Paramount Closed Its $110bn Warner Deal. In September, AI Answers Saw Six Brands, Not One.
In September 2026, the month before Paramount closed its acquisition of Warner Bros. Discovery, six of its streaming brands together held about 21% of brand mentions on ChatGPT and Google AI Overviews.
In September 2026, the month before Paramount closed its acquisition of Warner Bros. Discovery, Paramount+, HBO, Max, HBO Max, Pluto TV and Discovery+ together held 21.35% of brand mentions on ChatGPT and 21.11% on Google AI Overviews, measured across thirteen streaming brands. Second to Netflix on both. Three of those six are HBO-related brand names, and the two engines rank them differently: ChatGPT mentions HBO most often, Google AI Overviews mentions Max most often.
What this measures: BrightEdge AI Hyper Cube data with share of brand mentions inside AI answers, calculated as each brand's mentions divided by total mentions across the top thirteen streaming brands measured, in the United States, on ChatGPT and Google AI Overviews. It does not measure clicks, traffic, subscribers or revenue. See Technical Methodology.
The AI visibility position Skydance inherited
Skydance has a potential brand problem through its acquisition of Warner Bros. Discovery, which closed on 6 October 2026. The deal brings together a streaming portfolio with some naming consistency issues.
| Brand | ChatGPT | Google AI Overviews |
| Netflix | 27.93% | 28.23% |
| The six combined | 21.35% | 21.11% |
| Apple TV | 14.67% | 11.55% |
| Hulu | 12.27% | 11.70% |
| Disney+ | 7.87% | 7.95% |
Table 1. Share of brand mentions across thirteen streaming brands, September 2026, United States. The six are Paramount+, HBO, Max, HBO Max, Pluto TV and Discovery+. Source: BrightEdge AI Hyper Cube.
Netflix leads the six combined by 6.58 points on ChatGPT and 7.12 points on Google AI Overviews. Skydance, read as one portfolio, is a clear second. But read as the engines actually report it, it is six separate brand names, none of which reaches 7%.
Three HBO-related names, two engines that rank them differently
Three of the six are HBO-related brand names: HBO, Max and HBO Max. HBO is a channel and a programming brand as well as a streaming label, so the engines may be answering about different things under each name. What the data shows is which name each engine uses.
| Label | ChatGPT | Google AI Overviews |
| HBO | 5.52% | 4.70% |
| Max | 3.11% | 5.05% |
| HBO Max | 3.47% | 2.33% |
Table 2. Share of brand mentions for the three HBO-related names, September 2026, United States. Source: BrightEdge AI Hyper Cube.
ChatGPT mentions HBO most often, at 1.59 times the next of the three. Google AI Overviews mentions Max most often, at 1.07 times. Neither engine collapses the three into one, and the two do not agree on which name they reach for.
Older brand names can remain prominent well after a rebrand. HBO Max launched in 2020, was renamed Max in 2023 to signal a broader mix of programming, and went back to HBO Max in July 2025. For HBO Max, our September data shows that the former Max name continues to appear frequently in AI answers: more than a year after the name returned, Google AI Overviews still mentions Max more than HBO Max, and ChatGPT has the two at near parity.
Skydance should consider this learning as it looks at consolidating further. Tracking the same three names through a branding change is what would show how visibility moves. This research does not establish what any one name would be worth after such a change.
Much like TV ratings, live events dominate AI conversations
| Prompt category | ChatGPT | Google AI Overviews |
| Live events | 65% | 73% |
| Where to watch a title | 15% | 22% |
| Ownership questions | Under 1% | Under 1% |
Table 3. Share of top-prompt volume by category, September 2026. Prompt-mix analysis by BrightEdge Professional Services on the top 60 to 100 prompts by estimated volume per engine, categorized by keyword rules. Read as indicative.
Among the top prompts analyzed by estimated volume, live events (prompts like "What channel is the F1 race on today?") lead on both engines, followed by where to watch (prompts like "Where to watch Euphoria"). Despite the big news surrounding the acquisition, ownership questions were rarely seen, accounting for under 1%. These shares describe that sample rather than every question put to either engine.
What We Analyzed
BrightEdge measured brand mentions across thirteen streaming brands in AI answers on ChatGPT and Google AI Overviews, in the United States, for September 2026. No prompt filter was applied. The six Paramount and Warner Bros. Discovery streaming brands were then compared against each other and against the rest of the field, and the three HBO-family labels were compared separately on each engine.
Data Collected
| Field | Value |
| Source | BrightEdge AI Hyper Cube |
| Engines | ChatGPT and Google AI Overviews |
| Brand set | Thirteen streaming brands, including Netflix, Apple TV, Hulu, Disney+ and the six Paramount and Warner names |
| Market | United States |
| Period | September 2026 |
| Metrics | Share of brand mentions within the set |
| Prompt filter | None |
| Prompt-mix sample | Table 3 comes from the top 60 to 100 prompts by estimated volume per engine, not from all prompts |
| Not disclosed | Mention counts and prompt counts. BrightEdge publishes shares and ratios, not sample sizes |
Key Finding
Measured. The six brands together held 21.35% of brand mentions on ChatGPT and 21.11% on Google AI Overviews, second to Netflix on both. Within the HBO family, ChatGPT ranked HBO first at 5.52%, HBO Max second at 3.47% and Max third at 3.11%. Google AI Overviews ranked Max first at 5.05%, HBO second at 4.70% and HBO Max third at 2.33%.
Inferred. Brands are complicated and persistent. A company answering to several brand names is treated as several brands by both engines, and an older name can stay prominent well after a rebrand. More than a year after HBO Max returned to its original name, Google AI Overviews still mentions Max more frequently. That shows why marketers need to track both current and former brand names. It is not a finding about HBO specifically, and we were unable to identify a clear reason why one would be captured vs. the other, nor how persistent these kinds of discussions are.
How that affects your measurement
Share of mentions is calculated per brand name. An engine that answers with "Max" records a mention for Max, and an engine that answers with "HBO" records one for HBO. Nothing joins them without coordinating brands and sub-brands.
That has two consequences for any company with more than one name.
Each name is measured separately, so a dashboard filtered to one of them shows part of the position rather than all of it. The three HBO-related names individually range from 2.33% to 5.52%; together they are 12.10% on ChatGPT and 12.08% on Google AI Overviews.
The sum is a valid figure, and it answers a specific question. Because the metric counts mention instances, adding the shares gives the group's share of all mention instances across the thirteen brands. It is not the share of prompts in which at least one of those names appears.
What Marketers Need to Know
Use brand grouping to create a consistent definition of who your brand is. A short name, a legal name and a product name are three brands to an AI engine. Create a standard definition of a Grouped Brand to represent all your brand names.
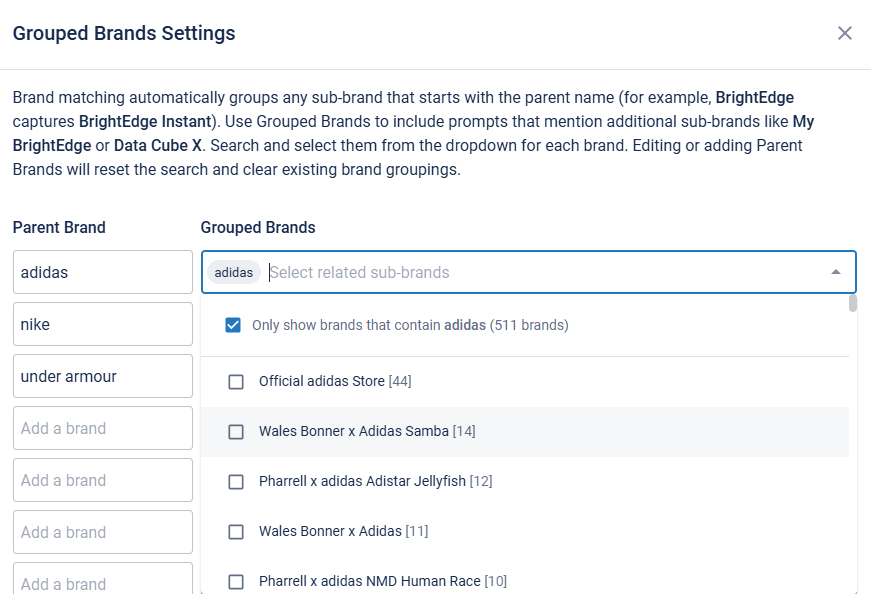
Grouped Brands Settings in BrightEdge AI Catalyst. Brand matching groups any sub-brand that starts with the parent name, and additional sub-brands are selected per parent brand so that every name a company answers to is measured as one.
Compare the engines against each other. ChatGPT and Google AI Overviews ranked the same three names differently here. A reading taken from one engine is half the picture.
Record the baseline before any branding change. A rename, a merge or a retirement can only be assessed against a measured starting position. Put the current names on record first, then track the same set through the change.
Work on the questions that carry the volume. Among the top prompts analyzed by estimated volume, live events lead on both engines. An evergreen how-to-watch page answering time, channel and stream covers the largest category in that sample.
Technical Methodology
| Field | Value |
| Capability | BrightEdge AI Hyper Cube, brand mention comparison |
| Engines | ChatGPT and Google AI Overviews |
| Window | September 2026, monthly cadence. One month, read as a snapshot rather than a trend |
| Market | United States only |
| Prompt filter | None. An earlier working cut excluded prompts containing a brand name by substring, which also drops every prompt containing "max" and therefore undercounts Max. That filter was not applied here |
| Brand set | Thirteen streaming brands. Share figures are relative to this set and change if the set changes |
| Share metric | percent_of_mentions, a brand's mentions divided by total mentions across the measured set |
| Metric not used | share_of_mentions in the same response is volume-weighted, being a brand's share of the search volume associated with the prompts where it was mentioned. It is a different measure and is not reported in this edition |
| Combined figure | The 21.35% and 21.11% totals add six individual shares. Because the metric counts mention instances, the sum is the six brands' share of all mention instances across the thirteen. It is not the share of prompts in which at least one of the six appears. That is a different metric with a different denominator, requiring prompt-level deduplication, and it is not reported here |
| Timing | AI Hyper Cube monthly coverage runs to September 2026. Every figure predates the 6 October 2026 close |
| Prompt mix | Categories in Table 3 come from BrightEdge Professional Services analysis of the top 60 to 100 prompts by estimated volume per engine, categorized by keyword rules. The shares describe that sample, not every question put to either engine. Single large prompts can move the mix. Indicative only |
| Not measured | Clicks, sessions, subscribers, revenue. Why any brand was mentioned. Customer sentiment. What any name would be worth after a branding change. Any engine other than ChatGPT and Google AI Overviews. Any market outside the United States |
| Brand name history | HBO Max launched in 2020, was renamed Max in 2023 and returned to HBO Max in July 2025. Source: Warner Bros. Discovery, Variety and The Hollywood Reporter, May and July 2025 |
| Company naming | Paramount Skydance acquired Warner Bros. Discovery, and the combined company is named Skydance. Source: CNBC and Variety, October 2026 |
| Deal facts | Axios, 6 October 2026 |
What Is Still Open
How Skydance handles the merger remains to be seen. The earlier Warner Bros.-Discovery merger left many brand names in place. With three major streaming platforms (HBO Max, Paramount+ and Discovery+) and new leadership, branding decisions, as we have shown, can have long-running implications for how you show up in AI.
- Whether the position moves after the close, which only post-merger data can show.
- Whether the engine disagreement holds. One month on two engines in one market is a snapshot. A second month would show whether ChatGPT's preference for HBO and Google AI Overviews' preference for Max are stable.
- Whether the conversation mix holds. The prompt-mix categories come from a single month's top prompts and have not been reproduced independently.
Key Takeaways
| Finding | Supporting evidence |
| AI answers saw six brands, not one company | Paramount+, HBO, Max, HBO Max, Pluto TV and Discovery+ measured separately on both engines |
| Together they ranked second to Netflix | 21.35% on ChatGPT and 21.11% on Google AI Overviews, against Netflix at 27.93% and 28.23% |
| Three of the six are HBO-related names | HBO, Max and HBO Max are measured as three separate brands by both engines |
| The engines reach for different ones | ChatGPT mentions HBO most often at 1.59x the next of the three; Google AI Overviews mentions Max most often at 1.07x |
| An older name can stay prominent after a rebrand | Max returned to the HBO Max name in July 2025, and Google AI Overviews still mentions Max more often |
| September is a baseline, not a forecast | The figures show where each name stands before the close, and a branding change would need the same names tracked through it |
| Ownership questions are a small share of the volume analyzed | Under 1% on both engines, among the top prompts by estimated volume |
Frequently Asked Questions
Which streaming brands are the biggest in AI?
Across thirteen streaming brands in the United States, Netflix led on both engines, at 27.93% of brand mentions on ChatGPT and 28.23% on Google AI Overviews. The six Paramount and Warner Bros. Discovery names together held 21.35% and 21.11%, ahead of Apple TV, Hulu and Disney+.
Do ChatGPT and Google AI Overviews treat HBO, Max and HBO Max as the same brand?
Neither does. Both engines record a mention against the specific name used, so the three are measured as three brands. The engines also reach for different ones: ChatGPT mentions HBO most often, at 1.59 times the next of the three, while Google AI Overviews mentions Max most often, at 1.07 times. HBO is also a channel and a programming brand, not only a streaming label, so the three are related names rather than interchangeable ones.
How often does Google AI Overviews mention Max versus HBO Max after the rebrand?
In September 2026, Google AI Overviews mentioned Max in 5.05% of brand mentions across thirteen streaming brands, against 2.33% for HBO Max. The service had returned to the HBO Max name in July 2025, more than a year earlier. ChatGPT had the two closer together, at 3.11% for Max and 3.47% for HBO Max. This research records that the older name is still in use on both engines. It does not establish why, and a single month cannot show how long a name change generally takes to register.
How should a merged company measure AI visibility through a brand name change?
Record the position of every name involved before the change, on each engine, then measure the same set afterwards. This research is an example of the first half: September 2026 positions for all six names, on ChatGPT and Google AI Overviews, taken before the deal closed. It does not forecast what any name would be worth after a change, and no measurement taken before one can.
Does this research measure the effect of the Paramount and Warner Bros. Discovery merger?
No. Every figure is September 2026 and the deal closed on 6 October 2026, so this describes the position Skydance inherited. October data is not yet available. The first post-merger read is the one that can show movement.
What do people ask AI about streaming services, among the highest-volume prompts?
Among the top 60 to 100 prompts by estimated volume on each engine, live events lead at 65% on ChatGPT and 73% on Google AI Overviews. Where to watch a specific title follows at 15% and 22%. Questions about who owns which service account for under 1% on both. These shares describe that sample rather than every question put to either engine.
What does share of brand mentions measure, and what does it not?
It is a brand's mentions divided by total mentions across the brands measured, inside AI answers. It does not measure clicks, traffic, subscribers or revenue, it does not establish why a brand was mentioned, and it does not predict what a name would be worth after a branding change. It depends on the brand set chosen, so a different set gives different shares.
Source: BrightEdge AI Hyper Cube. Share of brand mentions across thirteen streaming brands, United States, September 2026, on ChatGPT and Google AI Overviews. Deal facts from Axios, 6 October 2026. Brand name history from Variety and The Hollywood Reporter.
More from this series
See the rest of the Weekly AI & Search Insights series.
Google's Product Grid Disappeared in 14 European Markets: What Retailers Need to Check
On 16 September 2026 Product Grid listings stopped appearing in all 14 EEA markets BrightEdge tracks, and a Comparison Sites section began appearing in the same markets on the same day.
On 16 September 2026, Product Grid listings stopped appearing in all 14 EEA markets BrightEdge tracks. A Comparison Sites section began appearing in the same markets on the same day. In the EEA a retailer's free product listings run through one comparison shopping service. Google Shopping appeared in the new section 16 to 35 times as often as the next-largest service. That is across Germany, France, Spain and Italy, on tracked queries from 9 to 29 September.
Which service represents your domain is quick to establish. It sits in the Merchant Center CSS dashboard, it costs nothing to check, and it decides which service places your free listings. Feed quality and your relationships with third-party catalogs sit alongside it.
What this measures: This counts how many tracked keywords display each section. It does not show whether a given merchant's products appear inside it, and it does not measure clicks. The markets are the 14 EEA markets BrightEdge tracks, which are 13 EU countries plus Norway. Other EEA markets exist and were not measured.
The switch happened on one day, in every tracked market
Product Grid listings stopped appearing in all 14 tracked EEA markets after 15 September. The Comparison Sites section began on 16 September, the same day in every one of them. Product Grid stayed flat throughout in the UK, US, Canada and Australia, which sit outside the change.
Google removed the grid to comply with a European Commission ruling of 23 July 2026 under the Digital Markets Act. The ruling found that Google favored its own shopping, hotel, transport and sports results, and fined it EUR 460 million. Reuters reported a 60-day compliance window, and the September change landed inside it.
Google disagrees with the ruling. The change is a compliance step. Compliance does not establish that this particular layout has to remain, so treat the current arrangement as the position in the measured window.
One setting decides which service places your free listings
In the EEA, one comparison shopping service represents a merchant domain for free product listings. Google documents this per domain. Several services can be used for paid campaigns, and one carries the free listings. This rule predates the September change. What changed on 16 September is the place those listings appear.
Google Shopping appeared in the Comparison Sites section 16 to 35 times as often as the next-largest service. That is across Germany, France, Spain and Italy, on tracked queries from 9 to 29 September 2026. 71% of Comparison Sites appearances landed in result positions one to four, from 61% in France to 76% in Spain and Italy. It is premium space.
What the multiple counts. The 16 to 35 times comparison measures how often each service appears in the section. It does not measure an individual merchant's product visibility or performance. BrightEdge has not tested what changes when a merchant switches service. Google Shopping led the section across those three weeks. Read your own selection before deciding whether to change it.
Confirm which CSS represents your domain, resolve related disapprovals, and check whether priority products appear.
Where the selection does not match the destination, Merchant Center disapproves the products with the message "CSS not selected for this destination". Resolve the CSS mismatch, then check for any remaining eligibility issues.
Merchant Center and third-party catalogs provide separate routes into the section
| Route | Fed by | Your lever |
| Google Shopping box | Merchant Center feed, product and offer schema, page content | Feed quality, and which CSS represents your domain for free listings |
| Third-party service boxes | Each service's own catalog, fed by direct feeds, affiliate networks or feed partners | Presence and data accuracy in each service's catalog |
Coverage figures cover 1 September to 13 October 2026. Share and position figures cover 9 to 29 September 2026. Routes by which a product can appear in the Comparison Sites section. Source: BrightEdge Professional Services, with CSS mechanics from Google Merchant Center documentation.
Third-party comparison services use their own product catalogs, separate from Merchant Center. Retailers should check which services carry their products and whether the information is accurate.
Google Shopping appeared substantially more often than other services during the period measured. The section exists to give third-party services comparable prominence. Monitor changes in service appearances alongside your own product coverage.
Coverage returned to its previous level by 30 September
On 16 September, the number of tracked keywords showing a Comparison Sites section was 38% below the previous Product Grid baseline. Coverage increased through the remainder of September and matched the previous baseline on 30 September. The baseline is 53,035 keywords, day one counted 32,771, and 30 September counted 53,227.
Since 3 October, the combined count has remained 3% to 8% above that baseline.
These figures measure how often a product section appeared in tracked search results. They do not establish whether individual retailers retained their visibility or traffic. Changes in how the new section was collected may also have affected the early trend.
Markets did not move together
| Market | Day one | Index level, with the date of that reading |
| Germany | Fell to about half its old count | 108% to 111% of baseline on 3 October |
| Italy | Deep day-one drop | 108% to 111% of baseline on 3 October |
| Spain | Deep day-one drop | 108% to 111% of baseline on 3 October |
| Poland | Dipped less | At baseline on 13 October |
| Finland | Smaller early hit | About 14% below baseline on 13 October |
| Norway | Smaller early hit | About 6% below baseline on 13 October |
Selected markets, indexed to each market's own Product Grid average for 10 to 14 September. Source: BrightEdge Professional Services, 1 September to 13 October 2026. The six shown are the clearest examples of each pattern. The other eight tracked markets mostly follow the large-market or Poland shape.
Germany, Italy and Spain took the deepest day-one hits and recovered slowest, then sat above their old baselines on 3 October. Finland and Norway took smaller early hits and missed the 30 September step.
Finland and Norway remained below baseline on 13 October, the last day of the window. Both are small markets where a few dozen keywords move the index, so neither reading is a reliable guide alone.
What to do before the holiday peak
- Establish which CSS represents each merchant domain for free listings. Confirm the service, resolve eligibility issues, and assess that choice against your own product visibility. A market-wide share does not answer it.
- Annotate 16 September in European product reporting. The grid and the Comparison Sites section are different layouts, so measures either side are not like for like. Mark the date, report layout-specific measures separately, and keep the earlier history.
- Establish which third-party services carry your priority products, market by market. Those boxes fill from each service's own catalog. Record the service, the feed behind it, and whether the product data is accurate. Order the work by which markets carry your peak trading. The recovery index does not tell you where your catalog gaps are.
- Make the feed, the page and the structured data agree. Product information may appear across Google Shopping, third-party catalogs and AI shopping experiences. Match titles, prices, availability and identifiers across all of them.
- Compare clicks either side of 16 September. Compare product-page and non-product-page clicks before and after the change.
Start by checking CSS setup and product eligibility. Then prioritize the markets and products that matter most for holiday trading. Building coverage across third-party catalogs is slower, and how far up the list it belongs depends on which markets and products carry your peak.
Related check: product-page accessibility
Product-page accessibility is a related readiness check, and it sits outside the research above.
Crawlers vary in whether and when they execute JavaScript, and several AI crawlers fetch raw HTML without rendering it. Content that appears only after client-side rendering may be missed, so serve price, variants, availability and reviews in the page code itself.
Test this on your own pages. An industry average does not tell you which of your templates fail. Crawl a sample of product pages with JavaScript disabled and compare what appears with the browser view. Then check server logs for which crawlers fetched the full product content.
How to check this for your own site
Before you compare anything, note what changed in the reports. From the week of 27 September 2026, BrightEdge platform Product Grid reports reflect the new layout. Grid title, grid rank, product count and seller count can shift for reasons unrelated to SEO performance.
Find the keywords that lost a grid listing. In BrightEdge Product Grid reporting, pull the EEA keywords where your products appeared in the grid before 16 September, by market. Those are the keywords to follow through the switch.
Compare by market, with 16 September annotated. In Data Cube X and Product Grid reporting, compare keyword counts by listing type for your domain on either side of 16 September. Index each market to its 10 to 14 September average, as this edition does.
Compare clicks across the switch. In GSC Reporting, compare clicks to product pages and to non-product pages for your EEA markets before and after 16 September.
Frequently asked questions
What is the Comparison Sites section?
A section Google began showing on 16 September 2026, observed in the 14 EEA markets BrightEdge tracks, where comparison shopping services list products. Google Shopping, Google's own service, is one of them. It replaced the free product grid.
What is a comparison shopping service?
A service that places products in Google results in Europe, such as Google Shopping, idealo or billiger.de. A retailer selects one for its free listings.
Is the product grid gone everywhere?
No. The 14 EEA markets BrightEdge tracks all switched on 16 September. The UK, US, Canada and Australia kept the grid throughout the window.
Which markets did BrightEdge measure?
Austria, Belgium, Czechia, Denmark, Finland, France, Germany, Greece, Italy, the Netherlands, Norway, Poland, Spain and Sweden. These are 13 EU countries plus Norway. Other EEA markets exist and were not measured, so this edition does not describe them. Share and position figures cover Germany, France, Spain and Italy.
Which comparison shopping service should I select?
This research does not answer that. Google Shopping appeared 16 to 35 times as often as the next-largest service. That is across Germany, France, Spain and Italy, from 9 to 29 September 2026. That figure measures how often each service shows up in the section. It does not measure how a merchant's products perform inside it, and BrightEdge has not tested what changes when a merchant switches service. Start by reading which service represents your domain.
Did EEA traffic drop when the grid was removed?
This edition measures visibility and does not measure clicks, so it cannot answer that. Compare clicks to your product pages and to your non-product pages either side of 16 September in your own reporting.
Are merchants keeping their visibility?
The counts cannot answer that. Keyword coverage of the Comparison Sites section matched the old Product Grid level by 30 September. The counts show how many keywords display the section. Whether a given merchant's products appear inside it is a different question. That depends on your CSS selection and on the feeds third-party services ingest.
Is the grid coming back?
Unknown. The change is a compliance step and Google disagrees with the ruling. Compliance with the decision does not establish that this particular layout has to remain.
Technical methodology
| Field | Value |
| Source | BrightEdge Professional Services Total Search Visibility daily collection on a tracked product query set |
| Window | 1 September to 13 October 2026, daily |
| Markets | The 14 EEA markets BrightEdge tracks, being 13 EU countries plus Norway. The UK, US, Canada and Australia serve as non-EEA comparisons and Product Grid stayed flat in all four |
| Metric | Distinct keywords per day, per market, showing a Product Grid through 15 September or a Comparison Sites section from 16 September. The combined series sums the 14 markets, so a keyword tracked in more than one market counts once in each |
| Baseline | Each market's Product Grid average for 10 to 14 September is set to 100, and the combined baseline is 53,035 keywords. 10 September is the start because Austria, Belgium and Czechia expanded their tracked sets that day |
| Transition days | Combined Product Grid keywords fell about 8% on 15 September, before the first Comparison Sites row appeared. This edition dates the switch to 16 September |
| Share and position | Google Shopping's multiple is its appearances in the section divided by the next-largest service's appearances. Tracked queries in Germany, France, Spain and Italy, 9 to 29 September 2026. This is a narrower window than the daily coverage collection, which runs 1 September to 13 October 2026 |
| Known alternative explanation | The 30 September step hit the largest markets together and row counts moved unevenly across markets. A classification change on the collection side has not been ruled out |
| Not measured | Clicks, revenue and AI surfaces. Whether the same keywords appear on both sides of the switch. Whether any individual merchant's products appear in the section. Whether selecting a different comparison shopping service changes a merchant's visibility |
| Context | The 23 July 2026 ruling and the 60-day compliance window come from public coverage |
Key takeaways
| Finding | Supporting evidence |
| One service represents your domain for free listings, and it is yours to read and change | One CSS carries free listings in the EEA. Google Shopping appeared 16 to 35 times as often as the next-largest service in Germany, France, Spain and Italy, 9 to 29 September 2026 |
| The switch happened on a single day across every tracked market | Product Grid listings stopped and Comparison Sites began on 16 September 2026 in all 14 tracked EEA markets |
| The section is premium space | 71% of Comparison Sites appearances land in positions one to four, from 61% in France to 76% in Spain and Italy |
| Part of your product visibility runs through third-party catalogs | Third-party catalogs are supplied separately from Merchant Center, directly or through partners |
| Coverage returned to its previous level | 38% below baseline on 16 September, level with the 53,035 baseline on 30 September |
What is still open
Three questions would change this advice if they resolved differently.
- Whether the supplier unit, Google's separate section for direct sellers, appears on product queries at all. No capture in this collection shows it.
- How Google ranks the services inside the section. We have not located documentation.
- Where clicks from the section are reported in Search Console and Merchant Center. We have not located documentation.
More from this series
See the rest of the Weekly AI & Search Insights series.
For more on the grid removal and the Google Shopping lead, read EEA Product Grid Is Gone: Google Shopping Still Leads.
For the access and rendering checks behind machine-readable product pages, read our guide to AI agents.
BrightEdge tracks product visibility across search and AI surfaces. See how your products appear in the markets that changed with Data Cube X, or request a demo.
Google AI Overviews vs ChatGPT: Half of ChatGPT's Holiday Citations Point to Pages Marketing Does Not Own
Help and policy pages make up 12.5 times the share of citation weight on ChatGPT that they do on Google AI Overviews. Every retailer in the pull moves that way. Black Friday is 27 November.
This edition compares two AI surfaces, Google AI Overviews and ChatGPT, on holiday shopping prompts. We pulled the top 50 cited rows per retailer on each engine, across four major US retailers. Both engines were filtered to the same holiday terms. Then we pulled the prompts themselves.
What this measures: This measures which pages each engine cites as sources for holiday questions. It does not measure what the answers say, and it does not measure clicks. Citation weight counts page citations, so a prompt that cites two newsroom posts counts twice. Every share in this edition is a share of citation weight. A share of distinct prompts is a separate pull and would give different numbers.
Shoppers bring different questions to each surface
Half of ChatGPT's top holiday prompts are logistics questions. On Google AI Overviews, 28% are logistics questions and 72% are product and deal queries.
Google AI Overviews gets keyword strings such as black friday tv deals and store hours thanksgiving. ChatGPT gets full sentences such as Is the store open on Thanksgiving? and What time does Black Friday start?
The average ChatGPT holiday prompt runs 6.0 words against 4.4 on Google AI Overviews. A keyword product query is answered by a category page. A logistics question is answered by a press release or a help article.
Each engine receives different questions and cites different pages, so each needs its own measurement.
Each engine cites a different mix of page types
| Page type | Google AI Overviews | ChatGPT | Owner in a large retail organization | Higher share on |
| Commercial pages | 64.6% | 35.4% | Marketing and merchandising | Google AI Overviews 1.8x |
| On-site search results | 9.7% | 0.1% | Ecommerce platform | Google AI Overviews 91.1x |
| Newsroom posts | 17.2% | 40.7% | Communications | ChatGPT 2.4x |
| Buying and how-to guides | 7.5% | 12.9% | Marketing | ChatGPT 1.7x |
| Help and policy pages | 0.9% | 10.8% | Customer support | ChatGPT 12.5x |
Share of holiday citation weight by page type, Google AI Overviews against ChatGPT. Source: BrightEdge AI Hyper Cube. ChatGPT and Google AI Overviews, United States, June to August 2026. Four of six panel retailers, with both engines matched at the top 50 rows per domain, so both engines are compared at the same depth. Ratios use unrounded shares, so they differ slightly from ratios computed on the rounded values shown. Page owners are our characterization of a large retail organization. The shares are measured.
The last column names the engine with the higher share. ChatGPT gives more citation weight to newsroom posts, guides and help pages. Google AI Overviews gives more to commercial pages and on-site search results. Both engines cite all five types.
Commercial pages and on-site search results make up 74.4% of Google AI Overviews holiday citations and 35.5% of ChatGPT citations. Newsroom posts, guides and help pages make up 64.5% of ChatGPT citations and 25.6% of Google AI Overviews citations.
Two findings hold at every retailer in the pull. Commercial pages and on-site search results together run higher on Google AI Overviews for all four, by 10 to 53 percentage points. Help and policy pages run higher on ChatGPT for all four. The other three page types do not agree across all four. Those are panel averages, and the newsroom share on ChatGPT runs from 2% to 64%. Each retailer needs its own pull.
Pages owned outside marketing carry half of ChatGPT's holiday citations
In a large retail organization, marketing and merchandising own the commercial pages and guides. Those make up 72.1% of Google AI Overviews citations and 48.3% of ChatGPT citations. Communications and customer support own the newsroom and help pages, which make up 18.1% of Google AI Overviews citations and 51.5% of ChatGPT citations. On-site search results, owned by the ecommerce platform, make up the remaining 9.7% and 0.1%.
That changes who needs to be in the holiday planning meeting. On Google AI Overviews, updating the pages marketing owns covers most of the citations. On ChatGPT it covers about half.
Every retailer in the pull already has cited pages across at least four page types. Start by reviewing those cited pages for outdated information.
Example. Take an announcement post that carries last year's event date. If it is cited for the question of when a sale starts, anyone who opens it sees last year's date.
What this means for agentic commerce and AI shopping agents
These findings also matter for AI shopping agents. An agent needs four facts before it can buy: the sale date, the return window, the price-match terms and the shipping cutoff. Those four sit on newsroom posts and help pages, which carry 51.5% of ChatGPT's holiday citations.
The shopper typing a full sentence into ChatGPT today needs the same four facts an agent will need. Publishing them as pages a crawler can read gives both shoppers and AI systems more reliable information to work from.
On-site search results in Google AI Overviews call for a crawl and indexation check
Google AI Overviews cites retailers' own internal search result pages at 9.7% of its holiday citation weight. ChatGPT cites them at 0.1%. Two of the four retailers account for all of it, at 14.2% and 24.3%, and the other two show none. If a retailer's internal search pages appear in citations, the question for technical SEO is whether those pages should be crawled and indexed.
What to update before Black Friday
- Pull the cited-URL list for both engines. Group each list by directory and compare the two profiles. If they come back close to identical, check that the engine filter was applied before reading anything into the result.
- Share the ChatGPT list with the owners of those pages. The newsroom and help pages behind half of ChatGPT's citations sit with communications and customer support.
- Date every announcement and review last year's post. A cited announcement that carries last year's date shows that date to anyone who opens it. Sale start date, return window, price-match terms and shipping cutoff belong on pages a crawler can read.
- Update pages that already exist before commissioning new ones. Six weeks is a short window for new content to build visibility. Refreshing a page that is already live and already cited is the more practical priority.
- Plan around Google first and let the same page serve AI. Google still sends the traffic, so the commercial pages come first. They make up 64.6% of Google AI Overviews citations. Keep them current, then cover the newsroom, guide and help pages that make up 64.5% of ChatGPT citations.
How to check your holiday and agentic shopping visibility on both engines
Group the cited URLs by directory. In AI Hyper Cube, pull the cited-URL list for your holiday prompts and group it by directory. Each directory shows how much of the footprint comes from the newsroom, the help center and the guides.
Compare the two engines. Run the same pull on both and compare the two directory profiles. If they come back close to identical, confirm the engine filter was applied before acting on the result.
Size the organic footprint. Under the same question set, use Data Cube X to size the space before deciding how much to invest.
For the longer build program behind all of this, crawler access, product data and schema, see our guide to optimizing e-commerce for AI search.
Frequently asked questions
Does being cited mean I get the click?
This analysis does not measure clicks. It measures which pages are cited as sources.
Is this a share of prompts or a share of citations?
Citations. A prompt that cites two newsroom posts counts twice, so every share is a share of citation weight. A share of distinct prompts is a different pull and would give different numbers.
Should we stop investing in the Black Friday hub?
No. The hub sits inside the commercial pages that Google AI Overviews cites most, at 64.6%, and Google still sends the traffic. The finding is about which other page types carry the answer on ChatGPT.
How does this change what we do for agentic shopping?
It names the pages. An AI shopping agent needs the sale date, the return window, the price-match terms and the shipping cutoff. Those sit on newsroom and help pages, so those pages carry the agentic commerce work.
Why are the shares based on four retailers?
The page-type pull covers four of the six panel retailers, and the shares describe those four. They do not describe the other two.
Does this hold on other engines?
The pull covers ChatGPT and Google AI Overviews. Other engines are untested.
How current is this?
It reads June to August 2026. Holiday prompts run all year, so the pages cited in the summer are the pages already published going into November.
Technical methodology
| Field | Value |
| Data source | BrightEdge AI Hyper Cube |
| Engine | ChatGPT and Google AI Overviews |
| Market | United States, English |
| Period | June to August 2026 |
| Panel | Four of six panel retailers, pulled 14 October 2026 |
| Holiday prompts | Prompt text contains black friday, cyber monday, holiday, christmas or thanksgiving |
| Prompt mix | Top holiday prompts on each engine, grouped as logistics questions or product and deal queries, with average words per prompt |
| Metric | Citation weight. A prompt that cites two pages of a type counts twice, so every share is a share of citation weight. Shares of distinct prompts are not reported |
| Sampling | Top 50 rows per domain by BrightEdge Volume on each engine. Pages outside those rows are not counted, so every total is a floor |
| Classification | Page type assigned by URL pattern |
| Engine comparison | Same holiday term filter and same months on both engines, matched at the top 50 rows per domain. The prompt populations returned under that filter differ by engine, which is itself a finding of this edition. This is not an identical prompt panel run twice |
| Page ownership | BrightEdge characterization of which team owns each page type in a large retail organization. Ownership is not measured |
| What a citation means | A page was linked as a source. BrightEdge does not store ChatGPT's answer text, so answer accuracy is not measured |
| Buckets | Assigned from the URL alone: newsroom (corporate, news, press), guides (how-to and buying guides), help and policy, on-site search and commercial for everything else. Commercial includes category pages, product pages and event hubs. No hub-against-category judgment is used |
| Not included | Overall citation volume per engine, branded against unbranded prompts and pre-season growth multiples |
Key takeaways
| Finding | The number that proves it |
| Communications and customer support own the pages behind half of ChatGPT's citations | 51.5% of ChatGPT holiday citations against 18.1% on Google AI Overviews |
| The two engines cite different mixes of page types | Commercial pages and on-site search: 74.4% of Google AI Overviews citations and 35.5% of ChatGPT citations. Newsroom, guides and help pages: 64.5% of ChatGPT citations and 25.6% of Google AI Overviews citations |
| Help pages and on-site search show the widest gaps | Help and policy pages: 10.8% on ChatGPT against 0.9%, or 12.5x. On-site search: 9.7% on Google AI Overviews against 0.1%, or 91.1x, from two of four retailers |
| Two findings hold at every retailer | Commercial plus on-site search runs higher on Google AI Overviews for all four, by 10 to 53 points. Help and policy pages run higher on ChatGPT for all four. The other three page types do not agree across all four |
| The newsroom is the largest page type on ChatGPT | 40.7% of ChatGPT holiday citation weight, against 17.2% on Google AI Overviews |
| Google still sends the traffic, so commercial pages come first | Commercial pages hold 64.6% of Google AI Overviews citations |
More from this series
See the rest of the Weekly AI & Search Insights series. For the build side of the same problem, read our guide to optimizing e-commerce for AI search.
BrightEdge tracks which pages ChatGPT and Google AI Overviews cite for your brand. Find out which holiday pages each engine cites for you before Black Friday with AI Hyper Cube, or request a demo.
Before Black Friday, Update the Pages ChatGPT Already Cites
In this data, page age does not decide what ChatGPT cites. About 1 in 10 cited holiday pages carries a year that has already passed.
Dated press releases take 71.7% and 63.1% of Black Friday citations at the two retailers whose newsrooms carry the event. Their current store hubs take 10.5% and 13.3%. Nothing ages a page off the source list, so it stays there until someone updates it. The pages sit on the retailers' own sites, and Black Friday on 27 November leaves about seven weeks.
We went looking for stale pages in a long tail of neglect. At two retailers they are the most-cited Black Friday pages there are.
AEO and AI Overviews: An E-Commerce Optimization Guide covers what to build: crawler access, product data and schema, on a six-month runway. This edition covers what to update on pages that already exist, and that work fits in the seven weeks left.
We read holiday prompts that cite six major US retailers in AI Hyper Cube and checked which of the cited pages carry a year that has already passed.
What this measures. Every figure counts pages that ChatGPT linked as sources in the United States from June to August 2026. The newsroom, store hub and URL figures use August 2026 and each retailer's top 25 cited URLs. We do not store ChatGPT's answer text, so the data shows which pages it cites and says nothing about what it wrote.
ChatGPT answers an undated question with last year's announcement
9 of the 10 highest-volume prompts that cite a 2025 holiday announcement name no year. Someone asks when Black Friday starts, and ChatGPT answers with the announcement. Shoppers are sent to the announcement, so it is the page to keep current.
Where newsrooms carry Black Friday, press releases earn more citations than store hubs
At two of the retailers, newsroom posts take 71.7% and 63.1% of Black Friday citations and store hubs take 10.5% and 13.3%. A press release keeps one permanent address. A seasonal hub page gets retitled or replaced each year.
Citations split across many URLs
Every retailer in the analysis has at least 25 distinct Black Friday URLs cited. We read the top 25 per retailer, so these are minimums. Tracking-coded and email-campaign copies of the same hub show up as separate URLs, so one hub's citations spread across many URLs. Consolidating the copies puts them on one page.
A permanent hub and current guides keep dated pages under 5%
| Measure | Share of holiday prompts citing a dated page |
| All six retailers, weighted | 11.0% |
| Best Buy | 4.2% |
| Home Depot | 1.8% |
A dated page is one with a year from 2015 to 2025 in its URL. Source: BrightEdge AI Hyper Cube. ChatGPT, United States and English, June to August 2026.
- Best Buy. One permanent hub URL carries Black Friday every year. It holds 37.6% of Best Buy's Black Friday citations on its own and 63.0% with its variants. Its newsroom is cited only lightly for Black Friday. Its dated-page share is 4.2%. About a quarter of its Black Friday citations go to tracking-coded copies of the same hub, so consolidating those copies puts that share back on the hub.
- Home Depot. Its buying guides are current and detailed on specs, linked to collections with FAQ blocks, and its newsroom is cited mostly for current posts. Its dated-page share is 1.8%.
Black Friday pages are cited months before the event
ChatGPT cites Black Friday pages between June and August. We left out a growth multiple for that period, because part of the rise comes from prompts we added to the tracked set. The pages cited through the summer are likely the ones still cited in November. Nothing in this data suggests that age moves a page down the list. October is the time to update them, and a change made in the last week of November arrives late.
| Now | October | Last week of November | 27 November |
| Find the dated pages in your cited-URL list | Update cited pages that carry a past year and retitle evergreen pages | A change that lands here arrives late | Black Friday |
No retailer is a top source for gift-idea prompts
None of the six retailers is among the 15 most-cited sources for gift-idea prompts. Reddit, Good Housekeeping and Forbes lead that list. Where a gift prompt does cite a retailer, the page is a help page about receipts, registries or returns. No retailer holds a spot in that list, so a crawlable gift guide has room to earn one.
What marketers need to know
- Update cited pages that carry a past year, starting with newsroom posts. They take most Black Friday citations where a newsroom carries the event. Refresh each one or point it to this year's version.
- Keep one hub URL per event. Point the variants, tracking-coded copies and email-campaign URLs at one canonical hub.
- Retitle evergreen pages for the current year before October ends.
- Put this year's dates on the store hub. Add direct-answer FAQs for hours, early access, price matching and returns. A press release keeps its original date, so the hub is where this year's dates belong.
- Check holiday policy and help pages too. Gift-card help, coupons, price match, returns and store hours all get cited, so they need the same year check as the hub.
Google still sends the traffic. AI search is where the answer gets assembled before anyone clicks. Work both surfaces, starting with Google, because one canonical and current hub serves them together. These five updates fit in the seven weeks left. Build work needs a longer runway, so plan it for next season. Start with AEO and AI Overviews: An E-Commerce Optimization Guide. A crawlable gift guide belongs on that list.
How to check this for your own site
Find the dated pages. In AI Hyper Cube, pull the cited-URL list for your holiday prompts and sort it by URL. Any URL with a year that has passed goes on your work list.
Count the URLs for your biggest event. In the same list, count the distinct URLs for that event. If the same hub appears under more than one URL, consolidate before you create anything new.
Size the organic footprint. Use Data Cube X to size the organic footprint under the same question set, so you know how much to invest.
Frequently asked questions
Does this mean ChatGPT is giving shoppers wrong information?
The data shows which pages ChatGPT cites. A citation puts an older page on the source list, and whether the answer repeats its details is a separate check.
Which retailers does this cover?
Six major US retailers. We report the category and name only the two examples of current practice.
Should retailers stop publishing newsroom posts?
No. At two retailers, newsroom posts are among the pages ChatGPT cites most for Black Friday. The work is to keep each post current or point it to this year's version.
How was a dated page identified?
We looked for a year from 2015 to 2025 in the URL. A manual check found about 80% of matches genuinely dated, and the misses were email tracking codes carrying a year-like string. Pages that are old without carrying a year in the URL are not detected at all, so 11.0% is a floor.
Why is there no growth figure for pre-season citations?
Part of the rise comes from prompts added to the tracked set, so a multiple would overstate real growth.
Does this hold on other engines and for other retailers?
This covers six major US retailers on ChatGPT through August 2026. Other engines and other retailers are untested and worth checking separately.
How does this edition relate to AEO and AI Overviews: An E-Commerce Optimization Guide?
The guide covers what to build for AI search: crawler access, product data, schema and off-site signals, on a six-month runway. This edition covers what to update on pages already published, on a runway of about seven weeks. Run this audit first, because the pages are already published and already cited.
Technical methodology
| Field | Value |
| Data source | BrightEdge AI Hyper Cube |
| Engine | ChatGPT |
| Market | United States, English |
| Period | June to August 2026 |
| Panel | Six major US retailers, 13,915 holiday prompts |
| Holiday prompts | Prompt text contains black friday, cyber monday, holiday, christmas or thanksgiving |
| Fragmentation analysis | Black Friday prompts, August 2026, top 25 cited URLs per retailer, so URL counts are minimums |
| Gift prompts | Prompt text contains gift, excluding gift-card questions |
| Dated page test | URL contains a year from 2015 to 2025 in a date path or hyphenated name |
| Detection accuracy | A manual check found about 80% of matches genuinely dated, and the misses were email tracking codes carrying a year-like string. Pages that are old without carrying a year in the URL are not detected at all, so 11.0% is a floor. |
| What a citation means | A page was linked as a source. BrightEdge does not store ChatGPT's answer text, so answer accuracy is not measured |
| Counting | A prompt citing two retailers counts once for each |
| Newsroom share | The portion of a retailer's Black Friday citations, among its top 25 cited URLs, that goes to its newsroom posts |
| Weighted share | Each retailer's dated share weighted by its prompt volume, across 13,915 holiday prompts |
| Left out | Pre-season prompt growth multiples, because part of the rise comes from prompts added to the tracked set |
Key takeaways
| Finding | The number that backs it |
| AI citation shows no recency discount in this data | Dated press releases take five to seven times the citations of current store hubs |
| ChatGPT cites pages regardless of age | About 1 in 10 holiday prompts cites a page tied to a past year, 11.0% weighted across the six retailers |
| Shoppers ask without a year | 9 of the 10 highest-volume prompts citing a 2025 announcement name no year |
| Where newsrooms carry Black Friday, press releases earn more citations than store hubs | Newsroom posts 71.7% and 63.1%, store hubs 10.5% and 13.3% |
| One permanent hub holds citations together | Best Buy: 37.6% alone, 63.0% with variants |
| Current guides and hubs keep dated pages low | Home Depot 1.8%, Best Buy 4.2% |
| Citations split across many URLs | At least 25 distinct Black Friday URLs per retailer, as minimums |
| No retailer is a top source for gift-idea prompts | None of the six is among the 15 most-cited sources |
Download the full report
Get the full breakdown, or browse the rest of the Weekly AI & Search Insights series. For the build side of the same problem, read AEO and AI Overviews: An E-Commerce Optimization Guide.
BrightEdge tracks brand citations across ChatGPT, Google AI Overviews, Google AI Mode, Perplexity and Gemini. You can pull your own cited-URL list before the season starts in AI Hyper Cube, or request a demo.
Insurance AI Citations: ChatGPT Cites Insurers on Branded Questions Only
Government domains hold the definitional and coverage citations. Branded and HR questions are still open to insurers.
Government domains and clinical references hold every link on definitional and coverage questions in a tracked Insurance prompt panel. An insurer's own domain is the cited source in one question type out of four. Two of the four carry ownable ground.
Almost every insurance content calendar has a line on it like what is short-term disability insurance. Is that line worth the money? We stayed inside one vertical and asked one question: where is there ground an insurer can actually hold.
We took a tracked Insurance prompt panel, grouped it by what the question actually asks, and read the cited domains and the mentioned brands for each group in AI Hyper Cube and AI Catalyst. Four groups came out of it. An insurer's own domain is the cited source in exactly one of them: branded queries, where the customer has already typed the company name.
The map, and the verdict for each question type
Three different owners hold the citation set for unbranded insurance questions, and which one shows up depends entirely on what the question asks. The fourth group belongs to the brand.
| Question type | Who gets the link | Why | Verdict |
| Definitional and compliance | Government domains | Regulatory authority holds it | Hold for the mention |
| Drug and procedure coverage | Official and clinical references | Specialization, and narrowing further | Hold for the mention |
| Workplace and HR benefits | Job and HR platforms | No moat. Won on content quality | Invest. A real push |
| Branded and named queries | The brand's own domain | Nobody else can hold it | Defend. Best return |
All four question types in this panel are listed here. Scope is one tracked panel over these weeks. Source: BrightEdge AI Hyper Cube and AI Catalyst. A tracked Insurance prompt panel, ChatGPT and Google AI Overviews, United States, one-month and 12-week comparisons to 20 September 2026.
Nobody is going to outrank the IRS on what a deductible is. That is not a content problem. No budget fixes it. The better question is where the ownable ground sits, and the data points at two places.
What we analyzed
We read two outcomes separately for the same prompts over the same weeks. A citation is the linked source under an answer. A mention is the brand named in the answer text. They are two different outcomes, counted separately, and they do not move together, which is why one visibility score hides the result.
Prompts were grouped by what the question asks. Definitional and compliance questions ask what something is or what the rules are. Workplace and HR benefits questions ask about retention, culture and employee cost. Drug and procedure coverage questions ask whether a specific treatment is covered. Branded questions name a company.
Data collected
| Field | Value |
| Capability | BrightEdge AI Hyper Cube and AI Catalyst |
| Engines | ChatGPT and Google AI Overviews |
| Vertical | Insurance |
| Panel | An anonymized panel of tracked Insurance prompts. Domains shown are the public sources appearing in AI answers. They do not identify the panel |
| Market | United States |
| Period | One-month and 12-week comparisons to 20 September 2026 |
| Metrics | Share of citations by domain, and mentioned-brand rank |
| Comparison basis | Same tracked prompts at both dates, absolute shares, never indexed |
Key finding
Measured. Definitional and compliance questions cannot be won, the what-is-a-deductible and what-does-the-law-require kind. Government domains hold 4 of the top 8 cited, up from a mixed pool of job sites, publishers and legal aggregators 12 weeks earlier. healthcare.gov rose from 19.2% to 40.4% of ChatGPT citations over one month. legalclarity.org fell from 8.8% to 3.4%. Both movements appear in the tracked panel and in a wider prompt set pulled for comparison.
Measured. ny.gov rose from 1.6% to 8.0% of citations on ChatGPT and from 23.6% to 29.3% on Google AI Overviews. This is the one movement in the analysis confirmed on both engines, which is why it carries the most weight here.
Measured. Branded questions run the other way entirely. When a query names the company, the company's own domain is the source cited. That held in every group checked, without exception.
Measured. Insurer domains hold a place in the mentioned top three for the vertical, alongside healthcare.gov and dol.gov, across the same weeks government domains take the citations.
We expected insurers to disappear from those two areas altogether. They did not: insurer domains hold a place in the mentioned top three in the same weeks government domains dominate the citation set, which means the link and the answer are two separate contests, and a brand can lose one while holding the other.
Inference, labeled as such. Tightly query-matched content in a closed question type appears to earn the mention even where it cannot earn the citation. The mention data is measured. The causal link to content is not, and it is the first thing to test.
Source: BrightEdge AI Hyper Cube and AI Catalyst. A tracked Insurance prompt panel, ChatGPT and Google AI Overviews, United States, one-month and 12-week comparisons to 20 September 2026.
Drug and procedure coverage is closing further
Drug and procedure coverage questions are the does-my-plan-cover-this-treatment kind. They moved further in the same direction over the month, and the split is clean enough to be worth staring at. Every domain gaining citation share is official or single-purpose. Every domain losing share is general-purpose consumer health content.
| Domain | Share of ChatGPT citations | Direction |
| drugs.com | 20.6% | Gaining |
| nih.gov | 19.1% | Gaining |
| medlineplus.gov | 6.5% | Gaining |
| fda.gov | 4.4% | Gaining |
| mayoclinic.org | 3.5% | Losing |
| clevelandclinic.org | 3.2% | Losing |
| healthline.com | 3.0% | Losing |
| goodrx.com | 2.0% | Losing |
| webmd.com | 1.4% | Losing |
These are the top movers in this panel, ranked within each direction. Scope is one tracked panel over these weeks. Source: BrightEdge AI Hyper Cube. A tracked Insurance prompt panel, ChatGPT, United States, one-month comparison to 20 September 2026.
No insurer appears among the top movers in either direction. That group is narrowing even for the non-insurers already inside it.
The one you already win: branded and named queries
Branded queries are already held and the work is defensive. The specific gap is content answering does [brand] cover [drug or procedure], in a format that answers the question directly on the brand's own site.
Winning here displaces nobody. Someone has already decided to ask about you, so the only job left is being the complete, well-structured answer when they arrive. That is a far smaller problem than out-authoring a federal agency. Treat it as defensive infrastructure and budget it that way.
One caution, because this is where budgets quietly leak. There is no observed spillover. Publishing more generic definitional content does not appear to build toward branded citations at all. The two draw from different source pools entirely.
The one worth buying into: workplace and HR questions
A separate cluster of prompts inside the same tracked group cites Indeed, Glassdoor, SHRM, Gallup, Workday, AIHR and BuiltIn. None of those domains overlap with the government cluster or the clinical cluster.
There is no regulatory moat here. Indeed and SHRM hold this ground because their content is good, which is the whole point: ground held on quality can be taken. For an insurer selling group or employee benefits, the HR lead searching retention benchmarks on a Tuesday afternoon is your buyer, one step before you normally meet them.
Competing here means publishing content that works as genuine HR guidance. Calculators, benchmarking data and retention research qualify. Product marketing carrying an HR label does not.
Where the weighting changes
The split holds across every question type checked in this panel, and the weighting does not. Definitional and compliance questions are the most closed, with 15 or more distinct government domains appearing across the group. Coverage questions are closing further. Workplace questions stay open on quality. Branded questions are held by the brand.
Which of the four dominates your prompt mix decides how hard to lean. Pull the split first. Setting a content budget without it is guessing with a spreadsheet open. This covers one vertical on a tracked Insurance prompt panel. Whether the same split by question type holds in other regulated categories is untested and worth checking separately.
What marketers need to know
- Audit branded coverage content first. Someone is typing does [brand] cover [drug] into ChatGPT while you read this, and when a query names the company, the company's own domain is what gets cited. Go and check whether that page exists on your site in a format a machine can lift. Best return, least risk, shortest list of excuses.
- Decide whether HR content is a business you want to be in. No regulatory moat sits behind it. You would be competing with Indeed, Glassdoor, SHRM and Gallup on content quality, which is winnable and expensive. Calculators, benchmarking data and retention research qualify. Product marketing with an HR label on it does not, and everyone can tell the difference.
- Measure mentions separately from citations. Insurer domains hold a place in the mentioned top three while government domains take 4 of the top 8 cited. Keep tightly matched content in those two and report it as mention share in AI Catalyst, separately from citation share.
- Stop budgeting generic content as AI-citation growth. Definitional content is up against regulatory authority. Coverage content is up against official health references sitting at 20.6% and 19.1%. An insurer closes neither gap. Keep the content, because it still earns organic traffic and on-site conversion, and move the line item out of the AI-citation column.
- Google is still the channel to plan around. The ny.gov movement shows up on Google AI Overviews as well as ChatGPT, which is the tell. The canonical, specific content that earns organic visibility is the same content that gets a brand named in an AI answer, so it is built once and works on both surfaces.
How to check this for your own category
Path one. In AI Hyper Cube, pull the cited-domain list for your tracked prompts and group it by what the question asks. The owner changes by group, and that grouping is the whole exercise.
Path two. In AI Catalyst, read mention share beside citation share for the same weeks. Where the two diverge is where a single visibility score is hiding a result.
Path three. For the organic footprint underneath the same question set, use Data Cube X to size the space before you decide how hard to lean.
Frequently asked questions
What changed in how AI answers unbranded insurance questions?
The cited sources consolidated toward official domains. Government domains now hold 4 of the top 8 cited in the vertical. healthcare.gov alone went from 19.2% to 40.4% of ChatGPT citations in a month.
Can an insurer win the citation for definitional questions?
Plan as though the answer is no. 15 or more distinct government domains appear across that question group, and every week of the last twelve moved further toward them.
What is the difference between a citation and a mention?
A citation is the linked source under an answer. A mention is the brand named in the answer text. They are two different outcomes, counted separately, and they do not move together.
Which question type is worth the investment?
Branded and named queries, where the brand's own domain is already the cited source, and workplace and HR questions, which have no regulatory moat and are won on content quality.
Is this specific to ChatGPT?
Most of it is measured on ChatGPT. The ny.gov movement appears on Google AI Overviews as well, from 23.6% to 29.3%.
Does this hold outside Insurance?
This covers one vertical on a tracked Insurance prompt panel. Whether the same split by question type holds in other regulated categories is untested and worth checking separately.
Technical methodology
| Field | Value |
| Data source | BrightEdge AI Hyper Cube and AI Catalyst |
| Engines | ChatGPT and Google AI Overviews |
| Vertical | Insurance, tracked non-branded and branded prompts |
| Market | United States |
| Period | One-month and 12-week comparisons to 20 September 2026 |
| Measurement | Share of citations by domain, and mentioned-brand rank, read separately |
| Grouping | Prompts grouped by what the question asks |
| Comparison basis | Same tracked prompts at both dates, absolute shares, never indexed |
| Corroboration | healthcare.gov, legalclarity.org and ny.gov each confirmed in two sources. ny.gov confirmed on both engines |
| Panel | An anonymized panel of tracked Insurance prompts. Domains shown are the public sources appearing in AI answers. They do not identify the panel |
| Anonymization | Shares and ranks only. No prompt counts and no panel sizes |
| Limits | One vertical on one tracked panel. Each engine is measured on its own prompt set, so engines are compared by direction only |
Key takeaways
| Finding | The number that proves it |
| An insurer's own domain is the cited source in one question type of four | Branded queries. The other three are held by government, job platforms and clinical references |
| Definitional questions are held by regulatory authority | Government domains hold 4 of the top 8 cited, up from a mixed pool over 12 weeks |
| The largest single domain shift is healthcare.gov | 19.2% to 40.4% of ChatGPT citations in one month |
| One government riser is confirmed on both engines | ny.gov 1.6% to 8.0% on ChatGPT, 23.6% to 29.3% on Google AI Overviews |
| Coverage questions are closing further | drugs.com 20.6% and nih.gov 19.1% gaining, webmd.com 1.4% losing |
| Brands stay in the answer text where they lose the link | Insurer domains in the mentioned top three alongside healthcare.gov and dol.gov |
| Google is still the channel to plan around | The same specific, authoritative content supports organic visibility and gives AI systems stronger material to name the brand |
Download the full report
Download the full breakdown, or see the rest of the Weekly AI & Search Insights series.
BrightEdge measures brand mentions and citations across ChatGPT, Google AI Overviews, Google AI Mode, Perplexity and Gemini. You can see which group your category's questions sit in before a competitor builds around it. Request a demo.
The B2B Tech Shortlist Is Tightening Where Buyers Start
ChatGPT named 28% fewer brands per answer in B2B Tech in September 2026 than it did in March. The decline concentrates at the top of the funnel.
BrightEdge referral data shows AI search volume still climbing. Against that, a shorter list of brands per answer means each named slot is worth more than it was six months ago.
This edition covers the B2B Tech vertical. The panel holds the same non-branded prompts constant across two dates six months apart. Movement in the numbers reflects how ChatGPT answers changed. What was asked stayed the same. Usage and answer quality can both climb while the named list gets shorter. Measured in AI Catalyst.
What brand mentions measure, and what they do not
Mentions per answer counts how many distinct brands ChatGPT names in a single response, averaged across the tracked prompt set for a funnel stage. It is not citation volume, and it is not market share. A single answer can name many brands or very few, so the count moves independently of how many sources get cited for the same answer.
Source: BrightEdge AI Catalyst. A fixed panel of tracked non-branded B2B Tech prompts, ChatGPT engine, held constant across 15 March 2026 and 13 September 2026.
| Term | Definition |
| Mentions per answer | The average number of distinct brands ChatGPT names in a single answer, for a given funnel stage. |
| Change | The difference in that average between the two dates. |
| Sum across brands | One answer can name several brands, so this counts how many brands appear alongside each other in a single answer, separate from any measure of exclusive market share. |
Where the list got shorter
Where a prompt sits in the buyer's journey now decides how short the list gets. The panel stayed fixed. The prompts stayed fixed. Only the answers changed. Every figure below covers prompts that held the same intent classification on both dates. On those prompts ChatGPT named 5.36 brands per answer in March against 3.87 in September, a 27.9% decline. The fall concentrates at the top of the funnel.
Figures are the fixed-cohort cut: every prompt that carried the same intent classification on both dates. Source: BrightEdge AI Catalyst. A fixed panel of tracked non-branded B2B Tech prompts, ChatGPT engine, held constant across 15 March 2026 and 13 September 2026.
Data collected
| Funnel stage | Mar-26 avg. brands/answer | Sep-26 avg. brands/answer | Change |
| All stages | 5.36 | 3.87 | -27.9% |
| Informational | 5.15 | 3.50 | -32.0% |
| Consideration | 8.21 | 6.39 | -22.1% |
| Transactional | 2.02 | 3.34 | Not read as a trend |
Post Purchase carries too few prompts to read as a trend and is excluded. Transactional is printed above and held out of the conclusions below, for the reason given in its own section.
| Field | Value |
| Capability | BrightEdge AI Catalyst |
| Engine | ChatGPT |
| Market | United States |
| Vertical | B2B Tech |
| Prompts | Tracked non-branded prompts only, matched exactly across both dates |
| Period | 15 March 2026 and 13 September 2026 |
| Metric | Mentions per answer, the count of distinct brands named in one response |
| Comparison basis | Same prompts both dates, absolute averages, never indexed |
| Anonymization | Shares and averages only. No prompt counts and no panel sizes |
The questions buyers start with got the most selective
Informational prompts are the broadest questions, such as what a technology is or how it works. They went from naming 5.15 brands per answer to 3.50, a 32.0% decline, the steepest fall of any stage.
Microsoft, Google, and Amazon lost the most ground, down 9.5, 6.7, and 6.4 points. A cluster of developer and data-infrastructure names lost ground alongside them: Apache, dbt, Snowflake, Elastic, and HashiCorp.
IBM gained the most, up 9.9 points. NIST.gov, TechTarget, FBI.gov, Cisco and FTC.gov gained too, so institutional and government sources moved up alongside a publisher. The expected publisher squeeze does not appear in this data.
Consideration became a shorter list
Consideration prompts are where someone is comparing named options, such as accounting software for a small business. They went from naming 8.21 brands per answer to 6.39, a 22.1% decline.
Google, Amazon, GitHub, Trend Micro, Apple, and GitLab lost the most ground, down 9.3, 6.1, 3.7, 3.3, 2.0, and 2.0 points.
Every brand gaining ground here is a single-purpose tool.
| Brand | March presence | September presence |
| Zoho | 8.5% | 12.8% |
| Wave Apps | 2.8% | 5.7% |
| SAP | 3.5% | 5.7% |
| Squareup | 2.8% | 5.0% |
| Malwarebytes | 1.4% | 4.3% |
| ProtonVPN | 2.1% | 4.3% |
| NordVPN | 2.1% | 4.3% |
| Kubernetes.io | 2.1% | 4.3% |
| ServiceNow | 1.4% | 3.5% |
| ClickUp | 1.4% | 3.5% |
| ESET | 0.7% | 2.8% |
| Terraform.io | Not present | 2.1% |
Why buying-intent prompts are held back
Transactional prompts are where someone is ready to buy. They moved differently over the same window. A third measurement point shows that movement reversing, so the stage is held out of this edition's conclusions until the full weekly series is in. Both figures are printed above, so the omission is visible.
Two dates can show a direction that a third date takes away. So we waited, and printed the figures anyway.
Everything else in this edition holds at every measurement point checked.
Mentions and citations do not always move together
The relationship between how many brands get named and how many sources get cited is not consistent across the funnel.
In Informational, citations per answer rose from 2.30 to 3.12 even as mentions fell. Fewer brands were named, and each was backed by more sources.
In Consideration, citations fell in step with mentions, from 5.70 to 3.25.
In Transactional, citations stayed close to flat, from 1.92 to 1.84, while mentions rose.
What marketers need to know
- Fight for the winnable Consideration prompts. Pull Consideration-intent prompts for your category in AI Catalyst or AI Hyper Cube, then check where you already show up. Every brand gaining ground here is a single-purpose tool. Find the use case your product owns, and build content that answers that exact question.
- Audit where you appear stage by stage. A single visibility score hides which stage you are missing from. Split your tracked prompts by intent and find the stage where you are absent, because being absent from a stage is a different fix from ranking low inside it.
- Hold your top-of-funnel investment. Awareness answers hold their value. They just got harder to win, and the goal there is now earning a place on a shorter list. Pull awareness prompts for your category in AI Catalyst. Identify one to three where you have a right to win but do not appear, then prioritize those.
- Google is still the channel to plan around. The canonical, specific content that earns organic visibility is also what gets a brand named in an AI answer. Build it once and it works on both. Re-run this funnel comparison quarterly, because funnel-stage presence keeps moving.
How to check this for your own brand
Path one. Open Mentions, filter to your tracked B2B Tech prompt groups, and split by funnel stage. Compare two dates six months apart to see whether your category shows the same shift. Do it in AI Catalyst.
Path two. In AI Hyper Cube, pull the mentioned-brand list for your category across funnel stages for the cross-engine, brand-anchored view.
One caveat. A category with very few Consideration or Transactional prompts will not show a clean trend either way. This check is most useful where your category has enough tracked prompts at each funnel stage to compare, as B2B Tech does here.
Frequently asked questions
What changed in how ChatGPT answers B2B Tech questions?
Over six months ChatGPT named fewer brands per answer, and the decline concentrated at the top of the funnel. Overall presence fell 27.9%, from 5.36 to 3.87 brands per answer.
Which funnel stage lost the most brand presence?
Informational, the broadest and earliest-stage questions, fell 32.0%, from 5.15 to 3.50 brands per answer.
What happened at the buying-intent stage?
Transactional moved differently and is not reported as a finding here. A third measurement point shows that movement reversing, so the stage is held until the full weekly series is complete.
Does this mean publishers are losing ground to owned content?
The data does not support it. TechTarget gained ground in Informational over the same period, and other major publishers stayed flat. That pattern does not carry a publisher-versus-owned-content story.
Is this specific to ChatGPT?
Yes. This measurement is ChatGPT only. Whether Google AI Overviews and AI Mode follow the same funnel-stage pattern is untested and worth checking separately.
How reliable is the funnel-stage classification?
About 15% of prompts were reclassified into a different intent stage between the two dates. Every figure in this edition uses the fixed cohort instead: only prompts that carried the same classification on both dates. Reclassification therefore cannot explain the result.
Technical methodology
Measurement: mentions per answer, the count of distinct brands named in a single ChatGPT response, averaged across the tracked prompt set for each funnel stage.
Panel: tracked non-branded B2B Tech prompts on the ChatGPT engine, matched exactly across 15 March 2026 and 13 September 2026. Every prompt is present in both periods.
Classification: each prompt is assigned a funnel stage by intent. About 15% of prompts were reclassified between the two dates. The headline figures use the fixed cohort, meaning only prompts that held the same stage on both dates.
Cross-check: the same comparison run across all prompts at each date's current classification gives a 25.1% overall decline, against 27.9% on the fixed cohort. Brand-level movements quoted here are computed on all prompts at each date.
Scope: ChatGPT only. Whether the same funnel-stage pattern holds on Google AI Overviews or AI Mode is untested. Google remains the larger channel and the one to plan around.
Key takeaways
| Finding | The number that proves it |
| ChatGPT names fewer brands per B2B Tech answer overall | 5.36 to 3.87 brands per answer, a 27.9% decline |
| The decline concentrates where buyers start | Informational fell 32.0%, Consideration fell 22.1% |
| Consideration's gainers are single-purpose tools | Zoho rose from 8.5% to 12.8% presence, the largest gain in that stage |
| Mention volume and citation volume do not move together | Informational citations rose from 2.30 to 3.12 per answer even as mentions fell |
| Government and standards sources gained, and so did one publisher | NIST.gov up 8.1 points, TechTarget up 6.9 points |
| Google is still the channel to plan around | The content that earns organic visibility is what gets a brand named in an AI answer |
Two Weeks After Reddit's ChatGPT Collapse: What Replaced It in Education
Reddit's citation presence in ChatGPT fell from 17.2% to zero across two weeks in August 2026. The fall itself was widely reported. What replaced Reddit in Education citations was not, and that is what this edition measures.
Nothing about the content changed. Reddit changed its robots.txt, and every citation gain built on being crawled went with it. A source that had answered one in six Education questions in ChatGPT stopped appearing.
This series has been tracking Reddit's presence in AI citations closely, including an edition on 13 August covering Reddit's rise in search visibility. What follows is what happened in the two weeks after.
Six domains moved into the space inside a week. Two of them were gone again by week 37. The two weeks after the collapse are the useful part, measured in AI Catalyst.
What citation presence measures, and what it does not
Citation presence is the share of tracked prompts that cite a domain at least once. It is not share of citation volume, and it is not market share. A single AI answer cites several domains, so presence figures across domains add up to more than 100%. Reading them as a pie will produce the wrong conclusion.
| What it is | What it is not | |
| Citation presence | Share of tracked prompts citing the domain at least once | Share of total citations made |
| Movement | Change in that share between weeks | Change in a domain's traffic or rank |
| Sum across domains | Exceeds 100%, because one answer cites several sources | A market-share table |
Source: BrightEdge AI Catalyst. ChatGPT only, a fixed weekly panel of tracked Education prompts, United States, July to September 2026.
The collapse, week by week
| Week | Dates | Education panel | Account-wide |
| W28-33 | Jul 6 - Aug 16 | 17.2% | 9.0% |
| W34 | Aug 17-23 | 3.3% | 4.5% |
| W35 | Aug 24-30 | 0.0% | 0.5% |
| W36 | Aug 31 - Sep 6 | 0.2% | 1.6% |
| W37 | Sep 7-13 | 0.0% | 0.1% |
Source: BrightEdge AI Catalyst. ChatGPT only, a fixed weekly panel of tracked Education prompts, United States, July to September 2026.
Presence held steady for six weeks, then fell 81% in a single week and reached zero the week after. The Education panel fell further than the account-wide measure. That is what you would expect in Education, where Reddit already sat near the top of the cited set.
What we analyzed
A fixed weekly panel of tracked Education prompts in ChatGPT, measured every week across the same prompts. Because the panel does not change, week-to-week movement reflects the engine's behavior. What was asked stayed the same.
Data collected
| Field | Value |
| Capability | BrightEdge AI Catalyst |
| Engine | ChatGPT |
| Panel | A fixed weekly set of tracked Education prompts |
| Market | United States |
| Period | Week 28 to week 37, 2026 |
| Metric | Citation presence, the share of tracked prompts citing a domain at least once |
| Comparison basis | Same prompts every week, absolute presence, never indexed |
| Corroboration | Timing match between the account-wide drop and the robots.txt change, detailed in the methodology |
Key finding
reddit.com citation presence in the Education panel fell from 17.2% to 3.3% to zero across two weeks in August 2026. Account-wide, the same measure fell from about 9% to 0.5%. The inflection lands in the same week Reddit's robots.txt change took effect.
The panel is fixed, so this corroborates the mechanism behind the drop. It does not prove it. What the data can show is the timing and the size of the drop, and both match when the robots.txt change took effect.
Reddit did not fall on its own
| Domain | Before | After |
| coursera.org | 25.4% | 6.0% |
| indeed.com | 22.8% | 7.6% |
| forbes.com | 18.3% | 4.5% |
| reddit.com | 17.2% | 0.0% |
| collegeboard.org | 12.9% | 3.1% |
Source: BrightEdge AI Catalyst. ChatGPT only, a fixed weekly panel of tracked Education prompts, United States, July to September 2026.
Community sources and general commercial publishers receded together. Coursera lost 19 points of presence, Indeed 15 and Forbes 14. Reading the event as a Reddit story alone misses that other sources fell in the same window.
What replaced them was narrower and more institutional. Government sites, a university, and professional associations moved into the top set in the same two weeks.
Not everything that moved in stayed in
| Domain | What happened |
| onetonline.org | Spiked +589% in the week of the collapse, receded by week 37 |
| careeronestop.org | Spiked +346% in the week of the collapse, receded by week 37 |
| state.gov | Entered and held position through week 37 |
| asu.edu | Entered and held position through week 37 |
| apa.org | Entered and held position through week 37 |
| aacnnursing.org | Entered and held position through week 37 |
Source: BrightEdge AI Catalyst. ChatGPT only, a fixed weekly panel of tracked Education prompts, United States, July to September 2026.
The two biggest immediate movers did not hold. The four that held are government, university and professional-association domains. So are the two that faded. onetonline.org and careeronestop.org are both Department of Labor properties. Some institutional sources held and others did not, so domain type alone does not explain durability. Anyone who rebuilt a strategy on the first week's leaderboard rebuilt it on noise.
One name in the new top set is a trap. bls.gov did not grow at all. It was already third before the collapse at 21.2% presence, and it became first because everything around it fell faster. Rising in a ranking and gaining presence are different events.
This was a ChatGPT-specific event
| Engine | Reddit citation movement, same window |
| ChatGPT | About 86% relative decline |
| Google AI Mode | About 31% decline |
| Google AI Overviews | About 11% decline |
Source: Promptwatch via Search Engine Journal, 19 August 2026; Forbes and Gizmodo, 20 August 2026.
A one-engine read would have told a marketer their Reddit strategy had failed everywhere. It had not. Google's surfaces declined gradually across the same window while ChatGPT fell off a cliff, which is why the cross-engine view matters before anyone acts.
Reddit carried a trait the model wanted
Reddit's high citation rate became a playbook of its own. Teams seeded threads in order to be cited and treated presence on the platform as the objective. The trait the model actually wanted was first-hand, specific, unpolished answers. That content already existed on Reddit.
When the channel closed, it closed through an access policy. Content quality was not the reason. Everything built on it disappeared inside two weeks, and no warning was available to anyone optimizing for it. Reddit-based visibility was never a durable asset.
Some of the domains that moved in held position through week 37 and some did not. Both of the domains that spiked and faded are Department of Labor properties, so institutional status alone does not explain which sources stayed.
Citation share earned through one platform's willingness to be crawled is rented. Visibility built on a third-party platform is exposed to that platform's access decisions. Build the underlying expertise and canonical content on a domain you control. Run one test against your top cited sources. Does the citation exist because of what you are, or because a platform currently allows it to be crawled.
What marketers need to know
One. Build the trait, not the placement. What the model rewarded on Reddit was first-hand, specific, unpolished detail. Replicating that on a domain you control takes original data, named practitioners, and direct experience. Publish the material only you have.
Two. Quick wins from one platform's indexing behavior are fragile, whoever the platform is. Ask whether your current AI citation gains would survive a crawler-policy change tomorrow, and assume you would get no notice.
Three. Wait for the second week before crowning a replacement. The biggest immediate movers here did not hold, and two institutional domains faded alongside them. One week of leaderboard movement is not a trend.
Four. Google is still the channel to plan around. The canonical, specific content that earns organic visibility is also easier for a model to recommend by name. Build it where no third party's access policy can remove it.
How to check this for your own brand
Path one. In AI Catalyst, open Citations, filter the domain to reddit.com and scope to your tracked prompt groups. Pull the weekly trend. A single snapshot will not show it. You are looking for a steady baseline followed by a sudden break. A slope will not produce that pattern.
Path two. In AI Hyper Cube, pull the cited-domain list for reddit.com across your category for the brand-anchored, cross-engine view. That is where you compare Google AI Overviews and AI Mode against ChatGPT.
Three things to look for. Whether your category's Reddit presence collapsed in the same week or whether this is specific to Education. Which domains gained presence in the same window, and whether they held into a second week or spiked and faded. Whether your brand already has a foothold in whatever filled the gap.
One caveat. A category where Reddit had a low baseline will not show a dramatic story. This check is most useful where Reddit already sat in the top three or top five cited domains, as it did here.
Frequently asked questions
What happened to Reddit citations on ChatGPT?
Reddit's presence in ChatGPT citations fell sharply in the second half of August 2026. Public trackers reported a fall from 3.8% to 0.5% of ChatGPT Search citations account-wide, an 86% relative decline (Source: Promptwatch via Search Engine Journal, 19 August 2026). The change is attributed to Reddit blocking crawler access through robots.txt.
When did it happen?
The break lands in the week of 17 August 2026, with presence reaching zero in the Education panel the following week.
What replaced Reddit in Education specifically?
Government, university and professional-association domains. state.gov, asu.edu, apa.org and aacnnursing.org entered the top set and held position. Two others, onetonline.org and careeronestop.org, spiked hardest at the moment of collapse and then receded.
Is this permanent?
Unknown. The outcome depends on an access decision. Content has nothing to do with it. The measurable point is that a policy change removed a source in two weeks, and that is the risk worth planning around.
Does this mean brands should stop trying to get cited on Reddit?
It means a Reddit citation should not be the objective. What made Reddit useful to the model was specific, first-hand detail, and that kind of detail is harder to manufacture on an owned domain. Replicating it takes original data, named practitioners, and direct experience.
Was Reddit's high citation rate ever a reliable quality signal?
It was a signal about access and content type. Reddit's own authority as a source never entered into it. That distinction is what the collapse made visible.
How can I check whether this happened in my own industry?
Follow the two paths in the section above. Pull the weekly trend in AI Catalyst and the cross-engine view in AI Hyper Cube.
Technical methodology
Measurement: citation presence, the share of tracked prompts citing a domain at least once. This is not share of citation volume. Presence across domains sums past 100% because one answer cites several sources.
Engine: ChatGPT. Market: United States. Period: week 28 to week 37, 2026. Panel: a fixed weekly set of tracked Education prompts, held constant so week-to-week movement reflects engine behavior.
The series is plotted as absolute presence and is never indexed to a baseline week. A short series indexed to one week makes every later movement a function of that week.
Attribution. The panel is fixed and cannot observe cause directly. The inflection lands in the same week Reddit's robots.txt change took effect. That timing supports the mechanism. It does not prove it.
Scope. One category, one engine, one account's tracked panel. Directional for Education. It is not a claim about every category, and the account-wide comparison is included so the reader can see the difference.
Every figure quoted anywhere in this edition is a share or a change in a share. We publish no raw citation counts and no panel sizes.
Key takeaways
| Finding | The number that proves it |
| Reddit's ChatGPT citations in Education collapsed to zero | 17.2% presence to 3.3% to zero across two weeks |
| An access change caused the drop, unrelated to content quality. | The break lands in the week the robots.txt block took effect |
| It was a ChatGPT-specific event | About 86% decline in ChatGPT against about 11% in AI Overviews |
| Reddit did not fall alone | Coursera 25.4% to 6.0%, Indeed 22.8% to 7.6%, Forbes 18.3% to 4.5% |
| Half the replacements did not hold | onetonline.org and careeronestop.org spiked, then receded by week 37 |
| Rank movement is not presence movement | bls.gov became first without growing, from 21.2% presence |
| Visibility on a third-party platform is exposed to that platform's access decisions | reddit.com fell from 17.2% presence to zero in two weeks through a robots.txt change, with no change to the content |
Google AI Mode Cites Itself 4.5x More Than AI Overviews. Your Brand Can Still Be Winning.
google.com accounts for 44.9% of AI Mode citations and 9.9% of AI Overviews citations, a 4.5x gap that has held for eight months.
Ask Google AI Mode for an American Airlines stock price and it answers with a ticker. Ask it for things to do in Orlando and it answers with a local panel. Neither answer reads like a list of links, because neither one is. Both are assembled out of surfaces Google already owns.
That construction shows up in the citation data as Google citing itself. Across a tracked prompt set in AI Hyper Cube, google.com accounts for 44.9% of the citations AI Mode makes. In AI Overviews the same measure is 9.9%.
What Google AI Mode is, and how it differs from AI Overviews
Google AI Mode is a conversational search surface. It answers a query in full rather than returning a ranked list of links. AI Overviews is the AI summary that sits above the classic results page. Both are Google. They construct an answer in different ways, and that difference is what this edition measures.
| Google AI Overviews | Google AI Mode | |
| What the user sees | A summary above a ranked list of links | A conversational answer, often built around a module |
| How the answer is assembled | Largely from outbound sources, cited individually | More often from Google's own rich-result surfaces |
| google.com as a share of citations, August 2026 | 9.9% | 44.9% |
| Same measure, January 2026 | 3% | 35% |
Source: BrightEdge Insights from AI Hyper Cube. A tracked prompt set covering consumer product and finance queries, United States, January to August 2026.
The gap is eight months old, not eight days
Google confirmed in August 2026 that it routes outbound search clicks through its own redirect layer. The timing is coincidental. In January 2026, before any of it, AI Mode was already citing google.com in 35% of its citations against 3% in AI Overviews. The spread was 32 points then. It is 35 points now.
A change confirmed in August does not explain a gap that was already 32 points wide in January. The direction is wrong for it too. Both surfaces have moved upward across the eight months, together.
The redirect layer applies to organic result links, which is a different measurement surface from an AI citation. BrightEdge tracks both, so a click routed through a redirect still resolves to the destination in Data Cube X rather than disappearing from the report.
What we analyzed
A BrightEdge tracked prompt set covering consumer product and finance queries, run against Google AI Mode and Google AI Overviews in the United States. For each engine we took google.com as a share of all citations that engine made, at four observation points between January and August 2026.
The measure is deliberately a share rather than a count. A count moves whenever prompt coverage moves, which makes any two periods incomparable. A share does not.
Data collected
| Observation point | Google AI Mode | Google AI Overviews | Spread, percentage points |
| January 2026 | 35% | 3% | 32 |
| June 2026 | 45% | 12% | 33 |
| July 2026 | 48% | 11% | 37 |
| August 2026 | 44.9% | 9.9% | 35.0 |
Source: BrightEdge Insights from AI Hyper Cube. google.com as a share of citations, United States.
Plotted as absolute share and never indexed to a baseline period. Indexing a short series to one observation point makes every later movement a function of where that point happened to sit.
Key finding
google.com accounts for 44.9% of Google AI Mode citations and 9.9% of Google AI Overviews citations, a multiple of 4.5x. The gap has held for eight months and widened slightly, from 32 points to 35. AI Mode is assembling more of its answers from rich-result surfaces Google owns. The citation record then reflects the surface, and the brand sits inside it.
What it looks like one prompt at a time
Four example prompts show how it looks in practice. These four are an illustration and not a sample. The measurement is the share figure above.
| Prompt | AI Mode, cited domains | AI Overviews, cited domains |
| "fruit snacks" | google.com | walmart.com, welchsfruitsnacks.com, wikipedia.org |
| "things to do in orlando" | google.com | visitorlando.com, tripadvisor.com, neverstoptraveling.com, makingmyownlane.com |
| "local restaurants" | google.com | reddit.com, hotels.com |
| "american airlines stock price" | google.com | robinhood.com, tradingview.com, marketbeat.com |
Source: BrightEdge Insights from AI Hyper Cube. United States, August 2026.
The stock row is the sharpest. On "american airlines stock price" AI Mode returns google.com and nothing else. AI Overviews returns robinhood.com, tradingview.com and marketbeat.com for the same question in the same week. One engine answers out of a ticker module. The other sends the reader to the sites that publish prices.
The pattern holds across all four. A retail query, a travel query, a local query, a finance query. On every one, AI Mode answers from a Google surface and AI Overviews cites outbound sources.
BrightEdge replicated each prompt to identify a set that returns consistently, because an AI Mode answer can vary between sessions. Every prompt in the stable set returned google.com on AI Mode, so the table shows no counter-example.
Assorted local blogs and restaurant sites also appeared on the local restaurants prompt and are not listed individually.
This is rich results, extended into the answer
Rich results are not new. Product grids, price comparison strips, stock tickers, fare and hotel modules and local packs have shaped the classic results page for years. A search-literate reader already knows them, already optimizes for them, and already measures them.
AI Mode extended those same surfaces into a conversational answer at a scale AI Overviews did not reach. That reframing matters because it changes the response. A new and opaque ranking behavior would leave a brand with nothing to do. An extension of rich results means the brand already has the checklist.
It concentrates where modules already carry the classic page. Product comparison and shopping queries, local discovery, and financial rate and price lookups.
Why eCommerce and Travel see this first
| Category | Existing rich-result footprint in classic Search | What that means in AI Mode |
| eCommerce | Product grids, price comparison, review stars, availability | The deepest module inventory to extend into. Highest chance a win is recorded as a module citation |
| Travel | Fare modules, hotel panels, date and price grids | Same shape as retail. Rates and availability sit in a module rather than on a page |
| Finance | Rate tables, stock tickers, currency modules | Rate lookups answer from a module. Advice and explanation queries still cite publishers |
| Healthcare and B2B | Thinner module coverage | Answers still assemble from outbound sources, so citation counts read more directly |
Source: BrightEdge. Category assessment based on rich-result coverage in classic Search.
A brand in eCommerce or Travel is the most likely to be reading a decline that is not there. It is also the most likely to have a quick win available. The inputs that govern module eligibility are the ones those teams already maintain.
How marketers win in AI Mode
Some categories are already dominated by specific rich results. Publishing, ecommerce, travel, finance. In those, your opportunity to improve visibility and selection is the same as it is in traditional search. Optimize for the listing type that is winning.
In eCommerce and Travel that means product feed quality, supporting schema, and differentiated content on your pages. Three inputs. They win you AI Mode and the traditional results page at the same time. We would expect them to matter less inside AI Overviews, which draws on content already ranking.
For publishing and finance it means entity ownership. Authoritative commentary written by real people, carrying data that is not widely available and not generated by AI. Supporting schema again underneath it.
What marketers need to know
- A low AI Mode citation count is not proof of lost visibility. Read it next to your presence in the rich results the answer is built from. google.com accounts for 44.9% of AI Mode citations and 9.9% of AI Overviews citations. That is one brand measured against two constructions.
- eCommerce and Travel see this first. These are the categories where rich results already carry the most weight in classic Search. That existing infrastructure is what AI Mode extends into.
- Audit the three inputs you control. Product, Offer and Review schema quality decides eligibility for the modules AI Mode draws from. Feed completeness on pricing, availability, GTINs and imagery populates those same surfaces. Crawlability and indexation decide whether the data is eligible at all. Every one of those is checkable this week, which a ranking model is not.
- Google is still the channel to plan around. Strengthen the structured data that already earns rich results in classic Search. The same schema and the same feed serve the classic result and the AI Mode answer. Fix once, and both surfaces improve.
Frequently asked questions
- What is Google AI Mode?
Google AI Mode is a conversational search surface that answers a query in full rather than returning a ranked list of links. It sits alongside AI Overviews, which is the AI summary above the classic results page. Both are Google, and they assemble an answer differently. - Why does Google AI Mode cite google.com so often?
Because AI Mode builds more of its answers out of Google's own rich-result surfaces, such as product grids, price comparison strips and rate tables. When the answer comes from one of those modules, the citation records the module. google.com accounts for 44.9% of AI Mode citations against 9.9% in AI Overviews. - Is this caused by Google's search click redirect layer?
No. Google confirmed the redirect layer in August 2026, and the gap measured here was already 32 points wide in January 2026. The redirect layer also applies to organic result links, which is a different measurement surface from an AI citation. - Does a low AI Mode citation count mean my brand is losing visibility?
Not on its own. In categories where rich results carry the page, a brand can win a position inside the module without appearing as a citation. Check presence in the rich results alongside the citation report before reading it as a decline. - What controls whether my brand appears inside those rich results?
Three inputs. Product, Offer and Review schema quality. Feed completeness and accuracy on pricing, availability, GTINs and imagery. General technical health, meaning crawlability, indexation and page-level signals. A brand controls all three and can audit them. - Which categories are most affected?
eCommerce and Travel, because those are the categories where rich results already have the deepest footprint in classic Search. Finance rate and price lookups show the same pattern. Healthcare and B2B technology have thinner module coverage, so citation counts there read more directly.
Technical methodology
Measurement: google.com as a share of all citations made by each engine. Engines: Google AI Mode and Google AI Overviews. Market: United States. Period: four observation points between January and August 2026. Prompt set: a BrightEdge tracked set covering consumer product and finance queries.
The series is plotted as absolute share and is never indexed to a baseline observation point. A short series indexed to one period makes every later movement a function of that period. A flat trend can then read as a step change.
Replication. AI Mode answers vary between sessions. Each prompt was run repeatedly, and BrightEdge kept only the prompts that returned a consistent result.
The four-prompt table is an illustration of the mechanism, not a sample. No conclusion in this edition rests on it. Every figure quoted anywhere in this edition is a share of citations or a spread in percentage points. We publish no raw citation counts and no sample sizes.
Key takeaways
| Finding | The number that proves it |
| Google AI Mode cites google.com far more than AI Overviews does | 44.9% of AI Mode citations against 9.9% of AI Overviews citations, a 4.5x multiple |
| The gap predates the August redirect news | 32 points wide in January 2026, 35 points in August 2026 |
| The mechanism is rich results, not suppression | On "american airlines stock price" AI Mode answers from a ticker module while AI Overviews cites three finance sites |
| It holds across retail, travel, local and finance | All four example prompts show the same split between the two surfaces |
| The fix sits in inputs a brand controls | Schema quality, feed completeness and technical health govern rich-result eligibility |
Download the full report
The downloadable edition carries all three figures, the full prompt-level table and the methodology. It is the version to send to your search, merchandising and feed leads.
Find out how your brand appears across AI Mode, AI Overviews and the classic result. Request a demo.
Explore more in our Weekly AI Search Insights series.
Pull your category's cited-domain list in AI Hyper Cube. Track your own citation share week over week in AI Catalyst. Compare it against your organic and rich-result footprint in Data Cube X. Check how AI crawlers reach your pages in AI Agent Insights.
Institution or Platform: What Health and Finance Citations Reveal About ChatGPT and Google AI Overviews
ChatGPT's five most-cited healthcare sources are government agencies and hospital systems. Google AI Overviews puts YouTube above every clinical source in the same category. Authority is not one standard, and the gap between the two engines is where small
Last week's edition traced a single publisher's rise in Google AI Overviews back to a shift in what people were asking. This one goes a level deeper, into who each engine treats as an authority once the question is asked. And into how much room that leaves anyone else.
We pulled the cited-domain lists for healthcare and finance, the two categories Google's quality guidance holds to the highest standard. Both engines, in AI Hyper Cube. They produce different lists in the same category, in the same week.
What counts as a YMYL category
YMYL stands for Your Money or Your Life. It is Google's own term, set out in its Search Quality Rater Guidelines. It covers topics where low-quality content could plausibly harm a person's health, financial stability, safety or wellbeing. Pages in those categories are held to a higher standard than the rest of the web.
| YMYL category | What it covers | Measured in this edition |
| Health and medical | Diseases, treatments, symptoms, mental health | Yes. Both engines |
| Financial advice | Investments, taxes, loans, banking | Yes. Both engines |
| Legal guidance | Divorce, custody, rights, obligations | Not yet |
| News and civics | Current events, government policy, voting information | Not yet |
Source: Category definitions from Google's Search Quality Rater Guidelines. Coverage from BrightEdge AI Hyper Cube, week of 23 August 2026, United States.
We measured the first two. Legal guidance and news and civics are not in this dataset, so nothing here should be read as a claim about them. Both are on the list to run next.
The reason the distinction matters is that the guidance describes a standard rather than a source list. It does not name which domains an engine should cite in a sensitive category, and the two engines we measured have reached different answers. AI Hyper Cube reports the cited-domain list per engine, so you can check your own category rather than infer it from the guidance.
ChatGPT reaches for the institution
In tracked healthcare prompts, every one of ChatGPT's five most-cited domains is a government agency or a non-profit hospital system. Across the top ten, that holds for nine. YouTube does not appear at all.
| Domain | Citation presence, share of tracked healthcare prompts |
| nih.gov | 43% |
| medlineplus.gov | 33% |
| mayoclinic.org | 27% |
| cdc.gov | 18% |
| clevelandclinic.org | 17% |
Source: BrightEdge Insights from AI Hyper Cube. Citation presence, week of 23 August 2026, United States.
If your category is safety-adjacent, that is the citation diet you compete against on this engine.
What we analyzed
Two categories, two engines. For healthcare we took the five most-cited domains on each engine and their citation presence. Citation presence is the share of tracked prompts in a category where a domain appeared as a cited source. We also took the weekly healthcare series on Google, indexed so every source starts at the same point. For finance we took citation presence at each rank position within each engine's top five.
Each category is a separate prompt set. We compare figures within a category and engine, never across them. The prompt sets are different sizes, so comparing across them would compare the sets instead of the engines.
Data collected
| Dimension | Detail |
| Capability | BrightEdge AI Hyper Cube, cited-domain and citations-trend views. AI Catalyst for the measurement guidance |
| Engines | Google AI Overviews, ChatGPT |
| Categories | Healthcare, finance. B2B technology as a non-sensitive control |
| Period | Week of 23 August 2026. Weekly healthcare series from 7 June |
| Metric | Citation presence, the share of tracked prompts in a category citing a given domain |
| Comparison basis | Within category and engine. Weekly series indexed to a common baseline |
| Geography | United States |
| Anonymization | Reported as shares and ratios only. No prompt or keyword counts |
Key finding
What the data shows. Measured: ChatGPT's healthcare top five is entirely government and hospital domains, with YouTube absent. In the same category on Google AI Overviews, YouTube stepped to roughly 1.8 times its June level in the week of 19 July, and held. Clinical partners stayed near baseline.
What we take from it. Inferred: the two engines are building different definitions of what counts as an authoritative source. The difference is large enough to change what a marketer should build. The data measures the lists. The read on what to build from them is ours.
Google reaches for the platform
The same category on Google looks nothing like ChatGPT's. In the week of 19 July, YouTube's citation presence in healthcare AI Overviews stepped up sharply and held there. NIH drifted below its June level.
| Source | Presence, week of 7 June | Presence, week of 23 August |
| youtube.com | 100 | 158 |
| clevelandclinic.org | 100 | 108 |
| nih.gov | 100 | 83 |
Source: BrightEdge Insights from AI Hyper Cube. Google AI Overview citations, indexed so each series starts at 100 in the week of 7 June 2026, United States.
Brands with authoritative content still place. They now place alongside individual clinicians, museums and creators. One video surfacing in this set is a pathology museum explaining a condition with a specimen in hand. The asset was distinctive rather than institutional.
Finance splits on how much room is left
Finance shows the same disagreement in a different shape. On Google the leading source is cited in roughly half of all tracked prompts. The four below it are the largest sites in the category. On ChatGPT the same list is close to level.
| Rank position | Google AI Overviews | ChatGPT |
| 1 | 51% | 19% |
| 2 | 29% | 15% |
| 3 | 19% | 14% |
| 4 | 19% | 14% |
| 5 | 18% | 11% |
Source: BrightEdge Insights from AI Hyper Cube. Citation presence as a share of tracked finance prompts, week of 23 August 2026, United States.
simplywall.st holds the fifth slot on ChatGPT. It is not a large publisher. It publishes community valuation narratives, where named contributors argue a fair value for a stock against analyst positions. No larger competitor in that list holds that view of a ticker.
Divide the leading source's presence by the fifth and you get a number worth running on your own category. Finance is 2.8x on Google and 1.7x on ChatGPT. A steep curve means an entrenched incumbent. A flat one means the category is shared.
How much the weighting changes by category
We added B2B technology as a control, because Google's strictest guidance does not cover it. The engine split appears there too, which suggests it tracks the engine rather than the sensitivity of the subject.
| Category | ChatGPT top five | Google AI Overviews top five |
| Healthcare | All government or hospital. No YouTube | YouTube first, above every clinical source |
| Finance | Spread across five sources, one specialist | One source at roughly half of prompts |
| B2B technology | nist.gov first, cisa.gov fourth | YouTube first, at two thirds of prompts |
Source: BrightEdge Insights from AI Hyper Cube. Citation presence, week of 23 August 2026, United States.
Three categories is a pattern. A rule would need more. Run the same cut on your own category before you assume it behaves like any of these. Then compare it against your organic footprint in Data Cube X, to see whether the pages an engine cites are the ones already ranking.
What marketers need to know
1. Find the thing only you can say. Without a distinct point of view or data nobody else holds, selection is luck of the draw. simplywall.st takes a finance top-five slot on ChatGPT on community valuation narratives no larger competitor publishes. Establish what you or your audience know that the category cannot easily aggregate.
2. Read the citation list for your category, per engine. The winning source type is not a constant. Government and hospital domains take all five of ChatGPT's healthcare slots. Google AI Overviews puts YouTube above every clinical source in the same category. Pull the list before you decide what to build.
3. Check how much room the list leaves you. Divide the leading source's citation presence by the fifth. Finance runs 2.8x on Google and 1.7x on ChatGPT. Above three you are displacing an incumbent. Under two you are joining a rotation, which is a far cheaper fight.
4. Start with Google, and do not read format as a shortcut. Google AI Overviews carries the volume, so plan there first. Video and community formats reach places a long-form article does not, and that is a distribution decision. Foundational SEO remains the cost of entry to both surfaces.
Frequently asked questions
What is YMYL content?
YMYL stands for Your Money or Your Life. It is Google's term for topics where low-quality content could harm a person's health, financial stability, safety or wellbeing. Google's Search Quality Rater Guidelines group them into health and medical, financial advice, legal guidance, and news and civics.
What are the YMYL categories?
Four. Health and medical, covering diseases, treatments and mental health. Financial advice, covering investments, taxes, loans and banking. Legal guidance, covering rights and obligations. News and civics, covering current events, government policy and voting information.
Do Google AI Overviews and ChatGPT cite the same sources in YMYL categories?
Not in this dataset. In healthcare, ChatGPT's five most-cited domains are government agencies and hospital systems, and YouTube does not appear. Google AI Overviews places YouTube above every clinical source in the same category and the same week.
Can a smaller site get cited in a YMYL category?
In finance, yes. Citation presence on ChatGPT is spread almost evenly across the top five, and simplywall.st holds a position on community valuation narratives no larger competitor publishes. Concentration is far higher on Google AI Overviews, where the leading source appears in roughly half of tracked prompts.
How do you find out which sources get cited in your category?
Pull the cited-domain list for your category on each engine and compare them. BrightEdge AI Hyper Cube reports citation presence per engine. AI Catalyst tracks how your own share moves week over week. Data Cube X shows whether the cited pages are the ones already ranking in organic search.
Technical methodology
| Item | Detail |
| Data source | BrightEdge AI Hyper Cube, cited-domain and citations-trend views |
| Engines | Google AI Overviews, ChatGPT |
| Categories | Healthcare, finance, and B2B technology as a non-sensitive control |
| Period | Week of 23 August 2026. Weekly healthcare series from 7 June 2026 |
| Measurement | Citation presence, the share of tracked prompts in a category citing a given domain |
| Indexing | The weekly series is indexed so every source starts at 100 in the week of 7 June, showing movement against a common baseline rather than absolute levels |
| Comparison basis | Within category and engine only. Never across categories |
| Geography | United States |
| Anonymization | Shares and ratios only. No prompt counts, keyword counts, or figures that back-calculate to either |
| Limits | Three categories and one week, plus one weekly series. Directional, and not a claim about every vertical or every period |
Key takeaways
| Finding | The number that proves it |
| ChatGPT treats institutions as the authority in health | All five of the top five are government or hospital. Nine of the top ten |
| Google AI Overviews treats the platform as the authority in the same category | YouTube stepped to 1.8x its June level in the week of 19 July and held |
| Google concentrates finance citations on one source | 51% presence at rank one, against 18% at rank five |
| ChatGPT spreads them | 19, 15, 14, 14 and 11 percent across the top five |
| A flat list is where a specialist site gets in | simplywall.st at rank five on ChatGPT in finance |
Download the full report
The downloadable edition carries all three charts, the full cited-domain lists, the B2B technology control, and the methodology. It is the version to send to your search and content leads.
Find out what counts as authority in your category. Request a demo.
Explore more in our Weekly AI Search Insights series.
Pull your category's cited-domain list in AI Hyper Cube. Track your own share week over week in AI Catalyst. Compare it against your organic footprint in Data Cube X.
Reddit Is Not Where Shoppers Find You. It Is Where They Check You.
BrightEdge research across nine industries finds that most prompts triggering a Reddit citation already name the brand the answer returns, placing Reddit at the vetting stage rather than the discovery stage on both engines
Two weeks ago this series measured Reddit's expansion in search visibility and found a tracked footprint roughly 33 times larger than a year earlier, with Google AI Overviews carrying about 88% of Reddit's AI citation volume. That study established scale. This one asks a different question. When an engine cites Reddit, what did the person already know before they asked?
We used BrightEdge AI Hyper Cube to analyze the prompts behind Reddit citations across nine industries on Google AI Overviews and ChatGPT. In categories where people shop by name, a large share of those prompts already contain the brand that the answer goes on to return. Reddit is not being consulted to assemble a shortlist. It is being consulted about a name the shopper already has.
The Shopper Usually Arrives With a Brand
For each Reddit-cited prompt we checked whether the prompt text itself names a brand that appears in the answer. The pattern separates cleanly between categories where purchase decisions are brand-led and categories where they are not.
| Industry | Google AI Overviews | ChatGPT |
| Restaurants | 43.5% | 52.0% |
| Ecommerce | 36.4% | 49.6% |
| B2B | 36.1% | 51.6% |
| Insurance | 27.8% | 33.8% |
| Finance | 27.3% | 35.7% |
| Travel | 22.8% | 23.2% |
| Entertainment | 21.5% | 42.6% |
| Education | 9.0% | 10.5% |
| Healthcare | 7.1% | 4.7% |
These figures use exact brand matching against the prompt text and represent a floor rather than a midpoint. Shoppers frequently use short forms of a brand name that a strict match discards.
What We Analyzed
We measured, for each industry and each engine, the share of Reddit-cited prompts in which the prompt names a brand returned by the answer, the number of distinct brands returned per Reddit-cited answer, and the distribution of cited prompts by intent stage. Brand presence was classified by exact word-bounded matching between prompt text and the brands recorded in the answer. Intent stage was taken from the classification attached to each prompt. All findings are reported as proportions within an industry and engine, so that differences between engines remain the unit of analysis rather than differences in the size of either prompt set.
Data Collected
| Data Point | Description |
| Engines analyzed | Google AI Overviews, ChatGPT |
| Platform analyzed | |
| Industries | B2B, ecommerce, education, entertainment, finance, healthcare, insurance, restaurants, travel |
| Period | 17 May 2026 through 2 August 2026 |
| Metrics | Share of cited prompts naming a returned brand; distinct brands returned per answer; distribution of cited prompts by intent stage |
| Comparison basis | Proportions within industry and engine |
| Anonymization | Findings reported as shares, rates and proportions, not raw prompt or citation counts |
Key Finding: This is not a Google phenomenon. ChatGPT cites Reddit far less often in absolute terms, but its Reddit citations are more concentrated on brand-aware prompts, in every industry analyzed except healthcare. Google carries the volume. ChatGPT carries the intent. Both point at the same stage of the buying process.
Reddit Citations Cluster at the Consideration Stage
The intent classification supports the same conclusion from an independent direction. In the categories where brand-aware prompts are most common, consideration-stage prompts account for the largest share of Reddit's cited prompts.
| Industry | Share of Reddit-cited prompts at consideration stage, Google AI Overviews |
| Insurance | 41.8% |
| Ecommerce | 36.1% |
| Finance | 35.6% |
| Restaurants | 33.9% |
| Education | 29.9% |
| B2B | 28.7% |
| Travel | 20.4% |
| Entertainment | 9.9% |
| Healthcare | 4.7% |
Two independently classified measures agree. Prompts show shoppers arriving with a brand, and intent classification shows them arriving at the point of decision.
Healthcare Behaves Differently, and That Confirms the Pattern
Healthcare is the lowest industry on both measures. Only 7.1% of its Reddit-cited prompts on Google name a brand, and only 4.7% sit at the consideration stage. People arrive at a healthcare question with a symptom rather than a company, and Reddit is retrieved for something other than vetting.
The vetting behavior appears precisely where purchase decisions are brand-led. It is a property of how people shop in a category, not a property of Reddit.
The Shortlist Is the Same Size on Both Engines
Reddit-cited answers return an average of 4.32 brands on Google AI Overviews and 4.56 on ChatGPT, with a median of four on both. Answers returning five or more brands account for 37.7% on Google and 41.8% on ChatGPT.
The influence is equivalent. A thread that no one on a marketing team has read is contributing to the set of names a buyer sees, and it requires no audience to do so. It only requires citation.
Restaurants Show the Behavior in Its Clearest Form
Among Google's Reddit-cited prompts in restaurants, 35.1% contain the word reviews. No other industry exceeds 3%. On ChatGPT the same figure for restaurants is 1.8%.
For operators with seasonal locations, holiday dining programs or catering services, this is a fourth-quarter exposure. The review query is being answered, and Reddit threads are answering it.
What Marketers Need to Know
Audit what AI already cites for your brand terms before deciding whether to participate. The threads currently cited are the verdict your buyer receives. Where a brand has a genuine community presence, participation is natural. Where it does not, forced participation reads as marketing.
Do not budget Reddit as reach. Reddit visibility is not upper-funnel awareness. It operates between a shopper knowing a brand and a shopper choosing it, which makes it a demand-capture concern rather than a demand-generation one.
Do not treat this as a Google-only problem. Google cites Reddit more often, but ChatGPT's Reddit citations skew harder toward brand-aware shoppers in eight of nine industries.
Weight the effort to your category. Brand-aware prompts run above 36% in restaurants, ecommerce and B2B on Google and above 49% on ChatGPT. In healthcare and education they run under 11% on both.
Publishing more content does not address this. The cited asset is a third-party thread that no brand controls editorially. The corrective action is monitoring and response, not production.
Technical Methodology
| Parameter | Detail |
| Data Source | BrightEdge AI Hyper Cube |
| Engines Analyzed | Google AI Overviews, ChatGPT |
| Platform Analyzed | |
| Industries | Nine, as listed above |
| Period | 17 May 2026 through 2 August 2026 |
| Measurement | Cited prompt classification by brand presence, brand count returned, and intent stage |
| Brand matching | Exact word-bounded match between prompt text and brands recorded in the answer. Reported figures represent a lower bound |
| Comparison Basis | Proportions within industry and engine |
| Anonymization | Findings reported as shares, rates and proportions, not raw prompt or citation counts |
Key Takeaways
| Finding | Detail |
| Shoppers arrive with the brand already in hand | At least 36% of Reddit-cited prompts in restaurants, ecommerce and B2B on Google already name a brand the answer returns. On ChatGPT the same industries run above 49% |
| Reddit sits at the vetting stage | Consideration-stage prompts account for 41.8% of Reddit citations in insurance and 36.1% in ecommerce on Google AI Overviews |
| Both engines, not just Google | ChatGPT's Reddit citations skew more brand-aware than Google's in eight of nine industries, despite far lower citation volume |
| The shortlist is the same size either way | Reddit-cited answers return a median of four brands on both engines |
| Healthcare is the exception that proves the rule | Healthcare is lowest on both measures, at 7.1% brand-aware and 4.7% consideration stage, because people arrive with a symptom rather than a company |
| Restaurants face a fourth-quarter exposure | 35.1% of Google's Reddit-cited prompts in restaurants contain the word reviews, against under 3% in every other industry |