
Meta AI Crawler Traffic Surged 30-Fold Ahead of the Muse Launch
Meta's AI crawler requests rose 30-fold on one site the day before Muse launched. What marketing and PR teams should know about AI bot tracking.
BrightEdge AI Agent Insights recorded a 30-fold increase in Meta-identified automated requests on one ecommerce client on September 7, 2026, from about 30,000 requests per day to about 1.0 million. Meta announced Muse, its personal AI agent, the following day. For the next 52 days, Meta ranked second among the ten companies tracked on 49 days and first on three.
Muse raises a practical question for marketing and communications teams: when an AI agent visits a brand's website, whom is it acting for, and how would anyone know? Many automated crawlers do not trigger the tracking that conventional web analytics depends on, because they fetch the HTML and never run the JavaScript a tag needs. A change of this size can pass through a brand's reporting without a single dashboard line moving. This edition sets out what the data shows, what it does not show, and how to track AI bot activity on your own site.
What is Meta Muse, and why does it matter for brand visibility?
Muse is Meta's personal AI agent, announced on September 8, 2026. It carries out tasks for a person across connected services, including email, calendar, bookings and purchases, and it launched in the United States.
Muse reaches the web differently from the crawlers in this research. It drives a browser for the user, one page at a time, during a session, which is retrieval at a person's request rather than bulk crawling. Meta documents a separate bot for user-triggered retrieval, meta-externalfetcher. That string does not appear in this dataset, and Meta has not published which string Muse itself sends.
Server logs can help identify which crawlers access your site and what they request. Standard web analytics often misses this activity, because a bulk crawler fetches HTML and never fires a tag, while an agent driving a real browser runs the same scripts a person would. Robots.txt is voluntary either way, and works only on a bot that declares itself honestly.
What the data shows: Meta AI crawler activity around the Muse launch
On September 7, 2026, automated requests identifying themselves as Meta rose from about 30,000 per day to about 1.0 million on one BrightEdge ecommerce client. Meta announced Muse on September 8. Google remained the largest source of AI crawler activity on 49 of the following 52 days, with Meta first on the other three. Request volume has stayed near the new level.
The step occurred between September 6 and 7. The launch followed on September 8. The increase was measured across two Meta bots that crawl, one used for link previews and one used for training and indexing, rather than the bot Meta documents for retrieval at a person's request. BrightEdge therefore does not attribute the traffic to Muse.
Meta's automated activity on this site grew more than 30-fold within one day, in the same week Meta launched a consumer AI agent. Whether or not Muse was involved, the operational response is the same. Brands need to know which Meta bots are reading their content, and they need to set policy for each one separately.
| Measure | Value |
| Requests per day before, September 6 | about 30,000 |
| Requests per day after, September 7 | about 1.0 million |
| Mean requests per day, September 8 to October 29 | 1.17 million |
| Approaching, late October | 2 million |
| Days ranked second of ten | 49 of 52 |
| Days ranked first | 3 of 52 |
Table 1. Automated crawler requests identifying themselves as Meta, one BrightEdge ecommerce client. Meta is meta_facebook_external_hit and meta_external_agent, combined. Source: BrightEdge AI Agent Insights, August 2 to October 29, 2026.
One feature of the daily series qualifies the baseline. Around August 9 to 11, five weeks before the step, Meta reached roughly 0.75 million requests per day and fell back to near zero within days. The pre-step figure of about 30,000 therefore describes a typical day, not the whole period.
The ten companies tracked on this site are Meta, Google, Apple, Amazon, OpenAI, Perplexity, Anthropic, Microsoft, ByteDance and Common Crawl. Google's bots were the largest source of AI crawler activity on 49 of the 52 days after the step. The channel a brand already plans around remained the biggest reader of its pages, and a second large reader arrived alongside it within a day.
A hit is one request from a user-agent string that BrightEdge attributes to a named company. It is not a session, a visit or a person, and a site serving heavier pages will record more hits for the same level of interest.
Meta's AI bots: three user-agents, three different jobs
A single company name can cover requests made for very different reasons. Meta is the clearest example.
| Bot | What Meta uses it for | What you are deciding if you block it |
| facebookexternalhit | Generates the link preview when a URL is shared on a Meta surface. Not used for AI training. | The preview card disappears when anyone shares your URL on a Meta surface. This is a social distribution cost, not an AI one. |
| meta-externalagent | Crawls the web to train foundation models and index content. | How Meta's models learn to describe you from here on. It does not reach back into what a model already holds. |
| meta-externalfetcher | Retrieves individual links at a person's request. Not present in this dataset. | Retrieval at the moment a person asks. Of the three, this has an immediate cost to a live session, and it is the one a personal agent such as Muse would be expected to use. |
Table 2. Meta's bot tokens, their documented functions, and what a brand is choosing between. Function column from Meta's crawler documentation, read November 11, 2026. The third column is BrightEdge's reading of the consequence, not Meta's guidance.
A rule written against the company name treats all three identically, and they do not perform the same function. Blocking every Meta crawler also stops the link preview when someone shares your page. Each should be reviewed on its own. robots.txt evaluates each user-agent string separately, so a site can refuse meta-externalagent and still allow facebookexternalhit. Because robots.txt is voluntary and depends on a bot identifying itself accurately, the rule is only as reliable as the declared identity behind it.
That dependence cuts both ways. Requests in this research are grouped by the identity each one declares, which is not an independent check of who sent them or why.
The wider baseline was already substantial. In April 2026, BrightEdge measured automated requests at 88% of human organic search activity, approximately 15% of total website traffic.
How AI bots work: training, search and user agents
AI bots divide into three types, and each calls for a separate decision. The definitions and shares below come from the BrightEdge guide to AI agents and are measured across tracked sites, not the single client above.
| Type | What it does | Largest bot | Share |
| Training | Builds and refreshes the knowledge base behind a model | GPTBot | 51% of training crawls |
| Search | Retrieves content to power AI answers and citations | OAI-SearchBot | 49% of AI search crawls |
| User | Acts for one person during an active session | ChatGPT User | 96% of AI user traffic |
Table 3. The three agent types and the largest bot in each. Source: BrightEdge AI Agent Insights research, November 2025 to February 2026.
Training bots shape how a model describes a brand over time. Search bots determine what is quoted in an answer. User bots act for one person in the moment, which is the category Muse falls into. Companies also run bots outside these three types, for link previews and other specialized functions, as with one of the two Meta strings measured here.
Most published policies address only one of the three. BrightEdge found that 19% of sites carry specific directives for ChatGPT-related bots, while the other 81% apply obsolete or conflicting rules designed for traditional crawlers. Among sites with a policy, 77% focus on blocking training bots, 21% address search bots and 38% address user-facing bots.
A brand that blocks or misclassifies a user bot may lose access or visibility in what that bot assembles for a person. The size of that effect is not measured here. Shopping agents are the case most retailers will encounter first, and the agentic commerce hub covers them in more depth.
What Meta's crawler activity means for marketing and PR teams
For digital marketing teams.
Muse and similar agents will evaluate what a site makes available to them. That work overlaps with technical SEO, and it depends on bots being able to reach the page and read it quickly. Policy decisions on training, search and user bots determine whether that happens.
For PR and communications teams.
Training crawlers such as meta-externalagent influence how Meta's models learn to describe an organization, which means newsrooms, executive biographies and press releases are potential source material whether or not anyone is monitoring access. Link preview crawlers affect how earned coverage appears when it is shared on Meta surfaces, so a blanket block carries a distribution cost. The evidence sits in server logs, not in media monitoring or web analytics, so communications teams often have no view of it unless they ask their web or SEO colleagues for it.
How to track AI bots and AI crawler activity on your website
The first three steps require no BrightEdge product and can begin immediately.
1. Pull your server logs, not your analytics.
AI crawler activity frequently does not reach standard analytics. In the raw logs, identify which bots request your pages, which pages they request most, and where they encounter a 404, a blocked resource or a slow response. Group by user-agent string rather than by company, because one company can run several bots that do different jobs. The output is a list of strings and a list of pages, and many of them will be unfamiliar.
2. Decide separately about training, search and user bots.
Define what each of the three should be permitted to do. Training bots build a model's long-run picture of your brand. Search bots retrieve what gets cited. User bots act for someone who is researching or shopping at that moment. A single blanket rule answers all three questions the same way, usually by default and usually in favor of blocking.
3. Check that a bot can reach your answer quickly.
BrightEdge research found that 97% of the top 20,000 websites are not built to give an agent a quick answer. Heavy navigation and scripts slow a bot before it reaches the content. Open your most commercially important page, reduce it to the text a bot would need, and note how far down the page that text begins.
4. Review your rules as the mix changes.
On this client the mix shifted sharply between a Sunday and a Monday. A rule written against one company can describe a situation that is replaced within a day, so the review schedule should follow how fast the mix moves, not the annual policy cycle.
5. Measure before you change anything.
AI Agent Insights reports which AI crawlers and agents access your site and what they engage with. That is the baseline against which every later change is judged, and it cannot be reconstructed after the fact.
There is a case for tracking AI bots in the same place as search performance. AI Hyper Cube shows how AI platforms represent a brand from the outside, and AI Agent Insights shows how agents experience the site from the inside. AI Catalyst keeps Google performance and AI visibility in a single view. Together they place Google rankings, AI citations and bot requests in one report instead of three. A standalone log tool can show that a bot arrived. It cannot show what that did to the channel a brand already plans around.
6. Serve bots a page they can read.
Agent Edge detects verified agent traffic at the CDN and serves those agents a lightweight page, while human visitors and Googlebot receive the original. Bloomfire found that its comparison and category pages were among its most visited, measured a baseline, launched on a limited set of pages and expanded once the numbers held. Agent traffic to optimized pages doubled, and AI referral traffic rose 30% in July 2026 against the prior 90 days. Arm served agents a payload about 90% smaller and held a 2x lift on optimized pages.
Key Takeaways
| Finding | Evidence |
| Meta's AI crawler requests went from negligible to second place in one day | About 30,000 to about 1.0 million requests per day, September 6 to 7, 2026, one ecommerce client. |
| The change was sustained, not a spike | Meta ranked second of ten on 49 of 52 days and first on three, averaging 1.17 million requests per day. |
| The step came a day before the Muse launch, which is not evidence of a cause | The step occurred September 6 to 7, 2026. Meta launched Muse on September 8. The increase was measured across two Meta bots that crawl, not the user-triggered fetcher, so this research cannot test a link to Muse in either direction. |
| AI bots fall into three categories | Training, search and user bots, each with a different largest bot. |
| Meta runs separate bots for separate jobs | Link previews, model training and indexing, and user-triggered retrieval each carry a different cost if blocked. |
| A change this size can go unseen | Conventional web analytics generally does not report AI bot traffic at all. |
Frequently Asked Questions
What is AI bot tracking?
AI bot tracking is the practice of identifying which AI crawlers and agents request a site's pages, which pages they request and where they encounter problems. It starts in raw server logs, because standard analytics generally does not capture this traffic. AI Agent Insights provides it continuously within BrightEdge.
How do I track AI crawler activity on my website?
Pull raw server logs rather than relying on analytics, and group requests by user-agent string rather than by company, since one company can run several bots with different functions. A one-off log pull shows whether there is a question worth answering. Continuous monitoring is needed to catch changes such as the one in this research.
What is Meta Muse, and does it crawl my website?
Muse is Meta's personal AI agent, announced on September 8, 2026. It acts for a person across connected services and reaches the web by driving a browser during a session. Meta does not publish which user-agent string Muse sends, so Muse traffic cannot be identified in logs from Meta's documentation alone.
Did Muse cause the increase in Meta crawler traffic?
This research cannot establish that it did. The increase came first, on September 7, and Muse launched on September 8. The two strings measured are bots that crawl, not the one Meta documents for retrieval at a person's request.
What is the difference between a training bot, a search bot and a user bot?
Training bots crawl content to build and refresh the knowledge base behind a model. Search bots retrieve content to power AI answers and citations. User bots act for one person during an active session, which is the category a shopping agent falls into. Each justifies a different access decision.
Should I block Meta's AI crawlers?
Each Meta bot warrants its own decision. Blocking meta-externalagent limits how Meta's models learn about a brand. Blocking facebookexternalhit removes the link preview when a page is shared on a Meta surface. Blocking meta-externalfetcher removes the brand from retrieval at the moment a person asks. A blanket rule treats these as one choice.
What does the Muse launch mean for PR and communications teams?
It makes AI bot activity a communications issue as well as a technical one. Training crawlers influence how models describe an organization, link preview crawlers affect how earned coverage is shared, and the evidence of both sits in server logs. Communications teams should ask web and SEO colleagues for a bot activity report and review access rules for newsroom and executive pages.
How much of my website traffic is AI bots?
This research cannot answer that for a specific site. BrightEdge measured agent activity at approximately 15% of total website traffic in April 2026 across its tracked base. On any individual site the figure depends on the catalog, the page weight and which companies have taken an interest, which is why the first step is a log pull.
Does AI bot traffic turn into revenue?
This research does not say. It counts requests that identify themselves as bots. It does not measure what any bot recommended, whether a purchase followed, or what the traffic was worth, and no commercial comparison was run.
What this measures, and what it does not
The research counts automated requests on one BrightEdge ecommerce client across ten tracked companies, August 2 to October 29, 2026. It does not measure whether any person was involved, what any agent recommended, whether a purchase followed, or what the traffic was worth. It is one site's view, not a market measurement and not a read on BrightEdge's customer base. The step occurred on September 7, before the Muse launch on September 8. The two Meta bots involved crawl rather than fetch at a person's request, so the research does not attribute the traffic to Muse or to a shopper. The section on marketing and PR implications is BrightEdge's interpretation, not a measured result.
| Field | Value |
| Capability | BrightEdge AI Agent Insights |
| Headline series | One BrightEdge ecommerce client, August 2 to October 29, 2026, daily. Not a market measurement and not a read on BrightEdge's customer base. |
| Companies tracked | Ten: Meta, Google, Apple, Amazon, OpenAI, Perplexity, Anthropic, Microsoft, ByteDance, Common Crawl. |
| Meta definition | meta_facebook_external_hit and meta_external_agent, combined. This data does not resolve which of the two drove the step. |
| Measure | A hit is one request from a user-agent string attributed to a named company. Requests are grouped by the identity each one declares, which was not independently verified. |
| Chronology | The step is dated September 6 to 7, 2026, before the Muse launch on September 8. |
| Earlier spike | Meta reached roughly 0.75 million hits per day around August 9 to 11 and fell back within days. The pre-step figure of about 30,000 describes a typical day, not the whole period. |
| Muse facts | Launch date and description from Meta's announcement of September 8, 2026, checked against four independent write-ups on November 13, 2026. Launch market published as the United States, the narrower of two readings in those sources. The marketing and PR implications section is BrightEdge's reading of the consequences, not a finding from this dataset. |
| Supporting figures | The 88%, 15%, 19%, 81%, 77%, 21%, 38% and 97% figures and the three agent-type shares are published BrightEdge research measured across tracked sites, not on this client. The agent-type shares cover November 2025 to February 2026. The policy source gives no base for 77%, 21% and 38%, so they are proportions among companies with a policy. |
| Not measured | What any bot recommended. Whether a purchase followed. Revenue. Any site other than the one client. Whether requests came from Muse specifically rather than another Meta process sharing the same strings. |
Source: BrightEdge AI Agent Insights, one ecommerce client, August 2 to October 29, 2026. Ten tracked companies. Muse facts from Meta. Part of the Weekly AI & Search Insights series, following last week's edition on branded AI Overviews.
AI Is Defining Your Brand Before You Get the Chance To
AI Overviews appeared on 64% of the brand searches BrightEdge tracked. Here is how to find out what they say about you, and who is writing it.
When someone searches your brand name, Google increasingly has something to say about you on the results page before they decide where to click. Between 16 August and 24 October 2026, the share of 282 tracked brand and product names showing a Google AI Overview rose from 19% to 64%, a 3.4-fold rise in ten weeks. Over the same weeks, the count of keywords showing an overview across the full tracked keyword list grew 47%. Brand names moved far faster than the list they sit inside.
That matters because an AI Overview is not your messaging. It is a summary assembled from sources, and your own website is only one of the places it can draw from. An overview may describe what your brand does, compare it with alternatives or draw on third-party assessments, and for a growing share of brand searches that description now sits on the results page next to your own listing.
What this measures, and what it does not. Whether a Google AI Overview appears on the results page for a brand name, tracked weekly in BrightEdge keyword reporting across 282 brand and product names, Google United States desktop. It shows that the overview is there. It does not measure whether the brand's own site is cited inside the overview, it does not show what the overview says, and it does not measure clicks, traffic or revenue. Those are the questions the audit below is built to answer.
AI Overviews reached 64% of the tracked brand names
The climb was steady for eight weeks, spiked, and settled lower. In the opening week, 19% of the 282 brand names had an overview. By the closing week, 64% did.
| Week | Brand names with an AI Overview | Share of 282 |
| 202634 | 53 | 19% |
| 202636 | 88 | 31% |
| 202638 | 140 | 50% |
| 202640 | 162 | 57% |
| 202642 | 208 | 74% |
| 202643 | 180 | 64% |
Table 1. Brand names with a Google AI Overview, selected weeks. Source: BrightEdge Keyword Reporting, Google United States desktop, weeks 202634 to 202643.
Do not read 64% as settled. The count hit 208 in one week and fell back to 180 the next, and individual brand names dropped out and returned. BrightEdge found the same shape in ecommerce in 2025, when AI Overview coverage spiked and then pulled back within weeks. The direction is clear. The exact level will keep moving, so treat any single week as provisional rather than a position.
Indexed to the opening week, brand names reached 340 by the closing week against 147 for the full tracked keyword list. Those two series measure different things. The branded figure is the share of a fixed set of 282 terms. The comparison figure is the count of keywords showing an overview across a list whose size is not disclosed and whose composition may have changed. The comparison is useful for direction and scale, not as a like-for-like coverage rate.
Big brands are not exempt
Smaller brand names got overviews first. In the opening week, none of the brand names above 1 million monthly searches had one. Ten weeks later, 56% did, and the gap between the largest and smallest brands had closed from 27 points to 10.
| Monthly searches for the brand name | Brand names | Week 202634 | Week 202643 |
| Leader brands, 1M+ | 32 | 0 of 32 (0%) | 18 of 32 (56%) |
| Large brands, 250k to 1M | 41 | 3 of 41 (7%) | 23 of 41 (56%) |
| Medium brands, 100k to 250k | 57 | 9 of 57 (16%) | 38 of 57 (67%) |
| Small brands, under 100k | 152 | 41 of 152 (27%) | 101 of 152 (66%) |
Table 2. Brand names with an AI Overview, by search volume. Tiers use the search volume in the keyword export. Source: BrightEdge Keyword Reporting, Google United States desktop.
Weighted by search volume, the effect is larger than the term count suggests. The 50 highest-volume brand names carrying an overview covered about 5.9 million monthly searches in the opening week and about 64.8 million by the closing week, roughly 11 times more, because the biggest brands arrived last. One term, Google Classroom, accounts for 17.5 million of that total, so read the weighted figure as an order of magnitude rather than a precise multiple.
A tiered rollout by search volume would fit this shape. So would several other explanations, and this analysis establishes neither. No public announcement of a branded-query change was found, and the data shows the sequence without showing a cause.
Which brands are still outside, and why that is not a safe place to be
Among the 130 tracked brand names above 100,000 monthly searches, the number with an overview went from 12 to 79. Devices were fully covered by the closing week. Restaurants were almost untouched.
| Category, names above 100k searches | Names | Week 202634 | Week 202643 |
| Devices and hardware | 20 | 5 | 20 |
| Packaged food and beverage | 21 | 2 | 18 |
| Games and entertainment | 17 | 2 | 15 |
| Finance and payments | 23 | 1 | 13 |
| Software and platforms | 21 | 1 | 11 |
| Restaurants | 24 | 1 | 2 |
| Retail and apparel | 4 | 0 | 0 |
Table 3. Brand names above 100k monthly searches with an AI Overview, by category. Source: BrightEdge Keyword Reporting, Google United States desktop.
Local brands are the most protected group here. Of the 59 tracked brand names whose results also show a local 3-pack, 20% have an overview, against 75% of the other 223. Forty of those 59 are restaurants. Chili's, Outback Steakhouse, Texas Roadhouse and Longhorn Steakhouse have not shown an overview in any week checked. Across all 67 restaurant terms in the set, coverage went from 4 to 12, and excluding those 67 terms the closing figure for the rest of the set is 78%. This describes the 67 restaurant brand names on this list, not restaurant search generally. The local-pack flags were recorded in week 202640 and were not refreshed, so that split is read against an older flag.
The exact words matter. "American Express" carries an overview and "amex" does not. The same brand can be defined for one version of its name and left alone for another, which means checking one term and assuming the rest is not an audit. Separately, several large brands had none in the closing week: PayPal, Charles Schwab, GitHub, Microsoft Teams and New Balance.
Being outside is not the same as being safe. Intent decides a lot here. Definitional terms such as "what is" and "define" were already at 97% of 286 tracked terms in the opening week and were not pulled again, so that figure is an opening-week reading rather than a closing comparison. Terms containing "stock" are now at 84% and terms containing "near me" at 13%, against 64% for brand names. The same intent pattern appears in BrightEdge's earlier work on which queries get AI Overviews. The brand names left out today are the ones whose searches look most like local or transactional intent, and that line has moved before.
What the overview says comes from somewhere
The overview on your brand name is built from sources, and in BrightEdge research the mix is often not what brands expect. Across five AI engines, the engines cite meaningfully different parts of the web while still recommending many of the same brands, which is the finding in why AI engines cite different sources but recommend the same brands.
Social and professional platforms are part of that source mix, and they work differently depending on the engine. BrightEdge's analysis of how ChatGPT and Google AI Overviews cite Facebook, Instagram, LinkedIn, Reddit and YouTube found the two treat them differently, in Profiles over posts. The same split shows up in the detail of how the two engines use Reddit differently and how they cite YouTube differently. Those engines are named here as context for where brand descriptions are assembled. This research measured Google AI Overviews only.
If AI Overviews are new ground, start with what AI Overviews are and how they are built, then the guide to generative engine optimization for how engines choose which brands to describe.
What to do: find out who is defining your brand
You cannot manage a description you have not read. The audit below takes a few hours the first time. It tells you whether AI is describing your brand accurately, who it is relying on to do it, and where to act.
1. Pull every version of your brand name and see which ones trigger an overview.
List the full name, abbreviations, nicknames, product and service names, common misspellings and the names of your top two or three products. Customers use all of them. Check each one in your keyword reporting for whether an AI Overview appears. As the "American Express" and "amex" example shows, one version of a brand name can trigger an AI Overview while another does not. Report these as their own segment rather than inside a site-wide keyword number: brand names rose 3.4 times here while the full tracked set grew 47%, and a blended number can obscure that difference.
2. Read the overview as a customer would, and write down what it says.
Capture the description: what it says you are, who you serve, what you cost, where you operate and when you were founded. Flag anything wrong, outdated or missing, and anything you would not say yourself. Note which competitors or alternatives it names next to you. This is the step the presence figure cannot do for you, because presence and content are two different measurements.
3. List the sources it cites and sort them into yours and not yours.
For each cited source, record the type: your own site, a review or comparison site, news, a community such as Reddit, LinkedIn, YouTube, a partner or a competitor. Sources outside your website can influence how AI describes your brand. Identifying them helps show where your brand narrative is being shaped, and where to spend effort.
4. Go beyond keywords and check the prompts people ask AI about you.
A brand name search is one entry point. People also ask conversational questions, and each one is a chance for someone else to define you. Run a set like this:
| Prompt type | Example pattern | What you learn |
| Definition | What is [brand]? | How AI categorizes you |
| Reputation | Is [brand] legit? Is [brand] any good? | Sentiment and risks AI repeats |
| Comparison | [brand] vs [competitor] | Who AI places you beside |
| Alternatives | [brand] alternatives; best [your category] | Whether you make the shortlist |
| Fit | [brand] for [use case or audience] | Which uses AI assigns you |
| Facts | [brand] pricing, headquarters, founder | Whether the basics are accurate |
| Local, if relevant | [brand] near me; [brand] hours | Whether the local pack or the overview leads |
Table 4. A starting prompt set for a brand description audit.
For each prompt, record whether you are mentioned, in what position, with what sentiment, and which sources are cited. Doing this by hand does not scale past a few dozen prompts, which is the job BrightEdge AI Catalyst is built for: tracking brand mentions, sentiment, citations and competitors across engines over time.
5. Fix what you find at the source, not in the overview.
Wrong or stale facts belong on the pages you control first, then on the third-party pages that carry them. Missing answers need clear, direct pages for the questions the prompts exposed: what you do, who it is for, pricing, how you compare. For social and professional profiles, align your company description, LinkedIn presence, YouTube and community participation with how you want to be described. The on-demand webinar How to Build and Execute a Social Media Strategy for AEO covers how AI engines cite LinkedIn, YouTube, Reddit, Instagram and Facebook, how to align corporate descriptions, job listings and profile structures so engines can verify your business, and how to measure whether offsite work is improving AI visibility. Where a review site, publication or community drives the description, that is where earned coverage and relationships matter, and BrightEdge brand visibility research covers how engines choose which brands to mention.
6. Baseline now, then repeat weekly.
Capture your branded clicks and impressions today. This analysis measures presence, not clicks, and the before-and-after comparison cannot be rebuilt later. Then re-run the audit weekly for a month before acting on any one reading. One week moved by 28 terms in this data.
Why This Figure Is Lower Than Some Others
Branded AI Overview coverage has been measured publicly by several organizations this autumn, and the figures reported range higher than the 64% here.
The differences are methodological rather than contradictory. Three things move the number.
The keyword list. This set is 282 unmodified brand and product names chosen by analyst judgment, and it is deliberately broad: 67 of them are restaurant brands and 59 return a local 3-pack, the two groups with the least coverage in this data. Excluding the restaurant terms takes the closing figure to 78%.
The definition of branded. A list that includes brand plus modifier terms, such as a brand name with "login" or "stock", measures something broader than the bare brand name. Those are different measurement populations, and this analysis tracks only the bare brand name.
The cadence. A weekly series shows a climb that began in mid-August. A reading taken on two dates shows a step.
None of that makes one figure right and another wrong. It means a branded AI Overview percentage is only comparable against another one when the list, the definition and the dates are stated. Those are stated in full below.
Key Takeaways
| Finding | Evidence |
| AI Overviews appeared on 64% of the brand searches BrightEdge tracked | 19% to 64% of 282 brand names in ten weeks, weeks 202634 to 202643 |
| Brand names moved faster than the list they sit inside | A 3.4-fold rise in branded presence against 47% growth in the count of keywords showing an overview across all tracked keywords |
| Big brands lost their head start | Names above 1M searches went from 0% to 56%; weighted by search volume, covered search demand rose about 11 times |
| The version of the name changes the result | "American Express" carries an overview and "amex" does not, so one term is not an audit of a brand |
| Local and restaurant brands are the exception, for now | 20% of brand names that also show a local 3-pack carry an overview, against 75% of the rest |
| The description comes from sources you may not control | BrightEdge research shows AI engines draw on editorial, community and social sources as well as brand sites |
| One week is not a position | The count moved from 179 to 208 and back to 180 in three weeks |
Frequently Asked Questions
How often do brand name searches trigger a Google AI Overview?
In this sample, 64% did by the closing week, up from 19% ten weeks earlier. The sample is 282 brand and product names tracked weekly on Google United States desktop. Coverage varies by category and by search volume, and restaurant brands are largely an exception.
Does an AI Overview on my brand name hurt my traffic?
This analysis does not say. It measures whether an overview appears, not clicks or traffic, and no Search Console comparison was run. That is why the audit starts with a baseline of branded clicks and impressions.
How do I find out what AI says about my brand?
Search every version of your brand name and read the overviews, note the sources they cite, then test the conversational prompts customers use. A capability such as BrightEdge AI Catalyst tracks mentions, sentiment and citations at scale.
Which brands still do not trigger an AI Overview?
In the closing week, PayPal, Charles Schwab, GitHub, Microsoft Teams and New Balance had none, and restaurant chains including Chili's, Outback Steakhouse, Texas Roadhouse and Longhorn Steakhouse had none in any week checked. Brand names that also show a local 3-pack carry an overview 20% of the time.
Do social platforms and LinkedIn affect how my brand is described?
They can. BrightEdge research shows AI engines cite LinkedIn, YouTube, Reddit and other platforms, and that engines treat them differently. The on-demand webinar on a social media strategy for AEO covers this in detail.
Did AI Overviews reach big brands or small brands first?
Small brands first, in this set. In week 202634 no tracked term above 1M monthly searches carried an overview, while 27% of terms under 100k did. By week 202643 the largest tier had reached 56% and the long tail 66%, closing the gap from 27 points to 10.
About This Data
| Field | Value |
| Capability | BrightEdge Keyword Reporting, top-page listing, blended rank, BrightEdge search volume |
| Engine | Google AI Overviews only. Other engines are not described by this edition |
| Market and device | United States desktop only. Mobile was not checked, and local packs are usually more prominent on mobile |
| Window | BrightEdge weeks 202634 to 202643, weekly cadence, 16 August to 24 October 2026. BrightEdge weeks run Sunday to Saturday |
| Brand set | 282 unmodified brand and product names selected by analyst judgment from one tracked keyword list. Composition: software 70, restaurants 67, packaged food 36, finance 33, games 29, devices 27, retail 20. Ambiguous names and login or .com variants were excluded |
| Set caveat | A different list gives different shares, and this list is skewed toward topics tracked for AI Overviews |
| Measure | Whether an AI Overview appears on the results page for the keyword. It does not measure whether the brand's own site is cited inside the overview |
| Comparison series | All tracked keywords with an AI Overview, published as a growth rate and an index. The underlying counts are not disclosed |
| Volume-weighted figure | The 50 highest-volume brand names carrying an overview, by BrightEdge search volume. The closing side comes from the same 180-term pull that supplies the tier and category counts. One term, Google Classroom, is 17.5 million of the 64.8 million total |
| Definitional segment | Terms containing "what is" or "define", 286 terms at 97% in week 202634. Not pulled again, so it is reported as an opening-week figure only |
| Known artifact | The all-keywords series dips in week 202637 while the branded series does not, which points to a collection issue in the totals rather than a real drop. No conclusion is drawn from it |
| Excluded week | A further week, 202644, returned counts identical to 202643 in both series, 180 branded terms and the same all-keywords total. Two independent weeks matching to the unit in two separate series is more likely to be one collection counted twice, so 202644 is excluded from this analysis pending verification. The closing figure is unaffected either way, because 202643 and 202644 both report the same 180 terms |
| Local 3-pack flags | Recorded in week 202640 and not refreshed. The local split is read against that older flag |
| Modified brand set | A separate 190-keyword set of brand names plus a modifier was last pulled in week 202640 at 65% and was not refreshed for this update, so it is not compared against the closing branded figure |
| Supporting file | The 282-term list is published with this edition. Weekly AI Overview flags in it cover the finance and restaurant categories, 100 terms; the remaining rows are not pulled. The headline counts come from the keyword-level SERP feature report matched to the 282-term list |
| Not measured | Clicks, sessions, traffic, revenue. Whether a brand's own site is cited in the overview. What an overview says. Why coverage arrived in the order it did. Any engine other than Google AI Overviews. Any market outside the United States |
| Comparability | Branded AI Overview percentages published elsewhere use different keyword lists, different definitions of a branded query and different collection dates. They are not like-for-like with this figure |
Source: BrightEdge Keyword Reporting. Share of 282 tracked unmodified brand names showing a Google AI Overviews result, United States desktop, weeks 202634 to 202643. Part of the Weekly AI & Search Insights series.
Paramount Closed Its $110bn Warner Deal. In September, AI Answers Saw Six Brands, Not One.
In September 2026, the month before Paramount closed its acquisition of Warner Bros. Discovery, six of its streaming brands together held about 21% of brand mentions on ChatGPT and Google AI Overviews.
In September 2026, the month before Paramount closed its acquisition of Warner Bros. Discovery, Paramount+, HBO, Max, HBO Max, Pluto TV and Discovery+ together held 21.35% of brand mentions on ChatGPT and 21.11% on Google AI Overviews, measured across thirteen streaming brands. Second to Netflix on both. Three of those six are HBO-related brand names, and the two engines rank them differently: ChatGPT mentions HBO most often, Google AI Overviews mentions Max most often.
What this measures: BrightEdge AI Hyper Cube data with share of brand mentions inside AI answers, calculated as each brand's mentions divided by total mentions across the top thirteen streaming brands measured, in the United States, on ChatGPT and Google AI Overviews. It does not measure clicks, traffic, subscribers or revenue. See Technical Methodology.
The AI visibility position Skydance inherited
Skydance has a potential brand problem through its acquisition of Warner Bros. Discovery, which closed on 6 October 2026. The deal brings together a streaming portfolio with some naming consistency issues.
| Brand | ChatGPT | Google AI Overviews |
| Netflix | 27.93% | 28.23% |
| The six combined | 21.35% | 21.11% |
| Apple TV | 14.67% | 11.55% |
| Hulu | 12.27% | 11.70% |
| Disney+ | 7.87% | 7.95% |
Table 1. Share of brand mentions across thirteen streaming brands, September 2026, United States. The six are Paramount+, HBO, Max, HBO Max, Pluto TV and Discovery+. Source: BrightEdge AI Hyper Cube.
Netflix leads the six combined by 6.58 points on ChatGPT and 7.12 points on Google AI Overviews. Skydance, read as one portfolio, is a clear second. But read as the engines actually report it, it is six separate brand names, none of which reaches 7%.
Three HBO-related names, two engines that rank them differently
Three of the six are HBO-related brand names: HBO, Max and HBO Max. HBO is a channel and a programming brand as well as a streaming label, so the engines may be answering about different things under each name. What the data shows is which name each engine uses.
| Label | ChatGPT | Google AI Overviews |
| HBO | 5.52% | 4.70% |
| Max | 3.11% | 5.05% |
| HBO Max | 3.47% | 2.33% |
Table 2. Share of brand mentions for the three HBO-related names, September 2026, United States. Source: BrightEdge AI Hyper Cube.
ChatGPT mentions HBO most often, at 1.59 times the next of the three. Google AI Overviews mentions Max most often, at 1.07 times. Neither engine collapses the three into one, and the two do not agree on which name they reach for.
Older brand names can remain prominent well after a rebrand. HBO Max launched in 2020, was renamed Max in 2023 to signal a broader mix of programming, and went back to HBO Max in July 2025. For HBO Max, our September data shows that the former Max name continues to appear frequently in AI answers: more than a year after the name returned, Google AI Overviews still mentions Max more than HBO Max, and ChatGPT has the two at near parity.
Skydance should consider this learning as it looks at consolidating further. Tracking the same three names through a branding change is what would show how visibility moves. This research does not establish what any one name would be worth after such a change.
Much like TV ratings, live events dominate AI conversations
| Prompt category | ChatGPT | Google AI Overviews |
| Live events | 65% | 73% |
| Where to watch a title | 15% | 22% |
| Ownership questions | Under 1% | Under 1% |
Table 3. Share of top-prompt volume by category, September 2026. Prompt-mix analysis by BrightEdge Professional Services on the top 60 to 100 prompts by estimated volume per engine, categorized by keyword rules. Read as indicative.
Among the top prompts analyzed by estimated volume, live events (prompts like "What channel is the F1 race on today?") lead on both engines, followed by where to watch (prompts like "Where to watch Euphoria"). Despite the big news surrounding the acquisition, ownership questions were rarely seen, accounting for under 1%. These shares describe that sample rather than every question put to either engine.
What We Analyzed
BrightEdge measured brand mentions across thirteen streaming brands in AI answers on ChatGPT and Google AI Overviews, in the United States, for September 2026. No prompt filter was applied. The six Paramount and Warner Bros. Discovery streaming brands were then compared against each other and against the rest of the field, and the three HBO-family labels were compared separately on each engine.
Data Collected
| Field | Value |
| Source | BrightEdge AI Hyper Cube |
| Engines | ChatGPT and Google AI Overviews |
| Brand set | Thirteen streaming brands, including Netflix, Apple TV, Hulu, Disney+ and the six Paramount and Warner names |
| Market | United States |
| Period | September 2026 |
| Metrics | Share of brand mentions within the set |
| Prompt filter | None |
| Prompt-mix sample | Table 3 comes from the top 60 to 100 prompts by estimated volume per engine, not from all prompts |
| Not disclosed | Mention counts and prompt counts. BrightEdge publishes shares and ratios, not sample sizes |
Key Finding
Measured. The six brands together held 21.35% of brand mentions on ChatGPT and 21.11% on Google AI Overviews, second to Netflix on both. Within the HBO family, ChatGPT ranked HBO first at 5.52%, HBO Max second at 3.47% and Max third at 3.11%. Google AI Overviews ranked Max first at 5.05%, HBO second at 4.70% and HBO Max third at 2.33%.
Inferred. Brands are complicated and persistent. A company answering to several brand names is treated as several brands by both engines, and an older name can stay prominent well after a rebrand. More than a year after HBO Max returned to its original name, Google AI Overviews still mentions Max more frequently. That shows why marketers need to track both current and former brand names. It is not a finding about HBO specifically, and we were unable to identify a clear reason why one would be captured vs. the other, nor how persistent these kinds of discussions are.
How that affects your measurement
Share of mentions is calculated per brand name. An engine that answers with "Max" records a mention for Max, and an engine that answers with "HBO" records one for HBO. Nothing joins them without coordinating brands and sub-brands.
That has two consequences for any company with more than one name.
Each name is measured separately, so a dashboard filtered to one of them shows part of the position rather than all of it. The three HBO-related names individually range from 2.33% to 5.52%; together they are 12.10% on ChatGPT and 12.08% on Google AI Overviews.
The sum is a valid figure, and it answers a specific question. Because the metric counts mention instances, adding the shares gives the group's share of all mention instances across the thirteen brands. It is not the share of prompts in which at least one of those names appears.
What Marketers Need to Know
Use brand grouping to create a consistent definition of who your brand is. A short name, a legal name and a product name are three brands to an AI engine. Create a standard definition of a Grouped Brand to represent all your brand names.
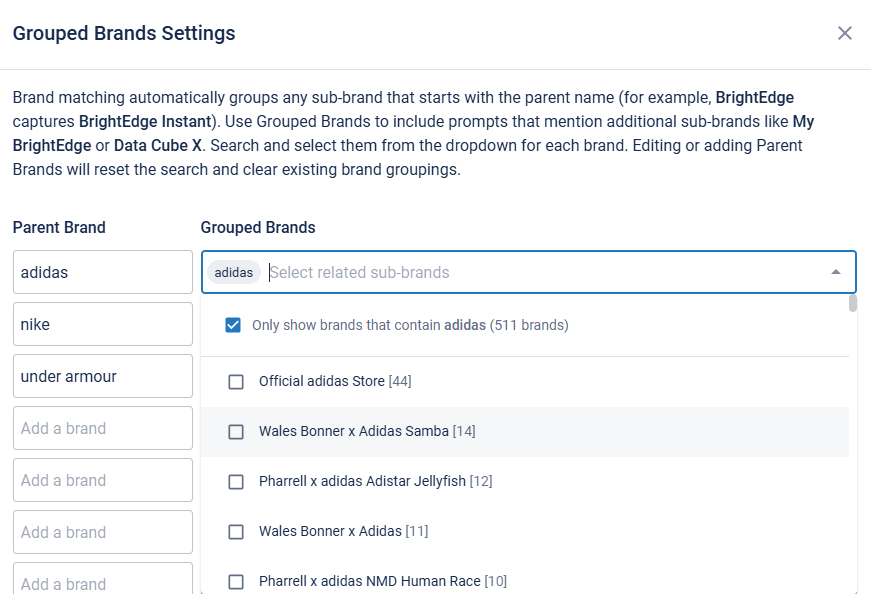
Grouped Brands Settings in BrightEdge AI Catalyst. Brand matching groups any sub-brand that starts with the parent name, and additional sub-brands are selected per parent brand so that every name a company answers to is measured as one.
Compare the engines against each other. ChatGPT and Google AI Overviews ranked the same three names differently here. A reading taken from one engine is half the picture.
Record the baseline before any branding change. A rename, a merge or a retirement can only be assessed against a measured starting position. Put the current names on record first, then track the same set through the change.
Work on the questions that carry the volume. Among the top prompts analyzed by estimated volume, live events lead on both engines. An evergreen how-to-watch page answering time, channel and stream covers the largest category in that sample.
Technical Methodology
| Field | Value |
| Capability | BrightEdge AI Hyper Cube, brand mention comparison |
| Engines | ChatGPT and Google AI Overviews |
| Window | September 2026, monthly cadence. One month, read as a snapshot rather than a trend |
| Market | United States only |
| Prompt filter | None. An earlier working cut excluded prompts containing a brand name by substring, which also drops every prompt containing "max" and therefore undercounts Max. That filter was not applied here |
| Brand set | Thirteen streaming brands. Share figures are relative to this set and change if the set changes |
| Share metric | percent_of_mentions, a brand's mentions divided by total mentions across the measured set |
| Metric not used | share_of_mentions in the same response is volume-weighted, being a brand's share of the search volume associated with the prompts where it was mentioned. It is a different measure and is not reported in this edition |
| Combined figure | The 21.35% and 21.11% totals add six individual shares. Because the metric counts mention instances, the sum is the six brands' share of all mention instances across the thirteen. It is not the share of prompts in which at least one of the six appears. That is a different metric with a different denominator, requiring prompt-level deduplication, and it is not reported here |
| Timing | AI Hyper Cube monthly coverage runs to September 2026. Every figure predates the 6 October 2026 close |
| Prompt mix | Categories in Table 3 come from BrightEdge Professional Services analysis of the top 60 to 100 prompts by estimated volume per engine, categorized by keyword rules. The shares describe that sample, not every question put to either engine. Single large prompts can move the mix. Indicative only |
| Not measured | Clicks, sessions, subscribers, revenue. Why any brand was mentioned. Customer sentiment. What any name would be worth after a branding change. Any engine other than ChatGPT and Google AI Overviews. Any market outside the United States |
| Brand name history | HBO Max launched in 2020, was renamed Max in 2023 and returned to HBO Max in July 2025. Source: Warner Bros. Discovery, Variety and The Hollywood Reporter, May and July 2025 |
| Company naming | Paramount Skydance acquired Warner Bros. Discovery, and the combined company is named Skydance. Source: CNBC and Variety, October 2026 |
| Deal facts | Axios, 6 October 2026 |
What Is Still Open
How Skydance handles the merger remains to be seen. The earlier Warner Bros.-Discovery merger left many brand names in place. With three major streaming platforms (HBO Max, Paramount+ and Discovery+) and new leadership, branding decisions, as we have shown, can have long-running implications for how you show up in AI.
- Whether the position moves after the close, which only post-merger data can show.
- Whether the engine disagreement holds. One month on two engines in one market is a snapshot. A second month would show whether ChatGPT's preference for HBO and Google AI Overviews' preference for Max are stable.
- Whether the conversation mix holds. The prompt-mix categories come from a single month's top prompts and have not been reproduced independently.
Key Takeaways
| Finding | Supporting evidence |
| AI answers saw six brands, not one company | Paramount+, HBO, Max, HBO Max, Pluto TV and Discovery+ measured separately on both engines |
| Together they ranked second to Netflix | 21.35% on ChatGPT and 21.11% on Google AI Overviews, against Netflix at 27.93% and 28.23% |
| Three of the six are HBO-related names | HBO, Max and HBO Max are measured as three separate brands by both engines |
| The engines reach for different ones | ChatGPT mentions HBO most often at 1.59x the next of the three; Google AI Overviews mentions Max most often at 1.07x |
| An older name can stay prominent after a rebrand | Max returned to the HBO Max name in July 2025, and Google AI Overviews still mentions Max more often |
| September is a baseline, not a forecast | The figures show where each name stands before the close, and a branding change would need the same names tracked through it |
| Ownership questions are a small share of the volume analyzed | Under 1% on both engines, among the top prompts by estimated volume |
Frequently Asked Questions
Which streaming brands are the biggest in AI?
Across thirteen streaming brands in the United States, Netflix led on both engines, at 27.93% of brand mentions on ChatGPT and 28.23% on Google AI Overviews. The six Paramount and Warner Bros. Discovery names together held 21.35% and 21.11%, ahead of Apple TV, Hulu and Disney+.
Do ChatGPT and Google AI Overviews treat HBO, Max and HBO Max as the same brand?
Neither does. Both engines record a mention against the specific name used, so the three are measured as three brands. The engines also reach for different ones: ChatGPT mentions HBO most often, at 1.59 times the next of the three, while Google AI Overviews mentions Max most often, at 1.07 times. HBO is also a channel and a programming brand, not only a streaming label, so the three are related names rather than interchangeable ones.
How often does Google AI Overviews mention Max versus HBO Max after the rebrand?
In September 2026, Google AI Overviews mentioned Max in 5.05% of brand mentions across thirteen streaming brands, against 2.33% for HBO Max. The service had returned to the HBO Max name in July 2025, more than a year earlier. ChatGPT had the two closer together, at 3.11% for Max and 3.47% for HBO Max. This research records that the older name is still in use on both engines. It does not establish why, and a single month cannot show how long a name change generally takes to register.
How should a merged company measure AI visibility through a brand name change?
Record the position of every name involved before the change, on each engine, then measure the same set afterwards. This research is an example of the first half: September 2026 positions for all six names, on ChatGPT and Google AI Overviews, taken before the deal closed. It does not forecast what any name would be worth after a change, and no measurement taken before one can.
Does this research measure the effect of the Paramount and Warner Bros. Discovery merger?
No. Every figure is September 2026 and the deal closed on 6 October 2026, so this describes the position Skydance inherited. October data is not yet available. The first post-merger read is the one that can show movement.
What do people ask AI about streaming services, among the highest-volume prompts?
Among the top 60 to 100 prompts by estimated volume on each engine, live events lead at 65% on ChatGPT and 73% on Google AI Overviews. Where to watch a specific title follows at 15% and 22%. Questions about who owns which service account for under 1% on both. These shares describe that sample rather than every question put to either engine.
What does share of brand mentions measure, and what does it not?
It is a brand's mentions divided by total mentions across the brands measured, inside AI answers. It does not measure clicks, traffic, subscribers or revenue, it does not establish why a brand was mentioned, and it does not predict what a name would be worth after a branding change. It depends on the brand set chosen, so a different set gives different shares.
Source: BrightEdge AI Hyper Cube. Share of brand mentions across thirteen streaming brands, United States, September 2026, on ChatGPT and Google AI Overviews. Deal facts from Axios, 6 October 2026. Brand name history from Variety and The Hollywood Reporter.
More from this series
See the rest of the Weekly AI & Search Insights series.
Google's Product Grid Disappeared in 14 European Markets: What Retailers Need to Check
On 16 September 2026 Product Grid listings stopped appearing in all 14 EEA markets BrightEdge tracks, and a Comparison Sites section began appearing in the same markets on the same day.
On 16 September 2026, Product Grid listings stopped appearing in all 14 EEA markets BrightEdge tracks. A Comparison Sites section began appearing in the same markets on the same day. In the EEA a retailer's free product listings run through one comparison shopping service. Google Shopping appeared in the new section 16 to 35 times as often as the next-largest service. That is across Germany, France, Spain and Italy, on tracked queries from 9 to 29 September.
Which service represents your domain is quick to establish. It sits in the Merchant Center CSS dashboard, it costs nothing to check, and it decides which service places your free listings. Feed quality and your relationships with third-party catalogs sit alongside it.
What this measures: This counts how many tracked keywords display each section. It does not show whether a given merchant's products appear inside it, and it does not measure clicks. The markets are the 14 EEA markets BrightEdge tracks, which are 13 EU countries plus Norway. Other EEA markets exist and were not measured.
The switch happened on one day, in every tracked market
Product Grid listings stopped appearing in all 14 tracked EEA markets after 15 September. The Comparison Sites section began on 16 September, the same day in every one of them. Product Grid stayed flat throughout in the UK, US, Canada and Australia, which sit outside the change.
Google removed the grid to comply with a European Commission ruling of 23 July 2026 under the Digital Markets Act. The ruling found that Google favored its own shopping, hotel, transport and sports results, and fined it EUR 460 million. Reuters reported a 60-day compliance window, and the September change landed inside it.
Google disagrees with the ruling. The change is a compliance step. Compliance does not establish that this particular layout has to remain, so treat the current arrangement as the position in the measured window.
One setting decides which service places your free listings
In the EEA, one comparison shopping service represents a merchant domain for free product listings. Google documents this per domain. Several services can be used for paid campaigns, and one carries the free listings. This rule predates the September change. What changed on 16 September is the place those listings appear.
Google Shopping appeared in the Comparison Sites section 16 to 35 times as often as the next-largest service. That is across Germany, France, Spain and Italy, on tracked queries from 9 to 29 September 2026. 71% of Comparison Sites appearances landed in result positions one to four, from 61% in France to 76% in Spain and Italy. It is premium space.
What the multiple counts. The 16 to 35 times comparison measures how often each service appears in the section. It does not measure an individual merchant's product visibility or performance. BrightEdge has not tested what changes when a merchant switches service. Google Shopping led the section across those three weeks. Read your own selection before deciding whether to change it.
Confirm which CSS represents your domain, resolve related disapprovals, and check whether priority products appear.
Where the selection does not match the destination, Merchant Center disapproves the products with the message "CSS not selected for this destination". Resolve the CSS mismatch, then check for any remaining eligibility issues.
Merchant Center and third-party catalogs provide separate routes into the section
| Route | Fed by | Your lever |
| Google Shopping box | Merchant Center feed, product and offer schema, page content | Feed quality, and which CSS represents your domain for free listings |
| Third-party service boxes | Each service's own catalog, fed by direct feeds, affiliate networks or feed partners | Presence and data accuracy in each service's catalog |
Coverage figures cover 1 September to 13 October 2026. Share and position figures cover 9 to 29 September 2026. Routes by which a product can appear in the Comparison Sites section. Source: BrightEdge Professional Services, with CSS mechanics from Google Merchant Center documentation.
Third-party comparison services use their own product catalogs, separate from Merchant Center. Retailers should check which services carry their products and whether the information is accurate.
Google Shopping appeared substantially more often than other services during the period measured. The section exists to give third-party services comparable prominence. Monitor changes in service appearances alongside your own product coverage.
Coverage returned to its previous level by 30 September
On 16 September, the number of tracked keywords showing a Comparison Sites section was 38% below the previous Product Grid baseline. Coverage increased through the remainder of September and matched the previous baseline on 30 September. The baseline is 53,035 keywords, day one counted 32,771, and 30 September counted 53,227.
Since 3 October, the combined count has remained 3% to 8% above that baseline.
These figures measure how often a product section appeared in tracked search results. They do not establish whether individual retailers retained their visibility or traffic. Changes in how the new section was collected may also have affected the early trend.
Markets did not move together
| Market | Day one | Index level, with the date of that reading |
| Germany | Fell to about half its old count | 108% to 111% of baseline on 3 October |
| Italy | Deep day-one drop | 108% to 111% of baseline on 3 October |
| Spain | Deep day-one drop | 108% to 111% of baseline on 3 October |
| Poland | Dipped less | At baseline on 13 October |
| Finland | Smaller early hit | About 14% below baseline on 13 October |
| Norway | Smaller early hit | About 6% below baseline on 13 October |
Selected markets, indexed to each market's own Product Grid average for 10 to 14 September. Source: BrightEdge Professional Services, 1 September to 13 October 2026. The six shown are the clearest examples of each pattern. The other eight tracked markets mostly follow the large-market or Poland shape.
Germany, Italy and Spain took the deepest day-one hits and recovered slowest, then sat above their old baselines on 3 October. Finland and Norway took smaller early hits and missed the 30 September step.
Finland and Norway remained below baseline on 13 October, the last day of the window. Both are small markets where a few dozen keywords move the index, so neither reading is a reliable guide alone.
What to do before the holiday peak
- Establish which CSS represents each merchant domain for free listings. Confirm the service, resolve eligibility issues, and assess that choice against your own product visibility. A market-wide share does not answer it.
- Annotate 16 September in European product reporting. The grid and the Comparison Sites section are different layouts, so measures either side are not like for like. Mark the date, report layout-specific measures separately, and keep the earlier history.
- Establish which third-party services carry your priority products, market by market. Those boxes fill from each service's own catalog. Record the service, the feed behind it, and whether the product data is accurate. Order the work by which markets carry your peak trading. The recovery index does not tell you where your catalog gaps are.
- Make the feed, the page and the structured data agree. Product information may appear across Google Shopping, third-party catalogs and AI shopping experiences. Match titles, prices, availability and identifiers across all of them.
- Compare clicks either side of 16 September. Compare product-page and non-product-page clicks before and after the change.
Start by checking CSS setup and product eligibility. Then prioritize the markets and products that matter most for holiday trading. Building coverage across third-party catalogs is slower, and how far up the list it belongs depends on which markets and products carry your peak.
Related check: product-page accessibility
Product-page accessibility is a related readiness check, and it sits outside the research above.
Crawlers vary in whether and when they execute JavaScript, and several AI crawlers fetch raw HTML without rendering it. Content that appears only after client-side rendering may be missed, so serve price, variants, availability and reviews in the page code itself.
Test this on your own pages. An industry average does not tell you which of your templates fail. Crawl a sample of product pages with JavaScript disabled and compare what appears with the browser view. Then check server logs for which crawlers fetched the full product content.
How to check this for your own site
Before you compare anything, note what changed in the reports. From the week of 27 September 2026, BrightEdge platform Product Grid reports reflect the new layout. Grid title, grid rank, product count and seller count can shift for reasons unrelated to SEO performance.
Find the keywords that lost a grid listing. In BrightEdge Product Grid reporting, pull the EEA keywords where your products appeared in the grid before 16 September, by market. Those are the keywords to follow through the switch.
Compare by market, with 16 September annotated. In Data Cube X and Product Grid reporting, compare keyword counts by listing type for your domain on either side of 16 September. Index each market to its 10 to 14 September average, as this edition does.
Compare clicks across the switch. In GSC Reporting, compare clicks to product pages and to non-product pages for your EEA markets before and after 16 September.
Frequently asked questions
What is the Comparison Sites section?
A section Google began showing on 16 September 2026, observed in the 14 EEA markets BrightEdge tracks, where comparison shopping services list products. Google Shopping, Google's own service, is one of them. It replaced the free product grid.
What is a comparison shopping service?
A service that places products in Google results in Europe, such as Google Shopping, idealo or billiger.de. A retailer selects one for its free listings.
Is the product grid gone everywhere?
No. The 14 EEA markets BrightEdge tracks all switched on 16 September. The UK, US, Canada and Australia kept the grid throughout the window.
Which markets did BrightEdge measure?
Austria, Belgium, Czechia, Denmark, Finland, France, Germany, Greece, Italy, the Netherlands, Norway, Poland, Spain and Sweden. These are 13 EU countries plus Norway. Other EEA markets exist and were not measured, so this edition does not describe them. Share and position figures cover Germany, France, Spain and Italy.
Which comparison shopping service should I select?
This research does not answer that. Google Shopping appeared 16 to 35 times as often as the next-largest service. That is across Germany, France, Spain and Italy, from 9 to 29 September 2026. That figure measures how often each service shows up in the section. It does not measure how a merchant's products perform inside it, and BrightEdge has not tested what changes when a merchant switches service. Start by reading which service represents your domain.
Did EEA traffic drop when the grid was removed?
This edition measures visibility and does not measure clicks, so it cannot answer that. Compare clicks to your product pages and to your non-product pages either side of 16 September in your own reporting.
Are merchants keeping their visibility?
The counts cannot answer that. Keyword coverage of the Comparison Sites section matched the old Product Grid level by 30 September. The counts show how many keywords display the section. Whether a given merchant's products appear inside it is a different question. That depends on your CSS selection and on the feeds third-party services ingest.
Is the grid coming back?
Unknown. The change is a compliance step and Google disagrees with the ruling. Compliance with the decision does not establish that this particular layout has to remain.
Technical methodology
| Field | Value |
| Source | BrightEdge Professional Services Total Search Visibility daily collection on a tracked product query set |
| Window | 1 September to 13 October 2026, daily |
| Markets | The 14 EEA markets BrightEdge tracks, being 13 EU countries plus Norway. The UK, US, Canada and Australia serve as non-EEA comparisons and Product Grid stayed flat in all four |
| Metric | Distinct keywords per day, per market, showing a Product Grid through 15 September or a Comparison Sites section from 16 September. The combined series sums the 14 markets, so a keyword tracked in more than one market counts once in each |
| Baseline | Each market's Product Grid average for 10 to 14 September is set to 100, and the combined baseline is 53,035 keywords. 10 September is the start because Austria, Belgium and Czechia expanded their tracked sets that day |
| Transition days | Combined Product Grid keywords fell about 8% on 15 September, before the first Comparison Sites row appeared. This edition dates the switch to 16 September |
| Share and position | Google Shopping's multiple is its appearances in the section divided by the next-largest service's appearances. Tracked queries in Germany, France, Spain and Italy, 9 to 29 September 2026. This is a narrower window than the daily coverage collection, which runs 1 September to 13 October 2026 |
| Known alternative explanation | The 30 September step hit the largest markets together and row counts moved unevenly across markets. A classification change on the collection side has not been ruled out |
| Not measured | Clicks, revenue and AI surfaces. Whether the same keywords appear on both sides of the switch. Whether any individual merchant's products appear in the section. Whether selecting a different comparison shopping service changes a merchant's visibility |
| Context | The 23 July 2026 ruling and the 60-day compliance window come from public coverage |
Key takeaways
| Finding | Supporting evidence |
| One service represents your domain for free listings, and it is yours to read and change | One CSS carries free listings in the EEA. Google Shopping appeared 16 to 35 times as often as the next-largest service in Germany, France, Spain and Italy, 9 to 29 September 2026 |
| The switch happened on a single day across every tracked market | Product Grid listings stopped and Comparison Sites began on 16 September 2026 in all 14 tracked EEA markets |
| The section is premium space | 71% of Comparison Sites appearances land in positions one to four, from 61% in France to 76% in Spain and Italy |
| Part of your product visibility runs through third-party catalogs | Third-party catalogs are supplied separately from Merchant Center, directly or through partners |
| Coverage returned to its previous level | 38% below baseline on 16 September, level with the 53,035 baseline on 30 September |
What is still open
Three questions would change this advice if they resolved differently.
- Whether the supplier unit, Google's separate section for direct sellers, appears on product queries at all. No capture in this collection shows it.
- How Google ranks the services inside the section. We have not located documentation.
- Where clicks from the section are reported in Search Console and Merchant Center. We have not located documentation.
More from this series
See the rest of the Weekly AI & Search Insights series.
For more on the grid removal and the Google Shopping lead, read EEA Product Grid Is Gone: Google Shopping Still Leads.
For the access and rendering checks behind machine-readable product pages, read our guide to AI agents.
BrightEdge tracks product visibility across search and AI surfaces. See how your products appear in the markets that changed with Data Cube X, or request a demo.
Google AI Overviews vs ChatGPT: Half of ChatGPT's Holiday Citations Point to Pages Marketing Does Not Own
Help and policy pages make up 12.5 times the share of citation weight on ChatGPT that they do on Google AI Overviews. Every retailer in the pull moves that way. Black Friday is 27 November.
This edition compares two AI surfaces, Google AI Overviews and ChatGPT, on holiday shopping prompts. We pulled the top 50 cited rows per retailer on each engine, across four major US retailers. Both engines were filtered to the same holiday terms. Then we pulled the prompts themselves.
What this measures: This measures which pages each engine cites as sources for holiday questions. It does not measure what the answers say, and it does not measure clicks. Citation weight counts page citations, so a prompt that cites two newsroom posts counts twice. Every share in this edition is a share of citation weight. A share of distinct prompts is a separate pull and would give different numbers.
Shoppers bring different questions to each surface
Half of ChatGPT's top holiday prompts are logistics questions. On Google AI Overviews, 28% are logistics questions and 72% are product and deal queries.
Google AI Overviews gets keyword strings such as black friday tv deals and store hours thanksgiving. ChatGPT gets full sentences such as Is the store open on Thanksgiving? and What time does Black Friday start?
The average ChatGPT holiday prompt runs 6.0 words against 4.4 on Google AI Overviews. A keyword product query is answered by a category page. A logistics question is answered by a press release or a help article.
Each engine receives different questions and cites different pages, so each needs its own measurement.
Each engine cites a different mix of page types
| Page type | Google AI Overviews | ChatGPT | Owner in a large retail organization | Higher share on |
| Commercial pages | 64.6% | 35.4% | Marketing and merchandising | Google AI Overviews 1.8x |
| On-site search results | 9.7% | 0.1% | Ecommerce platform | Google AI Overviews 91.1x |
| Newsroom posts | 17.2% | 40.7% | Communications | ChatGPT 2.4x |
| Buying and how-to guides | 7.5% | 12.9% | Marketing | ChatGPT 1.7x |
| Help and policy pages | 0.9% | 10.8% | Customer support | ChatGPT 12.5x |
Share of holiday citation weight by page type, Google AI Overviews against ChatGPT. Source: BrightEdge AI Hyper Cube. ChatGPT and Google AI Overviews, United States, June to August 2026. Four of six panel retailers, with both engines matched at the top 50 rows per domain, so both engines are compared at the same depth. Ratios use unrounded shares, so they differ slightly from ratios computed on the rounded values shown. Page owners are our characterization of a large retail organization. The shares are measured.
The last column names the engine with the higher share. ChatGPT gives more citation weight to newsroom posts, guides and help pages. Google AI Overviews gives more to commercial pages and on-site search results. Both engines cite all five types.
Commercial pages and on-site search results make up 74.4% of Google AI Overviews holiday citations and 35.5% of ChatGPT citations. Newsroom posts, guides and help pages make up 64.5% of ChatGPT citations and 25.6% of Google AI Overviews citations.
Two findings hold at every retailer in the pull. Commercial pages and on-site search results together run higher on Google AI Overviews for all four, by 10 to 53 percentage points. Help and policy pages run higher on ChatGPT for all four. The other three page types do not agree across all four. Those are panel averages, and the newsroom share on ChatGPT runs from 2% to 64%. Each retailer needs its own pull.
Pages owned outside marketing carry half of ChatGPT's holiday citations
In a large retail organization, marketing and merchandising own the commercial pages and guides. Those make up 72.1% of Google AI Overviews citations and 48.3% of ChatGPT citations. Communications and customer support own the newsroom and help pages, which make up 18.1% of Google AI Overviews citations and 51.5% of ChatGPT citations. On-site search results, owned by the ecommerce platform, make up the remaining 9.7% and 0.1%.
That changes who needs to be in the holiday planning meeting. On Google AI Overviews, updating the pages marketing owns covers most of the citations. On ChatGPT it covers about half.
Every retailer in the pull already has cited pages across at least four page types. Start by reviewing those cited pages for outdated information.
Example. Take an announcement post that carries last year's event date. If it is cited for the question of when a sale starts, anyone who opens it sees last year's date.
What this means for agentic commerce and AI shopping agents
These findings also matter for AI shopping agents. An agent needs four facts before it can buy: the sale date, the return window, the price-match terms and the shipping cutoff. Those four sit on newsroom posts and help pages, which carry 51.5% of ChatGPT's holiday citations.
The shopper typing a full sentence into ChatGPT today needs the same four facts an agent will need. Publishing them as pages a crawler can read gives both shoppers and AI systems more reliable information to work from.
On-site search results in Google AI Overviews call for a crawl and indexation check
Google AI Overviews cites retailers' own internal search result pages at 9.7% of its holiday citation weight. ChatGPT cites them at 0.1%. Two of the four retailers account for all of it, at 14.2% and 24.3%, and the other two show none. If a retailer's internal search pages appear in citations, the question for technical SEO is whether those pages should be crawled and indexed.
What to update before Black Friday
- Pull the cited-URL list for both engines. Group each list by directory and compare the two profiles. If they come back close to identical, check that the engine filter was applied before reading anything into the result.
- Share the ChatGPT list with the owners of those pages. The newsroom and help pages behind half of ChatGPT's citations sit with communications and customer support.
- Date every announcement and review last year's post. A cited announcement that carries last year's date shows that date to anyone who opens it. Sale start date, return window, price-match terms and shipping cutoff belong on pages a crawler can read.
- Update pages that already exist before commissioning new ones. Six weeks is a short window for new content to build visibility. Refreshing a page that is already live and already cited is the more practical priority.
- Plan around Google first and let the same page serve AI. Google still sends the traffic, so the commercial pages come first. They make up 64.6% of Google AI Overviews citations. Keep them current, then cover the newsroom, guide and help pages that make up 64.5% of ChatGPT citations.
How to check your holiday and agentic shopping visibility on both engines
Group the cited URLs by directory. In AI Hyper Cube, pull the cited-URL list for your holiday prompts and group it by directory. Each directory shows how much of the footprint comes from the newsroom, the help center and the guides.
Compare the two engines. Run the same pull on both and compare the two directory profiles. If they come back close to identical, confirm the engine filter was applied before acting on the result.
Size the organic footprint. Under the same question set, use Data Cube X to size the space before deciding how much to invest.
For the longer build program behind all of this, crawler access, product data and schema, see our guide to optimizing e-commerce for AI search.
Frequently asked questions
Does being cited mean I get the click?
This analysis does not measure clicks. It measures which pages are cited as sources.
Is this a share of prompts or a share of citations?
Citations. A prompt that cites two newsroom posts counts twice, so every share is a share of citation weight. A share of distinct prompts is a different pull and would give different numbers.
Should we stop investing in the Black Friday hub?
No. The hub sits inside the commercial pages that Google AI Overviews cites most, at 64.6%, and Google still sends the traffic. The finding is about which other page types carry the answer on ChatGPT.
How does this change what we do for agentic shopping?
It names the pages. An AI shopping agent needs the sale date, the return window, the price-match terms and the shipping cutoff. Those sit on newsroom and help pages, so those pages carry the agentic commerce work.
Why are the shares based on four retailers?
The page-type pull covers four of the six panel retailers, and the shares describe those four. They do not describe the other two.
Does this hold on other engines?
The pull covers ChatGPT and Google AI Overviews. Other engines are untested.
How current is this?
It reads June to August 2026. Holiday prompts run all year, so the pages cited in the summer are the pages already published going into November.
Technical methodology
| Field | Value |
| Data source | BrightEdge AI Hyper Cube |
| Engine | ChatGPT and Google AI Overviews |
| Market | United States, English |
| Period | June to August 2026 |
| Panel | Four of six panel retailers, pulled 14 October 2026 |
| Holiday prompts | Prompt text contains black friday, cyber monday, holiday, christmas or thanksgiving |
| Prompt mix | Top holiday prompts on each engine, grouped as logistics questions or product and deal queries, with average words per prompt |
| Metric | Citation weight. A prompt that cites two pages of a type counts twice, so every share is a share of citation weight. Shares of distinct prompts are not reported |
| Sampling | Top 50 rows per domain by BrightEdge Volume on each engine. Pages outside those rows are not counted, so every total is a floor |
| Classification | Page type assigned by URL pattern |
| Engine comparison | Same holiday term filter and same months on both engines, matched at the top 50 rows per domain. The prompt populations returned under that filter differ by engine, which is itself a finding of this edition. This is not an identical prompt panel run twice |
| Page ownership | BrightEdge characterization of which team owns each page type in a large retail organization. Ownership is not measured |
| What a citation means | A page was linked as a source. BrightEdge does not store ChatGPT's answer text, so answer accuracy is not measured |
| Buckets | Assigned from the URL alone: newsroom (corporate, news, press), guides (how-to and buying guides), help and policy, on-site search and commercial for everything else. Commercial includes category pages, product pages and event hubs. No hub-against-category judgment is used |
| Not included | Overall citation volume per engine, branded against unbranded prompts and pre-season growth multiples |
Key takeaways
| Finding | The number that proves it |
| Communications and customer support own the pages behind half of ChatGPT's citations | 51.5% of ChatGPT holiday citations against 18.1% on Google AI Overviews |
| The two engines cite different mixes of page types | Commercial pages and on-site search: 74.4% of Google AI Overviews citations and 35.5% of ChatGPT citations. Newsroom, guides and help pages: 64.5% of ChatGPT citations and 25.6% of Google AI Overviews citations |
| Help pages and on-site search show the widest gaps | Help and policy pages: 10.8% on ChatGPT against 0.9%, or 12.5x. On-site search: 9.7% on Google AI Overviews against 0.1%, or 91.1x, from two of four retailers |
| Two findings hold at every retailer | Commercial plus on-site search runs higher on Google AI Overviews for all four, by 10 to 53 points. Help and policy pages run higher on ChatGPT for all four. The other three page types do not agree across all four |
| The newsroom is the largest page type on ChatGPT | 40.7% of ChatGPT holiday citation weight, against 17.2% on Google AI Overviews |
| Google still sends the traffic, so commercial pages come first | Commercial pages hold 64.6% of Google AI Overviews citations |
More from this series
See the rest of the Weekly AI & Search Insights series. For the build side of the same problem, read our guide to optimizing e-commerce for AI search.
BrightEdge tracks which pages ChatGPT and Google AI Overviews cite for your brand. Find out which holiday pages each engine cites for you before Black Friday with AI Hyper Cube, or request a demo.
Before Black Friday, Update the Pages ChatGPT Already Cites
In this data, page age does not decide what ChatGPT cites. About 1 in 10 cited holiday pages carries a year that has already passed.
Dated press releases take 71.7% and 63.1% of Black Friday citations at the two retailers whose newsrooms carry the event. Their current store hubs take 10.5% and 13.3%. Nothing ages a page off the source list, so it stays there until someone updates it. The pages sit on the retailers' own sites, and Black Friday on 27 November leaves about seven weeks.
We went looking for stale pages in a long tail of neglect. At two retailers they are the most-cited Black Friday pages there are.
AEO and AI Overviews: An E-Commerce Optimization Guide covers what to build: crawler access, product data and schema, on a six-month runway. This edition covers what to update on pages that already exist, and that work fits in the seven weeks left.
We read holiday prompts that cite six major US retailers in AI Hyper Cube and checked which of the cited pages carry a year that has already passed.
What this measures. Every figure counts pages that ChatGPT linked as sources in the United States from June to August 2026. The newsroom, store hub and URL figures use August 2026 and each retailer's top 25 cited URLs. We do not store ChatGPT's answer text, so the data shows which pages it cites and says nothing about what it wrote.
ChatGPT answers an undated question with last year's announcement
9 of the 10 highest-volume prompts that cite a 2025 holiday announcement name no year. Someone asks when Black Friday starts, and ChatGPT answers with the announcement. Shoppers are sent to the announcement, so it is the page to keep current.
Where newsrooms carry Black Friday, press releases earn more citations than store hubs
At two of the retailers, newsroom posts take 71.7% and 63.1% of Black Friday citations and store hubs take 10.5% and 13.3%. A press release keeps one permanent address. A seasonal hub page gets retitled or replaced each year.
Citations split across many URLs
Every retailer in the analysis has at least 25 distinct Black Friday URLs cited. We read the top 25 per retailer, so these are minimums. Tracking-coded and email-campaign copies of the same hub show up as separate URLs, so one hub's citations spread across many URLs. Consolidating the copies puts them on one page.
A permanent hub and current guides keep dated pages under 5%
| Measure | Share of holiday prompts citing a dated page |
| All six retailers, weighted | 11.0% |
| Best Buy | 4.2% |
| Home Depot | 1.8% |
A dated page is one with a year from 2015 to 2025 in its URL. Source: BrightEdge AI Hyper Cube. ChatGPT, United States and English, June to August 2026.
- Best Buy. One permanent hub URL carries Black Friday every year. It holds 37.6% of Best Buy's Black Friday citations on its own and 63.0% with its variants. Its newsroom is cited only lightly for Black Friday. Its dated-page share is 4.2%. About a quarter of its Black Friday citations go to tracking-coded copies of the same hub, so consolidating those copies puts that share back on the hub.
- Home Depot. Its buying guides are current and detailed on specs, linked to collections with FAQ blocks, and its newsroom is cited mostly for current posts. Its dated-page share is 1.8%.
Black Friday pages are cited months before the event
ChatGPT cites Black Friday pages between June and August. We left out a growth multiple for that period, because part of the rise comes from prompts we added to the tracked set. The pages cited through the summer are likely the ones still cited in November. Nothing in this data suggests that age moves a page down the list. October is the time to update them, and a change made in the last week of November arrives late.
| Now | October | Last week of November | 27 November |
| Find the dated pages in your cited-URL list | Update cited pages that carry a past year and retitle evergreen pages | A change that lands here arrives late | Black Friday |
No retailer is a top source for gift-idea prompts
None of the six retailers is among the 15 most-cited sources for gift-idea prompts. Reddit, Good Housekeeping and Forbes lead that list. Where a gift prompt does cite a retailer, the page is a help page about receipts, registries or returns. No retailer holds a spot in that list, so a crawlable gift guide has room to earn one.
What marketers need to know
- Update cited pages that carry a past year, starting with newsroom posts. They take most Black Friday citations where a newsroom carries the event. Refresh each one or point it to this year's version.
- Keep one hub URL per event. Point the variants, tracking-coded copies and email-campaign URLs at one canonical hub.
- Retitle evergreen pages for the current year before October ends.
- Put this year's dates on the store hub. Add direct-answer FAQs for hours, early access, price matching and returns. A press release keeps its original date, so the hub is where this year's dates belong.
- Check holiday policy and help pages too. Gift-card help, coupons, price match, returns and store hours all get cited, so they need the same year check as the hub.
Google still sends the traffic. AI search is where the answer gets assembled before anyone clicks. Work both surfaces, starting with Google, because one canonical and current hub serves them together. These five updates fit in the seven weeks left. Build work needs a longer runway, so plan it for next season. Start with AEO and AI Overviews: An E-Commerce Optimization Guide. A crawlable gift guide belongs on that list.
How to check this for your own site
Find the dated pages. In AI Hyper Cube, pull the cited-URL list for your holiday prompts and sort it by URL. Any URL with a year that has passed goes on your work list.
Count the URLs for your biggest event. In the same list, count the distinct URLs for that event. If the same hub appears under more than one URL, consolidate before you create anything new.
Size the organic footprint. Use Data Cube X to size the organic footprint under the same question set, so you know how much to invest.
Frequently asked questions
Does this mean ChatGPT is giving shoppers wrong information?
The data shows which pages ChatGPT cites. A citation puts an older page on the source list, and whether the answer repeats its details is a separate check.
Which retailers does this cover?
Six major US retailers. We report the category and name only the two examples of current practice.
Should retailers stop publishing newsroom posts?
No. At two retailers, newsroom posts are among the pages ChatGPT cites most for Black Friday. The work is to keep each post current or point it to this year's version.
How was a dated page identified?
We looked for a year from 2015 to 2025 in the URL. A manual check found about 80% of matches genuinely dated, and the misses were email tracking codes carrying a year-like string. Pages that are old without carrying a year in the URL are not detected at all, so 11.0% is a floor.
Why is there no growth figure for pre-season citations?
Part of the rise comes from prompts added to the tracked set, so a multiple would overstate real growth.
Does this hold on other engines and for other retailers?
This covers six major US retailers on ChatGPT through August 2026. Other engines and other retailers are untested and worth checking separately.
How does this edition relate to AEO and AI Overviews: An E-Commerce Optimization Guide?
The guide covers what to build for AI search: crawler access, product data, schema and off-site signals, on a six-month runway. This edition covers what to update on pages already published, on a runway of about seven weeks. Run this audit first, because the pages are already published and already cited.
Technical methodology
| Field | Value |
| Data source | BrightEdge AI Hyper Cube |
| Engine | ChatGPT |
| Market | United States, English |
| Period | June to August 2026 |
| Panel | Six major US retailers, 13,915 holiday prompts |
| Holiday prompts | Prompt text contains black friday, cyber monday, holiday, christmas or thanksgiving |
| Fragmentation analysis | Black Friday prompts, August 2026, top 25 cited URLs per retailer, so URL counts are minimums |
| Gift prompts | Prompt text contains gift, excluding gift-card questions |
| Dated page test | URL contains a year from 2015 to 2025 in a date path or hyphenated name |
| Detection accuracy | A manual check found about 80% of matches genuinely dated, and the misses were email tracking codes carrying a year-like string. Pages that are old without carrying a year in the URL are not detected at all, so 11.0% is a floor. |
| What a citation means | A page was linked as a source. BrightEdge does not store ChatGPT's answer text, so answer accuracy is not measured |
| Counting | A prompt citing two retailers counts once for each |
| Newsroom share | The portion of a retailer's Black Friday citations, among its top 25 cited URLs, that goes to its newsroom posts |
| Weighted share | Each retailer's dated share weighted by its prompt volume, across 13,915 holiday prompts |
| Left out | Pre-season prompt growth multiples, because part of the rise comes from prompts added to the tracked set |
Key takeaways
| Finding | The number that backs it |
| AI citation shows no recency discount in this data | Dated press releases take five to seven times the citations of current store hubs |
| ChatGPT cites pages regardless of age | About 1 in 10 holiday prompts cites a page tied to a past year, 11.0% weighted across the six retailers |
| Shoppers ask without a year | 9 of the 10 highest-volume prompts citing a 2025 announcement name no year |
| Where newsrooms carry Black Friday, press releases earn more citations than store hubs | Newsroom posts 71.7% and 63.1%, store hubs 10.5% and 13.3% |
| One permanent hub holds citations together | Best Buy: 37.6% alone, 63.0% with variants |
| Current guides and hubs keep dated pages low | Home Depot 1.8%, Best Buy 4.2% |
| Citations split across many URLs | At least 25 distinct Black Friday URLs per retailer, as minimums |
| No retailer is a top source for gift-idea prompts | None of the six is among the 15 most-cited sources |
Download the full report
Get the full breakdown, or browse the rest of the Weekly AI & Search Insights series. For the build side of the same problem, read AEO and AI Overviews: An E-Commerce Optimization Guide.
BrightEdge tracks brand citations across ChatGPT, Google AI Overviews, Google AI Mode, Perplexity and Gemini. You can pull your own cited-URL list before the season starts in AI Hyper Cube, or request a demo.
Insurance AI Citations: ChatGPT Cites Insurers on Branded Questions Only
Government domains hold the definitional and coverage citations. Branded and HR questions are still open to insurers.
Government domains and clinical references hold every link on definitional and coverage questions in a tracked Insurance prompt panel. An insurer's own domain is the cited source in one question type out of four. Two of the four carry ownable ground.
Almost every insurance content calendar has a line on it like what is short-term disability insurance. Is that line worth the money? We stayed inside one vertical and asked one question: where is there ground an insurer can actually hold.
We took a tracked Insurance prompt panel, grouped it by what the question actually asks, and read the cited domains and the mentioned brands for each group in AI Hyper Cube and AI Catalyst. Four groups came out of it. An insurer's own domain is the cited source in exactly one of them: branded queries, where the customer has already typed the company name.
The map, and the verdict for each question type
Three different owners hold the citation set for unbranded insurance questions, and which one shows up depends entirely on what the question asks. The fourth group belongs to the brand.
| Question type | Who gets the link | Why | Verdict |
| Definitional and compliance | Government domains | Regulatory authority holds it | Hold for the mention |
| Drug and procedure coverage | Official and clinical references | Specialization, and narrowing further | Hold for the mention |
| Workplace and HR benefits | Job and HR platforms | No moat. Won on content quality | Invest. A real push |
| Branded and named queries | The brand's own domain | Nobody else can hold it | Defend. Best return |
All four question types in this panel are listed here. Scope is one tracked panel over these weeks. Source: BrightEdge AI Hyper Cube and AI Catalyst. A tracked Insurance prompt panel, ChatGPT and Google AI Overviews, United States, one-month and 12-week comparisons to 20 September 2026.
Nobody is going to outrank the IRS on what a deductible is. That is not a content problem. No budget fixes it. The better question is where the ownable ground sits, and the data points at two places.
What we analyzed
We read two outcomes separately for the same prompts over the same weeks. A citation is the linked source under an answer. A mention is the brand named in the answer text. They are two different outcomes, counted separately, and they do not move together, which is why one visibility score hides the result.
Prompts were grouped by what the question asks. Definitional and compliance questions ask what something is or what the rules are. Workplace and HR benefits questions ask about retention, culture and employee cost. Drug and procedure coverage questions ask whether a specific treatment is covered. Branded questions name a company.
Data collected
| Field | Value |
| Capability | BrightEdge AI Hyper Cube and AI Catalyst |
| Engines | ChatGPT and Google AI Overviews |
| Vertical | Insurance |
| Panel | An anonymized panel of tracked Insurance prompts. Domains shown are the public sources appearing in AI answers. They do not identify the panel |
| Market | United States |
| Period | One-month and 12-week comparisons to 20 September 2026 |
| Metrics | Share of citations by domain, and mentioned-brand rank |
| Comparison basis | Same tracked prompts at both dates, absolute shares, never indexed |
Key finding
Measured. Definitional and compliance questions cannot be won, the what-is-a-deductible and what-does-the-law-require kind. Government domains hold 4 of the top 8 cited, up from a mixed pool of job sites, publishers and legal aggregators 12 weeks earlier. healthcare.gov rose from 19.2% to 40.4% of ChatGPT citations over one month. legalclarity.org fell from 8.8% to 3.4%. Both movements appear in the tracked panel and in a wider prompt set pulled for comparison.
Measured. ny.gov rose from 1.6% to 8.0% of citations on ChatGPT and from 23.6% to 29.3% on Google AI Overviews. This is the one movement in the analysis confirmed on both engines, which is why it carries the most weight here.
Measured. Branded questions run the other way entirely. When a query names the company, the company's own domain is the source cited. That held in every group checked, without exception.
Measured. Insurer domains hold a place in the mentioned top three for the vertical, alongside healthcare.gov and dol.gov, across the same weeks government domains take the citations.
We expected insurers to disappear from those two areas altogether. They did not: insurer domains hold a place in the mentioned top three in the same weeks government domains dominate the citation set, which means the link and the answer are two separate contests, and a brand can lose one while holding the other.
Inference, labeled as such. Tightly query-matched content in a closed question type appears to earn the mention even where it cannot earn the citation. The mention data is measured. The causal link to content is not, and it is the first thing to test.
Source: BrightEdge AI Hyper Cube and AI Catalyst. A tracked Insurance prompt panel, ChatGPT and Google AI Overviews, United States, one-month and 12-week comparisons to 20 September 2026.
Drug and procedure coverage is closing further
Drug and procedure coverage questions are the does-my-plan-cover-this-treatment kind. They moved further in the same direction over the month, and the split is clean enough to be worth staring at. Every domain gaining citation share is official or single-purpose. Every domain losing share is general-purpose consumer health content.
| Domain | Share of ChatGPT citations | Direction |
| drugs.com | 20.6% | Gaining |
| nih.gov | 19.1% | Gaining |
| medlineplus.gov | 6.5% | Gaining |
| fda.gov | 4.4% | Gaining |
| mayoclinic.org | 3.5% | Losing |
| clevelandclinic.org | 3.2% | Losing |
| healthline.com | 3.0% | Losing |
| goodrx.com | 2.0% | Losing |
| webmd.com | 1.4% | Losing |
These are the top movers in this panel, ranked within each direction. Scope is one tracked panel over these weeks. Source: BrightEdge AI Hyper Cube. A tracked Insurance prompt panel, ChatGPT, United States, one-month comparison to 20 September 2026.
No insurer appears among the top movers in either direction. That group is narrowing even for the non-insurers already inside it.
The one you already win: branded and named queries
Branded queries are already held and the work is defensive. The specific gap is content answering does [brand] cover [drug or procedure], in a format that answers the question directly on the brand's own site.
Winning here displaces nobody. Someone has already decided to ask about you, so the only job left is being the complete, well-structured answer when they arrive. That is a far smaller problem than out-authoring a federal agency. Treat it as defensive infrastructure and budget it that way.
One caution, because this is where budgets quietly leak. There is no observed spillover. Publishing more generic definitional content does not appear to build toward branded citations at all. The two draw from different source pools entirely.
The one worth buying into: workplace and HR questions
A separate cluster of prompts inside the same tracked group cites Indeed, Glassdoor, SHRM, Gallup, Workday, AIHR and BuiltIn. None of those domains overlap with the government cluster or the clinical cluster.
There is no regulatory moat here. Indeed and SHRM hold this ground because their content is good, which is the whole point: ground held on quality can be taken. For an insurer selling group or employee benefits, the HR lead searching retention benchmarks on a Tuesday afternoon is your buyer, one step before you normally meet them.
Competing here means publishing content that works as genuine HR guidance. Calculators, benchmarking data and retention research qualify. Product marketing carrying an HR label does not.
Where the weighting changes
The split holds across every question type checked in this panel, and the weighting does not. Definitional and compliance questions are the most closed, with 15 or more distinct government domains appearing across the group. Coverage questions are closing further. Workplace questions stay open on quality. Branded questions are held by the brand.
Which of the four dominates your prompt mix decides how hard to lean. Pull the split first. Setting a content budget without it is guessing with a spreadsheet open. This covers one vertical on a tracked Insurance prompt panel. Whether the same split by question type holds in other regulated categories is untested and worth checking separately.
What marketers need to know
- Audit branded coverage content first. Someone is typing does [brand] cover [drug] into ChatGPT while you read this, and when a query names the company, the company's own domain is what gets cited. Go and check whether that page exists on your site in a format a machine can lift. Best return, least risk, shortest list of excuses.
- Decide whether HR content is a business you want to be in. No regulatory moat sits behind it. You would be competing with Indeed, Glassdoor, SHRM and Gallup on content quality, which is winnable and expensive. Calculators, benchmarking data and retention research qualify. Product marketing with an HR label on it does not, and everyone can tell the difference.
- Measure mentions separately from citations. Insurer domains hold a place in the mentioned top three while government domains take 4 of the top 8 cited. Keep tightly matched content in those two and report it as mention share in AI Catalyst, separately from citation share.
- Stop budgeting generic content as AI-citation growth. Definitional content is up against regulatory authority. Coverage content is up against official health references sitting at 20.6% and 19.1%. An insurer closes neither gap. Keep the content, because it still earns organic traffic and on-site conversion, and move the line item out of the AI-citation column.
- Google is still the channel to plan around. The ny.gov movement shows up on Google AI Overviews as well as ChatGPT, which is the tell. The canonical, specific content that earns organic visibility is the same content that gets a brand named in an AI answer, so it is built once and works on both surfaces.
How to check this for your own category
Path one. In AI Hyper Cube, pull the cited-domain list for your tracked prompts and group it by what the question asks. The owner changes by group, and that grouping is the whole exercise.
Path two. In AI Catalyst, read mention share beside citation share for the same weeks. Where the two diverge is where a single visibility score is hiding a result.
Path three. For the organic footprint underneath the same question set, use Data Cube X to size the space before you decide how hard to lean.
Frequently asked questions
What changed in how AI answers unbranded insurance questions?
The cited sources consolidated toward official domains. Government domains now hold 4 of the top 8 cited in the vertical. healthcare.gov alone went from 19.2% to 40.4% of ChatGPT citations in a month.
Can an insurer win the citation for definitional questions?
Plan as though the answer is no. 15 or more distinct government domains appear across that question group, and every week of the last twelve moved further toward them.
What is the difference between a citation and a mention?
A citation is the linked source under an answer. A mention is the brand named in the answer text. They are two different outcomes, counted separately, and they do not move together.
Which question type is worth the investment?
Branded and named queries, where the brand's own domain is already the cited source, and workplace and HR questions, which have no regulatory moat and are won on content quality.
Is this specific to ChatGPT?
Most of it is measured on ChatGPT. The ny.gov movement appears on Google AI Overviews as well, from 23.6% to 29.3%.
Does this hold outside Insurance?
This covers one vertical on a tracked Insurance prompt panel. Whether the same split by question type holds in other regulated categories is untested and worth checking separately.
Technical methodology
| Field | Value |
| Data source | BrightEdge AI Hyper Cube and AI Catalyst |
| Engines | ChatGPT and Google AI Overviews |
| Vertical | Insurance, tracked non-branded and branded prompts |
| Market | United States |
| Period | One-month and 12-week comparisons to 20 September 2026 |
| Measurement | Share of citations by domain, and mentioned-brand rank, read separately |
| Grouping | Prompts grouped by what the question asks |
| Comparison basis | Same tracked prompts at both dates, absolute shares, never indexed |
| Corroboration | healthcare.gov, legalclarity.org and ny.gov each confirmed in two sources. ny.gov confirmed on both engines |
| Panel | An anonymized panel of tracked Insurance prompts. Domains shown are the public sources appearing in AI answers. They do not identify the panel |
| Anonymization | Shares and ranks only. No prompt counts and no panel sizes |
| Limits | One vertical on one tracked panel. Each engine is measured on its own prompt set, so engines are compared by direction only |
Key takeaways
| Finding | The number that proves it |
| An insurer's own domain is the cited source in one question type of four | Branded queries. The other three are held by government, job platforms and clinical references |
| Definitional questions are held by regulatory authority | Government domains hold 4 of the top 8 cited, up from a mixed pool over 12 weeks |
| The largest single domain shift is healthcare.gov | 19.2% to 40.4% of ChatGPT citations in one month |
| One government riser is confirmed on both engines | ny.gov 1.6% to 8.0% on ChatGPT, 23.6% to 29.3% on Google AI Overviews |
| Coverage questions are closing further | drugs.com 20.6% and nih.gov 19.1% gaining, webmd.com 1.4% losing |
| Brands stay in the answer text where they lose the link | Insurer domains in the mentioned top three alongside healthcare.gov and dol.gov |
| Google is still the channel to plan around | The same specific, authoritative content supports organic visibility and gives AI systems stronger material to name the brand |
Download the full report
Download the full breakdown, or see the rest of the Weekly AI & Search Insights series.
BrightEdge measures brand mentions and citations across ChatGPT, Google AI Overviews, Google AI Mode, Perplexity and Gemini. You can see which group your category's questions sit in before a competitor builds around it. Request a demo.
The B2B Tech Shortlist Is Tightening Where Buyers Start
ChatGPT named 28% fewer brands per answer in B2B Tech in September 2026 than it did in March. The decline concentrates at the top of the funnel.
BrightEdge referral data shows AI search volume still climbing. Against that, a shorter list of brands per answer means each named slot is worth more than it was six months ago.
This edition covers the B2B Tech vertical. The panel holds the same non-branded prompts constant across two dates six months apart. Movement in the numbers reflects how ChatGPT answers changed. What was asked stayed the same. Usage and answer quality can both climb while the named list gets shorter. Measured in AI Catalyst.
What brand mentions measure, and what they do not
Mentions per answer counts how many distinct brands ChatGPT names in a single response, averaged across the tracked prompt set for a funnel stage. It is not citation volume, and it is not market share. A single answer can name many brands or very few, so the count moves independently of how many sources get cited for the same answer.
Source: BrightEdge AI Catalyst. A fixed panel of tracked non-branded B2B Tech prompts, ChatGPT engine, held constant across 15 March 2026 and 13 September 2026.
| Term | Definition |
| Mentions per answer | The average number of distinct brands ChatGPT names in a single answer, for a given funnel stage. |
| Change | The difference in that average between the two dates. |
| Sum across brands | One answer can name several brands, so this counts how many brands appear alongside each other in a single answer, separate from any measure of exclusive market share. |
Where the list got shorter
Where a prompt sits in the buyer's journey now decides how short the list gets. The panel stayed fixed. The prompts stayed fixed. Only the answers changed. Every figure below covers prompts that held the same intent classification on both dates. On those prompts ChatGPT named 5.36 brands per answer in March against 3.87 in September, a 27.9% decline. The fall concentrates at the top of the funnel.
Figures are the fixed-cohort cut: every prompt that carried the same intent classification on both dates. Source: BrightEdge AI Catalyst. A fixed panel of tracked non-branded B2B Tech prompts, ChatGPT engine, held constant across 15 March 2026 and 13 September 2026.
Data collected
| Funnel stage | Mar-26 avg. brands/answer | Sep-26 avg. brands/answer | Change |
| All stages | 5.36 | 3.87 | -27.9% |
| Informational | 5.15 | 3.50 | -32.0% |
| Consideration | 8.21 | 6.39 | -22.1% |
| Transactional | 2.02 | 3.34 | Not read as a trend |
Post Purchase carries too few prompts to read as a trend and is excluded. Transactional is printed above and held out of the conclusions below, for the reason given in its own section.
| Field | Value |
| Capability | BrightEdge AI Catalyst |
| Engine | ChatGPT |
| Market | United States |
| Vertical | B2B Tech |
| Prompts | Tracked non-branded prompts only, matched exactly across both dates |
| Period | 15 March 2026 and 13 September 2026 |
| Metric | Mentions per answer, the count of distinct brands named in one response |
| Comparison basis | Same prompts both dates, absolute averages, never indexed |
| Anonymization | Shares and averages only. No prompt counts and no panel sizes |
The questions buyers start with got the most selective
Informational prompts are the broadest questions, such as what a technology is or how it works. They went from naming 5.15 brands per answer to 3.50, a 32.0% decline, the steepest fall of any stage.
Microsoft, Google, and Amazon lost the most ground, down 9.5, 6.7, and 6.4 points. A cluster of developer and data-infrastructure names lost ground alongside them: Apache, dbt, Snowflake, Elastic, and HashiCorp.
IBM gained the most, up 9.9 points. NIST.gov, TechTarget, FBI.gov, Cisco and FTC.gov gained too, so institutional and government sources moved up alongside a publisher. The expected publisher squeeze does not appear in this data.
Consideration became a shorter list
Consideration prompts are where someone is comparing named options, such as accounting software for a small business. They went from naming 8.21 brands per answer to 6.39, a 22.1% decline.
Google, Amazon, GitHub, Trend Micro, Apple, and GitLab lost the most ground, down 9.3, 6.1, 3.7, 3.3, 2.0, and 2.0 points.
Every brand gaining ground here is a single-purpose tool.
| Brand | March presence | September presence |
| Zoho | 8.5% | 12.8% |
| Wave Apps | 2.8% | 5.7% |
| SAP | 3.5% | 5.7% |
| Squareup | 2.8% | 5.0% |
| Malwarebytes | 1.4% | 4.3% |
| ProtonVPN | 2.1% | 4.3% |
| NordVPN | 2.1% | 4.3% |
| Kubernetes.io | 2.1% | 4.3% |
| ServiceNow | 1.4% | 3.5% |
| ClickUp | 1.4% | 3.5% |
| ESET | 0.7% | 2.8% |
| Terraform.io | Not present | 2.1% |
Why buying-intent prompts are held back
Transactional prompts are where someone is ready to buy. They moved differently over the same window. A third measurement point shows that movement reversing, so the stage is held out of this edition's conclusions until the full weekly series is in. Both figures are printed above, so the omission is visible.
Two dates can show a direction that a third date takes away. So we waited, and printed the figures anyway.
Everything else in this edition holds at every measurement point checked.
Mentions and citations do not always move together
The relationship between how many brands get named and how many sources get cited is not consistent across the funnel.
In Informational, citations per answer rose from 2.30 to 3.12 even as mentions fell. Fewer brands were named, and each was backed by more sources.
In Consideration, citations fell in step with mentions, from 5.70 to 3.25.
In Transactional, citations stayed close to flat, from 1.92 to 1.84, while mentions rose.
What marketers need to know
- Fight for the winnable Consideration prompts. Pull Consideration-intent prompts for your category in AI Catalyst or AI Hyper Cube, then check where you already show up. Every brand gaining ground here is a single-purpose tool. Find the use case your product owns, and build content that answers that exact question.
- Audit where you appear stage by stage. A single visibility score hides which stage you are missing from. Split your tracked prompts by intent and find the stage where you are absent, because being absent from a stage is a different fix from ranking low inside it.
- Hold your top-of-funnel investment. Awareness answers hold their value. They just got harder to win, and the goal there is now earning a place on a shorter list. Pull awareness prompts for your category in AI Catalyst. Identify one to three where you have a right to win but do not appear, then prioritize those.
- Google is still the channel to plan around. The canonical, specific content that earns organic visibility is also what gets a brand named in an AI answer. Build it once and it works on both. Re-run this funnel comparison quarterly, because funnel-stage presence keeps moving.
How to check this for your own brand
Path one. Open Mentions, filter to your tracked B2B Tech prompt groups, and split by funnel stage. Compare two dates six months apart to see whether your category shows the same shift. Do it in AI Catalyst.
Path two. In AI Hyper Cube, pull the mentioned-brand list for your category across funnel stages for the cross-engine, brand-anchored view.
One caveat. A category with very few Consideration or Transactional prompts will not show a clean trend either way. This check is most useful where your category has enough tracked prompts at each funnel stage to compare, as B2B Tech does here.
Frequently asked questions
What changed in how ChatGPT answers B2B Tech questions?
Over six months ChatGPT named fewer brands per answer, and the decline concentrated at the top of the funnel. Overall presence fell 27.9%, from 5.36 to 3.87 brands per answer.
Which funnel stage lost the most brand presence?
Informational, the broadest and earliest-stage questions, fell 32.0%, from 5.15 to 3.50 brands per answer.
What happened at the buying-intent stage?
Transactional moved differently and is not reported as a finding here. A third measurement point shows that movement reversing, so the stage is held until the full weekly series is complete.
Does this mean publishers are losing ground to owned content?
The data does not support it. TechTarget gained ground in Informational over the same period, and other major publishers stayed flat. That pattern does not carry a publisher-versus-owned-content story.
Is this specific to ChatGPT?
Yes. This measurement is ChatGPT only. Whether Google AI Overviews and AI Mode follow the same funnel-stage pattern is untested and worth checking separately.
How reliable is the funnel-stage classification?
About 15% of prompts were reclassified into a different intent stage between the two dates. Every figure in this edition uses the fixed cohort instead: only prompts that carried the same classification on both dates. Reclassification therefore cannot explain the result.
Technical methodology
Measurement: mentions per answer, the count of distinct brands named in a single ChatGPT response, averaged across the tracked prompt set for each funnel stage.
Panel: tracked non-branded B2B Tech prompts on the ChatGPT engine, matched exactly across 15 March 2026 and 13 September 2026. Every prompt is present in both periods.
Classification: each prompt is assigned a funnel stage by intent. About 15% of prompts were reclassified between the two dates. The headline figures use the fixed cohort, meaning only prompts that held the same stage on both dates.
Cross-check: the same comparison run across all prompts at each date's current classification gives a 25.1% overall decline, against 27.9% on the fixed cohort. Brand-level movements quoted here are computed on all prompts at each date.
Scope: ChatGPT only. Whether the same funnel-stage pattern holds on Google AI Overviews or AI Mode is untested. Google remains the larger channel and the one to plan around.
Key takeaways
| Finding | The number that proves it |
| ChatGPT names fewer brands per B2B Tech answer overall | 5.36 to 3.87 brands per answer, a 27.9% decline |
| The decline concentrates where buyers start | Informational fell 32.0%, Consideration fell 22.1% |
| Consideration's gainers are single-purpose tools | Zoho rose from 8.5% to 12.8% presence, the largest gain in that stage |
| Mention volume and citation volume do not move together | Informational citations rose from 2.30 to 3.12 per answer even as mentions fell |
| Government and standards sources gained, and so did one publisher | NIST.gov up 8.1 points, TechTarget up 6.9 points |
| Google is still the channel to plan around | The content that earns organic visibility is what gets a brand named in an AI answer |
Two Weeks After Reddit's ChatGPT Collapse: What Replaced It in Education
Reddit's citation presence in ChatGPT fell from 17.2% to zero across two weeks in August 2026. The fall itself was widely reported. What replaced Reddit in Education citations was not, and that is what this edition measures.
Nothing about the content changed. Reddit changed its robots.txt, and every citation gain built on being crawled went with it. A source that had answered one in six Education questions in ChatGPT stopped appearing.
This series has been tracking Reddit's presence in AI citations closely, including an edition on 13 August covering Reddit's rise in search visibility. What follows is what happened in the two weeks after.
Six domains moved into the space inside a week. Two of them were gone again by week 37. The two weeks after the collapse are the useful part, measured in AI Catalyst.
What citation presence measures, and what it does not
Citation presence is the share of tracked prompts that cite a domain at least once. It is not share of citation volume, and it is not market share. A single AI answer cites several domains, so presence figures across domains add up to more than 100%. Reading them as a pie will produce the wrong conclusion.
| What it is | What it is not | |
| Citation presence | Share of tracked prompts citing the domain at least once | Share of total citations made |
| Movement | Change in that share between weeks | Change in a domain's traffic or rank |
| Sum across domains | Exceeds 100%, because one answer cites several sources | A market-share table |
Source: BrightEdge AI Catalyst. ChatGPT only, a fixed weekly panel of tracked Education prompts, United States, July to September 2026.
The collapse, week by week
| Week | Dates | Education panel | Account-wide |
| W28-33 | Jul 6 - Aug 16 | 17.2% | 9.0% |
| W34 | Aug 17-23 | 3.3% | 4.5% |
| W35 | Aug 24-30 | 0.0% | 0.5% |
| W36 | Aug 31 - Sep 6 | 0.2% | 1.6% |
| W37 | Sep 7-13 | 0.0% | 0.1% |
Source: BrightEdge AI Catalyst. ChatGPT only, a fixed weekly panel of tracked Education prompts, United States, July to September 2026.
Presence held steady for six weeks, then fell 81% in a single week and reached zero the week after. The Education panel fell further than the account-wide measure. That is what you would expect in Education, where Reddit already sat near the top of the cited set.
What we analyzed
A fixed weekly panel of tracked Education prompts in ChatGPT, measured every week across the same prompts. Because the panel does not change, week-to-week movement reflects the engine's behavior. What was asked stayed the same.
Data collected
| Field | Value |
| Capability | BrightEdge AI Catalyst |
| Engine | ChatGPT |
| Panel | A fixed weekly set of tracked Education prompts |
| Market | United States |
| Period | Week 28 to week 37, 2026 |
| Metric | Citation presence, the share of tracked prompts citing a domain at least once |
| Comparison basis | Same prompts every week, absolute presence, never indexed |
| Corroboration | Timing match between the account-wide drop and the robots.txt change, detailed in the methodology |
Key finding
reddit.com citation presence in the Education panel fell from 17.2% to 3.3% to zero across two weeks in August 2026. Account-wide, the same measure fell from about 9% to 0.5%. The inflection lands in the same week Reddit's robots.txt change took effect.
The panel is fixed, so this corroborates the mechanism behind the drop. It does not prove it. What the data can show is the timing and the size of the drop, and both match when the robots.txt change took effect.
Reddit did not fall on its own
| Domain | Before | After |
| coursera.org | 25.4% | 6.0% |
| indeed.com | 22.8% | 7.6% |
| forbes.com | 18.3% | 4.5% |
| reddit.com | 17.2% | 0.0% |
| collegeboard.org | 12.9% | 3.1% |
Source: BrightEdge AI Catalyst. ChatGPT only, a fixed weekly panel of tracked Education prompts, United States, July to September 2026.
Community sources and general commercial publishers receded together. Coursera lost 19 points of presence, Indeed 15 and Forbes 14. Reading the event as a Reddit story alone misses that other sources fell in the same window.
What replaced them was narrower and more institutional. Government sites, a university, and professional associations moved into the top set in the same two weeks.
Not everything that moved in stayed in
| Domain | What happened |
| onetonline.org | Spiked +589% in the week of the collapse, receded by week 37 |
| careeronestop.org | Spiked +346% in the week of the collapse, receded by week 37 |
| state.gov | Entered and held position through week 37 |
| asu.edu | Entered and held position through week 37 |
| apa.org | Entered and held position through week 37 |
| aacnnursing.org | Entered and held position through week 37 |
Source: BrightEdge AI Catalyst. ChatGPT only, a fixed weekly panel of tracked Education prompts, United States, July to September 2026.
The two biggest immediate movers did not hold. The four that held are government, university and professional-association domains. So are the two that faded. onetonline.org and careeronestop.org are both Department of Labor properties. Some institutional sources held and others did not, so domain type alone does not explain durability. Anyone who rebuilt a strategy on the first week's leaderboard rebuilt it on noise.
One name in the new top set is a trap. bls.gov did not grow at all. It was already third before the collapse at 21.2% presence, and it became first because everything around it fell faster. Rising in a ranking and gaining presence are different events.
This was a ChatGPT-specific event
| Engine | Reddit citation movement, same window |
| ChatGPT | About 86% relative decline |
| Google AI Mode | About 31% decline |
| Google AI Overviews | About 11% decline |
Source: Promptwatch via Search Engine Journal, 19 August 2026; Forbes and Gizmodo, 20 August 2026.
A one-engine read would have told a marketer their Reddit strategy had failed everywhere. It had not. Google's surfaces declined gradually across the same window while ChatGPT fell off a cliff, which is why the cross-engine view matters before anyone acts.
Reddit carried a trait the model wanted
Reddit's high citation rate became a playbook of its own. Teams seeded threads in order to be cited and treated presence on the platform as the objective. The trait the model actually wanted was first-hand, specific, unpolished answers. That content already existed on Reddit.
When the channel closed, it closed through an access policy. Content quality was not the reason. Everything built on it disappeared inside two weeks, and no warning was available to anyone optimizing for it. Reddit-based visibility was never a durable asset.
Some of the domains that moved in held position through week 37 and some did not. Both of the domains that spiked and faded are Department of Labor properties, so institutional status alone does not explain which sources stayed.
Citation share earned through one platform's willingness to be crawled is rented. Visibility built on a third-party platform is exposed to that platform's access decisions. Build the underlying expertise and canonical content on a domain you control. Run one test against your top cited sources. Does the citation exist because of what you are, or because a platform currently allows it to be crawled.
What marketers need to know
One. Build the trait, not the placement. What the model rewarded on Reddit was first-hand, specific, unpolished detail. Replicating that on a domain you control takes original data, named practitioners, and direct experience. Publish the material only you have.
Two. Quick wins from one platform's indexing behavior are fragile, whoever the platform is. Ask whether your current AI citation gains would survive a crawler-policy change tomorrow, and assume you would get no notice.
Three. Wait for the second week before crowning a replacement. The biggest immediate movers here did not hold, and two institutional domains faded alongside them. One week of leaderboard movement is not a trend.
Four. Google is still the channel to plan around. The canonical, specific content that earns organic visibility is also easier for a model to recommend by name. Build it where no third party's access policy can remove it.
How to check this for your own brand
Path one. In AI Catalyst, open Citations, filter the domain to reddit.com and scope to your tracked prompt groups. Pull the weekly trend. A single snapshot will not show it. You are looking for a steady baseline followed by a sudden break. A slope will not produce that pattern.
Path two. In AI Hyper Cube, pull the cited-domain list for reddit.com across your category for the brand-anchored, cross-engine view. That is where you compare Google AI Overviews and AI Mode against ChatGPT.
Three things to look for. Whether your category's Reddit presence collapsed in the same week or whether this is specific to Education. Which domains gained presence in the same window, and whether they held into a second week or spiked and faded. Whether your brand already has a foothold in whatever filled the gap.
One caveat. A category where Reddit had a low baseline will not show a dramatic story. This check is most useful where Reddit already sat in the top three or top five cited domains, as it did here.
Frequently asked questions
What happened to Reddit citations on ChatGPT?
Reddit's presence in ChatGPT citations fell sharply in the second half of August 2026. Public trackers reported a fall from 3.8% to 0.5% of ChatGPT Search citations account-wide, an 86% relative decline (Source: Promptwatch via Search Engine Journal, 19 August 2026). The change is attributed to Reddit blocking crawler access through robots.txt.
When did it happen?
The break lands in the week of 17 August 2026, with presence reaching zero in the Education panel the following week.
What replaced Reddit in Education specifically?
Government, university and professional-association domains. state.gov, asu.edu, apa.org and aacnnursing.org entered the top set and held position. Two others, onetonline.org and careeronestop.org, spiked hardest at the moment of collapse and then receded.
Is this permanent?
Unknown. The outcome depends on an access decision. Content has nothing to do with it. The measurable point is that a policy change removed a source in two weeks, and that is the risk worth planning around.
Does this mean brands should stop trying to get cited on Reddit?
It means a Reddit citation should not be the objective. What made Reddit useful to the model was specific, first-hand detail, and that kind of detail is harder to manufacture on an owned domain. Replicating it takes original data, named practitioners, and direct experience.
Was Reddit's high citation rate ever a reliable quality signal?
It was a signal about access and content type. Reddit's own authority as a source never entered into it. That distinction is what the collapse made visible.
How can I check whether this happened in my own industry?
Follow the two paths in the section above. Pull the weekly trend in AI Catalyst and the cross-engine view in AI Hyper Cube.
Technical methodology
Measurement: citation presence, the share of tracked prompts citing a domain at least once. This is not share of citation volume. Presence across domains sums past 100% because one answer cites several sources.
Engine: ChatGPT. Market: United States. Period: week 28 to week 37, 2026. Panel: a fixed weekly set of tracked Education prompts, held constant so week-to-week movement reflects engine behavior.
The series is plotted as absolute presence and is never indexed to a baseline week. A short series indexed to one week makes every later movement a function of that week.
Attribution. The panel is fixed and cannot observe cause directly. The inflection lands in the same week Reddit's robots.txt change took effect. That timing supports the mechanism. It does not prove it.
Scope. One category, one engine, one account's tracked panel. Directional for Education. It is not a claim about every category, and the account-wide comparison is included so the reader can see the difference.
Every figure quoted anywhere in this edition is a share or a change in a share. We publish no raw citation counts and no panel sizes.
Key takeaways
| Finding | The number that proves it |
| Reddit's ChatGPT citations in Education collapsed to zero | 17.2% presence to 3.3% to zero across two weeks |
| An access change caused the drop, unrelated to content quality. | The break lands in the week the robots.txt block took effect |
| It was a ChatGPT-specific event | About 86% decline in ChatGPT against about 11% in AI Overviews |
| Reddit did not fall alone | Coursera 25.4% to 6.0%, Indeed 22.8% to 7.6%, Forbes 18.3% to 4.5% |
| Half the replacements did not hold | onetonline.org and careeronestop.org spiked, then receded by week 37 |
| Rank movement is not presence movement | bls.gov became first without growing, from 21.2% presence |
| Visibility on a third-party platform is exposed to that platform's access decisions | reddit.com fell from 17.2% presence to zero in two weeks through a robots.txt change, with no change to the content |
Google AI Mode Cites Itself 4.5x More Than AI Overviews. Your Brand Can Still Be Winning.
google.com accounts for 44.9% of AI Mode citations and 9.9% of AI Overviews citations, a 4.5x gap that has held for eight months.
Ask Google AI Mode for an American Airlines stock price and it answers with a ticker. Ask it for things to do in Orlando and it answers with a local panel. Neither answer reads like a list of links, because neither one is. Both are assembled out of surfaces Google already owns.
That construction shows up in the citation data as Google citing itself. Across a tracked prompt set in AI Hyper Cube, google.com accounts for 44.9% of the citations AI Mode makes. In AI Overviews the same measure is 9.9%.
What Google AI Mode is, and how it differs from AI Overviews
Google AI Mode is a conversational search surface. It answers a query in full rather than returning a ranked list of links. AI Overviews is the AI summary that sits above the classic results page. Both are Google. They construct an answer in different ways, and that difference is what this edition measures.
| Google AI Overviews | Google AI Mode | |
| What the user sees | A summary above a ranked list of links | A conversational answer, often built around a module |
| How the answer is assembled | Largely from outbound sources, cited individually | More often from Google's own rich-result surfaces |
| google.com as a share of citations, August 2026 | 9.9% | 44.9% |
| Same measure, January 2026 | 3% | 35% |
Source: BrightEdge Insights from AI Hyper Cube. A tracked prompt set covering consumer product and finance queries, United States, January to August 2026.
The gap is eight months old, not eight days
Google confirmed in August 2026 that it routes outbound search clicks through its own redirect layer. The timing is coincidental. In January 2026, before any of it, AI Mode was already citing google.com in 35% of its citations against 3% in AI Overviews. The spread was 32 points then. It is 35 points now.
A change confirmed in August does not explain a gap that was already 32 points wide in January. The direction is wrong for it too. Both surfaces have moved upward across the eight months, together.
The redirect layer applies to organic result links, which is a different measurement surface from an AI citation. BrightEdge tracks both, so a click routed through a redirect still resolves to the destination in Data Cube X rather than disappearing from the report.
What we analyzed
A BrightEdge tracked prompt set covering consumer product and finance queries, run against Google AI Mode and Google AI Overviews in the United States. For each engine we took google.com as a share of all citations that engine made, at four observation points between January and August 2026.
The measure is deliberately a share rather than a count. A count moves whenever prompt coverage moves, which makes any two periods incomparable. A share does not.
Data collected
| Observation point | Google AI Mode | Google AI Overviews | Spread, percentage points |
| January 2026 | 35% | 3% | 32 |
| June 2026 | 45% | 12% | 33 |
| July 2026 | 48% | 11% | 37 |
| August 2026 | 44.9% | 9.9% | 35.0 |
Source: BrightEdge Insights from AI Hyper Cube. google.com as a share of citations, United States.
Plotted as absolute share and never indexed to a baseline period. Indexing a short series to one observation point makes every later movement a function of where that point happened to sit.
Key finding
google.com accounts for 44.9% of Google AI Mode citations and 9.9% of Google AI Overviews citations, a multiple of 4.5x. The gap has held for eight months and widened slightly, from 32 points to 35. AI Mode is assembling more of its answers from rich-result surfaces Google owns. The citation record then reflects the surface, and the brand sits inside it.
What it looks like one prompt at a time
Four example prompts show how it looks in practice. These four are an illustration and not a sample. The measurement is the share figure above.
| Prompt | AI Mode, cited domains | AI Overviews, cited domains |
| "fruit snacks" | google.com | walmart.com, welchsfruitsnacks.com, wikipedia.org |
| "things to do in orlando" | google.com | visitorlando.com, tripadvisor.com, neverstoptraveling.com, makingmyownlane.com |
| "local restaurants" | google.com | reddit.com, hotels.com |
| "american airlines stock price" | google.com | robinhood.com, tradingview.com, marketbeat.com |
Source: BrightEdge Insights from AI Hyper Cube. United States, August 2026.
The stock row is the sharpest. On "american airlines stock price" AI Mode returns google.com and nothing else. AI Overviews returns robinhood.com, tradingview.com and marketbeat.com for the same question in the same week. One engine answers out of a ticker module. The other sends the reader to the sites that publish prices.
The pattern holds across all four. A retail query, a travel query, a local query, a finance query. On every one, AI Mode answers from a Google surface and AI Overviews cites outbound sources.
BrightEdge replicated each prompt to identify a set that returns consistently, because an AI Mode answer can vary between sessions. Every prompt in the stable set returned google.com on AI Mode, so the table shows no counter-example.
Assorted local blogs and restaurant sites also appeared on the local restaurants prompt and are not listed individually.
This is rich results, extended into the answer
Rich results are not new. Product grids, price comparison strips, stock tickers, fare and hotel modules and local packs have shaped the classic results page for years. A search-literate reader already knows them, already optimizes for them, and already measures them.
AI Mode extended those same surfaces into a conversational answer at a scale AI Overviews did not reach. That reframing matters because it changes the response. A new and opaque ranking behavior would leave a brand with nothing to do. An extension of rich results means the brand already has the checklist.
It concentrates where modules already carry the classic page. Product comparison and shopping queries, local discovery, and financial rate and price lookups.
Why eCommerce and Travel see this first
| Category | Existing rich-result footprint in classic Search | What that means in AI Mode |
| eCommerce | Product grids, price comparison, review stars, availability | The deepest module inventory to extend into. Highest chance a win is recorded as a module citation |
| Travel | Fare modules, hotel panels, date and price grids | Same shape as retail. Rates and availability sit in a module rather than on a page |
| Finance | Rate tables, stock tickers, currency modules | Rate lookups answer from a module. Advice and explanation queries still cite publishers |
| Healthcare and B2B | Thinner module coverage | Answers still assemble from outbound sources, so citation counts read more directly |
Source: BrightEdge. Category assessment based on rich-result coverage in classic Search.
A brand in eCommerce or Travel is the most likely to be reading a decline that is not there. It is also the most likely to have a quick win available. The inputs that govern module eligibility are the ones those teams already maintain.
How marketers win in AI Mode
Some categories are already dominated by specific rich results. Publishing, ecommerce, travel, finance. In those, your opportunity to improve visibility and selection is the same as it is in traditional search. Optimize for the listing type that is winning.
In eCommerce and Travel that means product feed quality, supporting schema, and differentiated content on your pages. Three inputs. They win you AI Mode and the traditional results page at the same time. We would expect them to matter less inside AI Overviews, which draws on content already ranking.
For publishing and finance it means entity ownership. Authoritative commentary written by real people, carrying data that is not widely available and not generated by AI. Supporting schema again underneath it.
What marketers need to know
- A low AI Mode citation count is not proof of lost visibility. Read it next to your presence in the rich results the answer is built from. google.com accounts for 44.9% of AI Mode citations and 9.9% of AI Overviews citations. That is one brand measured against two constructions.
- eCommerce and Travel see this first. These are the categories where rich results already carry the most weight in classic Search. That existing infrastructure is what AI Mode extends into.
- Audit the three inputs you control. Product, Offer and Review schema quality decides eligibility for the modules AI Mode draws from. Feed completeness on pricing, availability, GTINs and imagery populates those same surfaces. Crawlability and indexation decide whether the data is eligible at all. Every one of those is checkable this week, which a ranking model is not.
- Google is still the channel to plan around. Strengthen the structured data that already earns rich results in classic Search. The same schema and the same feed serve the classic result and the AI Mode answer. Fix once, and both surfaces improve.
Frequently asked questions
- What is Google AI Mode?
Google AI Mode is a conversational search surface that answers a query in full rather than returning a ranked list of links. It sits alongside AI Overviews, which is the AI summary above the classic results page. Both are Google, and they assemble an answer differently. - Why does Google AI Mode cite google.com so often?
Because AI Mode builds more of its answers out of Google's own rich-result surfaces, such as product grids, price comparison strips and rate tables. When the answer comes from one of those modules, the citation records the module. google.com accounts for 44.9% of AI Mode citations against 9.9% in AI Overviews. - Is this caused by Google's search click redirect layer?
No. Google confirmed the redirect layer in August 2026, and the gap measured here was already 32 points wide in January 2026. The redirect layer also applies to organic result links, which is a different measurement surface from an AI citation. - Does a low AI Mode citation count mean my brand is losing visibility?
Not on its own. In categories where rich results carry the page, a brand can win a position inside the module without appearing as a citation. Check presence in the rich results alongside the citation report before reading it as a decline. - What controls whether my brand appears inside those rich results?
Three inputs. Product, Offer and Review schema quality. Feed completeness and accuracy on pricing, availability, GTINs and imagery. General technical health, meaning crawlability, indexation and page-level signals. A brand controls all three and can audit them. - Which categories are most affected?
eCommerce and Travel, because those are the categories where rich results already have the deepest footprint in classic Search. Finance rate and price lookups show the same pattern. Healthcare and B2B technology have thinner module coverage, so citation counts there read more directly.
Technical methodology
Measurement: google.com as a share of all citations made by each engine. Engines: Google AI Mode and Google AI Overviews. Market: United States. Period: four observation points between January and August 2026. Prompt set: a BrightEdge tracked set covering consumer product and finance queries.
The series is plotted as absolute share and is never indexed to a baseline observation point. A short series indexed to one period makes every later movement a function of that period. A flat trend can then read as a step change.
Replication. AI Mode answers vary between sessions. Each prompt was run repeatedly, and BrightEdge kept only the prompts that returned a consistent result.
The four-prompt table is an illustration of the mechanism, not a sample. No conclusion in this edition rests on it. Every figure quoted anywhere in this edition is a share of citations or a spread in percentage points. We publish no raw citation counts and no sample sizes.
Key takeaways
| Finding | The number that proves it |
| Google AI Mode cites google.com far more than AI Overviews does | 44.9% of AI Mode citations against 9.9% of AI Overviews citations, a 4.5x multiple |
| The gap predates the August redirect news | 32 points wide in January 2026, 35 points in August 2026 |
| The mechanism is rich results, not suppression | On "american airlines stock price" AI Mode answers from a ticker module while AI Overviews cites three finance sites |
| It holds across retail, travel, local and finance | All four example prompts show the same split between the two surfaces |
| The fix sits in inputs a brand controls | Schema quality, feed completeness and technical health govern rich-result eligibility |
Download the full report
The downloadable edition carries all three figures, the full prompt-level table and the methodology. It is the version to send to your search, merchandising and feed leads.
Find out how your brand appears across AI Mode, AI Overviews and the classic result. Request a demo.
Explore more in our Weekly AI Search Insights series.
Pull your category's cited-domain list in AI Hyper Cube. Track your own citation share week over week in AI Catalyst. Compare it against your organic and rich-result footprint in Data Cube X. Check how AI crawlers reach your pages in AI Agent Insights.